<?xml version="1.0" encoding="utf-8"?>

<feed xmlns="http://www.w3.org/2005/Atom" >
  <generator uri="https://jekyllrb.com/" version="3.10.0">Jekyll</generator>
  <link href="https://www.kuniga.me/feed.xml" rel="self" type="application/atom+xml" />
  <link href="https://www.kuniga.me/" rel="alternate" type="text/html" />
  <updated>2026-09-11T19:05:57+00:00</updated>
  <id>https://www.kuniga.me/feed.xml</id>


    <title type="html">NP-Incompleteness | </title>


    <subtitle>Kunigami&apos;s Technical Blog</subtitle>


    <author>
        <name>Guilherme Kunigami</name>
      
      
    </author>


    <entry>
      

      <title type="html">Linux Memory Reclamation</title>
      <link href="https://www.kuniga.me/blog/2026/09/11/memory-reclaim.html" rel="alternate" type="text/html" title="Linux Memory Reclamation" />
      <published>2026-09-11T00:00:00+00:00</published>
      <updated>2026-09-11T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/09/11/memory-reclaim</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/09/11/memory-reclaim.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/shared/tux.svg" alt="Tux mascot" height="100" />
</figure>

<p>For most operating systems, when memory usage grows beyond what the hardware can support, the kernel starts swapping, i.e. moving data from memory to disk. In this post, we’ll study how the Linux kernel does this, as part of the more general memory reclamation process. We’ll also cover the memory allocation flow, because memory reclamation is just one part of it, one of the unhappy paths.</p>

<p>First, we’ll go over the different components involved, and then how they fit together in the memory allocation flow and then memory reclamation via swap and zswap.</p>

<div style="clear: both"></div>

<!--more-->

<h2 id="concepts">Concepts</h2>

<h3 id="pages">Pages</h3>

<p>A page is a chunk of contiguous memory. We’ll assume an x86-64 Linux configuration and that a page is 4KB ($2^{12}$ bytes). A page can be virtual (a chunk of virtual memory) or physical (a chunk of physical memory). To avoid ambiguity, we’ll assume a page is virtual and denote a physical page as a <strong>page frame</strong>.</p>

<p>Pages are useful because that’s the minimum granularity the kernel supports in terms of allocation.</p>

<h3 id="virtual-memory">Virtual Memory</h3>

<p>When a process is created, it gets its own <strong>virtual address space</strong>. In 64-bit systems it can theoretically represent $2^{64}$ bytes, but in practice the range is smaller due to how addresses are encoded.</p>

<p>We’ll talk about page tables later, but it suffices to know a virtual address is composed of 4-5 regions + offset. The regions identify the location of the page, and the offset is the distance from the start of that page. Each region supports 9 bits, and since a page has 4KB, we need 12 bits to address it, so a system with 5 regions can represent $5 \cdot 9 + 12 = 57$-bit virtual addresses.</p>

<p>When we use syscalls like <code class="language-plaintext highlighter-rouge">mmap()</code> or <code class="language-plaintext highlighter-rouge">brk()</code>, the kernel reserves a range of the virtual address space, called a <strong>Virtual Memory Area</strong> (VMA), and returns the start of that virtual address range. This address is not backed by physical memory.</p>

<p>The list of VMAs is kept in a data structure called <a href="https://docs.kernel.org/core-api/maple_tree.html">Maple tree</a>. We won’t go over details, but it can efficiently determine the VMA of a given virtual address. We’ll call this structure the <strong>VMA tree</strong>.</p>

<p>There’s a special section of a process’ virtual address space which is reserved for the kernel, usually high addresses. The reason for this is so that kernel objects don’t need a special address space. They can use the same space as the process being executed.</p>

<h3 id="physical-memory">Physical Memory</h3>

<p>The physical memory is the RAM that you can actually write to. As we said, virtual memory is not initially backed by physical memory. This only happens when we write to it, which triggers a <strong>page fault</strong>, which causes the kernel to finally try to back the page being written to by a page frame. We’ll cover this flow in more detail later. The important part to note is that mapping virtual pages to physical pages is lazy.</p>

<p>Another important fact is that the kernel overcommits (analogous to overbooking in airlines). When multiple callers call <code class="language-plaintext highlighter-rouge">mmap()</code>, it won’t fail the call if the amount of virtual memory used exceeds the host or cgroup memory. That’s because the kernel knows that most of the time not all the requested memory will be used (think of <code class="language-plaintext highlighter-rouge">.reserve()</code> vs <code class="language-plaintext highlighter-rouge">.size()</code> in <code class="language-plaintext highlighter-rouge">std::vector</code>).</p>

<p>Recall that two different virtual addresses can map to the same physical one. For example, when we <code class="language-plaintext highlighter-rouge">fork()</code> a process, the child process inherits the addresses from the parent, including the mapping to physical memory. However, this is COW (copy-on-write): the moment one attempts to write, the contents are copied to a new location.</p>

<p>As we mentioned, the physical page is also 4KB and aligned to 4KB, so we can drop the 12 least significant bits when representing it. This representation is called a <strong>page frame number</strong> or PFN. The kernel maintains a structure with metadata on a <code class="language-plaintext highlighter-rouge">struct page</code> (ignore the contents for now):</p>

<figure class="highlight"><pre><code class="language-c" data-lang="c"><span class="k">struct</span> <span class="n">page</span> <span class="p">{</span>
    <span class="cm">/* ... */</span>
<span class="p">};</span></code></pre></figure>

<p>Conceptually, this struct lives in a giant array, <code class="language-plaintext highlighter-rouge">vmemmap</code>, and the PFN is an index in this array. So if we want to access the metadata for a given PFN, we do <code class="language-plaintext highlighter-rouge">vmemmap + PFN</code>.</p>

<p>Note that because this is a struct that lives in the kernel, it’s subject to the same memory layout: it’s divided into virtual pages that are mapped to physical pages, which have metadata in <code class="language-plaintext highlighter-rouge">vmemmap</code>. There’s some degree of circularity that can be mind-bending.</p>

<h3 id="page-table">Page Table</h3>

<p>The mapping from virtual to physical memory is kept in a structure called a <strong>page table</strong>. Conceptually, it’s a map from the 57-bit virtual address (see <em>Virtual Memory</em>) to a 64-bit number, encoding the physical address. Because we can drop 12 bits of the physical address (due to 4KB alignment), we can reuse them for metadata / flags.</p>

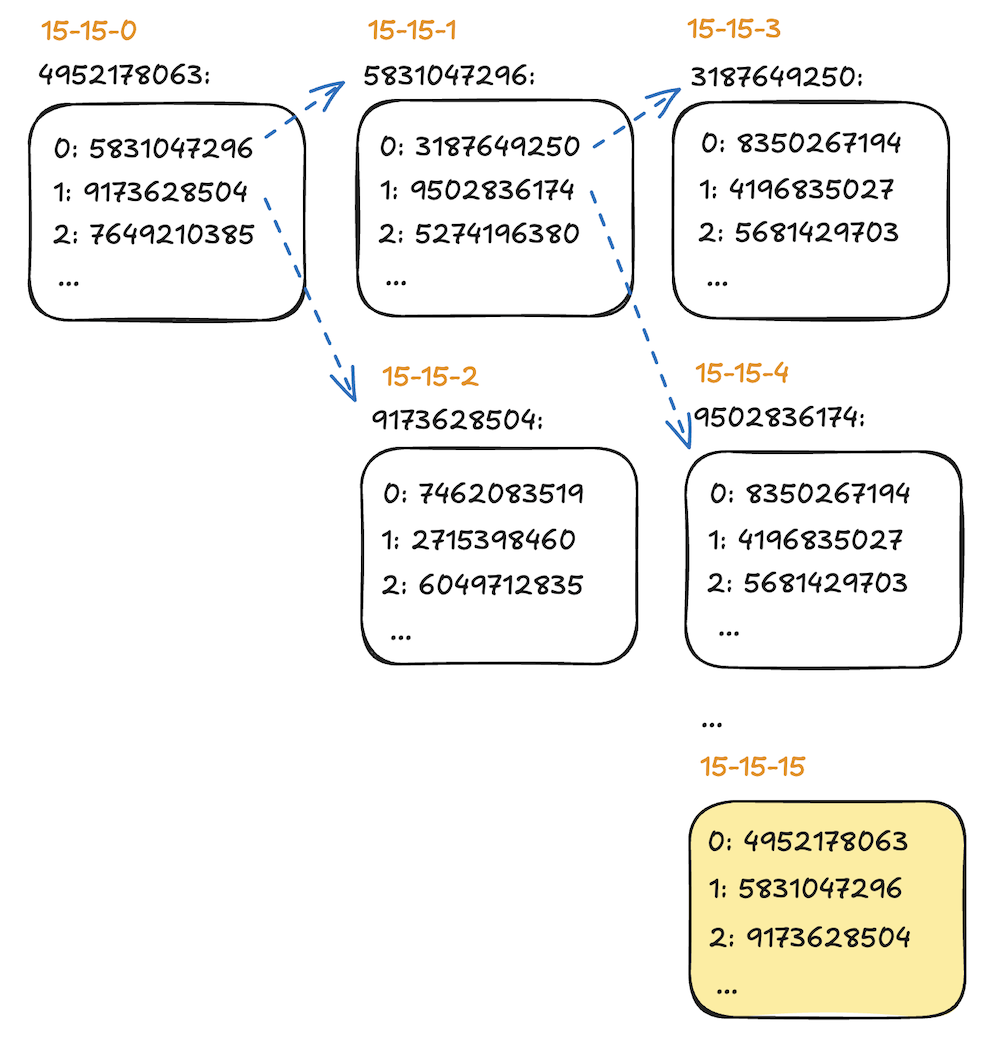
<p>The problem with storing all virtual page mappings in a single contiguous array is that this would have to be mapped to a similarly gigantic array in the physical memory. Instead, we use an n-ary tree where each node is a page. The “regions” we mentioned in <em>Virtual Memory</em> are each level of this tree, so for 5 regions the tree has depth 5.</p>

<p>Each internal node has 512 entries pointing to the 64-bit physical address of the children nodes. Each leaf node contains 512 entries of the 64-bit physical address, which are the mappings for the virtual addresses. But which virtual address? Recall that a virtual address has 5 parts that identify the virtual page + an offset. Each of these parts corresponds to the entry index in a given node.</p>

<p>For example, if we have the parts <code class="language-plaintext highlighter-rouge">41, 121, 5, 203, 57</code>, this tells us: in the root, get the physical address at entry <code class="language-plaintext highlighter-rouge">41</code> and navigate to that child. Then do the same for entry <code class="language-plaintext highlighter-rouge">121</code> and so on. After following <code class="language-plaintext highlighter-rouge">203</code>, we’ll arrive at the appropriate leaf. Now we look up the entry <code class="language-plaintext highlighter-rouge">57</code> and the corresponding physical address is the mapping for the virtual address <code class="language-plaintext highlighter-rouge">41, 121, 5, 203, 57</code>! So <code class="language-plaintext highlighter-rouge">41, 121, 5, 203, 57</code> is really a path on this tree (think of JSON paths).</p>

<p>The regions or levels in this tree have weird acronyms: PGD (root, <em>Page Global Directory</em>), P4D (level 1, <em>Page 4th-level Directory</em>), PUD (<em>Page Upper Directory</em>), PMD (<em>Page Middle Directory</em>), PTE (leaf, <em>Page Table Entry</em>). There’s one such structure per virtual address space, so simplistically, one per process.</p>

<p>Note that this structure grows on demand. If there’s only one entry, we’d have one node per region. When the 512 entries on the first leaf fill up, we add a new leaf, etc.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-09-11-memory-reclaim/page-table.png" alt="See caption" style="width: 600px;" />
  <figcaption>Figure 1. Nodes of a hypothetical n-ary tree with 3 levels. The orange values correspond to the virtual address where each part is the index for a corresponding node. The value under it is the physical address. If we want, for example, to find the physical address of the virtual address 0-1-2, we'll navigate this tree to the node 9502836174 and check the index 2, so 5681429703.</figcaption>
</figure>

<p>Note that the page table works directly with physical addresses, not virtual. This is very important because the CPU (see <em>TLB</em>) must be able to traverse this table and it has no knowledge of virtual addresses.</p>

<p><strong>Kernel.</strong> As we mentioned in <em>Virtual memory</em>, a portion of the process’ virtual address space is reserved for the kernel. Since the mapping is consistent across processes, they can actually share the same “node” in the page table. In <em>Figure 1</em>, the yellow page contains addresses for the kernel virtual spaces. So different processes would have their own page table, but they would “point” to this same yellow node.</p>

<p><strong>Bootstrapping.</strong> Note that the nodes themselves are pages, so their addresses must be in the page table! In <em>Figure 1</em>, the yellow node contains the mapping for the other nodes. For example, <code class="language-plaintext highlighter-rouge">15-15-1</code> maps to <code class="language-plaintext highlighter-rouge">5831047296</code>.</p>

<p>This creates an interesting problem: how are the first nodes added to this tree? When the kernel is bootstrapped, it can initialize a minimal table with some pages pre-mapped.</p>

<h3 id="zones">Zones</h3>

<p>Zones are partitions of the <em>physical</em> address space. Typically, there are 3 zones: <code class="language-plaintext highlighter-rouge">ZONE_DMA</code> for low addresses (less than 16MB), <code class="language-plaintext highlighter-rouge">ZONE_DMA32</code> for the 32-bit address space (less than 4GB), and <code class="language-plaintext highlighter-rouge">ZONE_NORMAL</code> for the rest. These exist for legacy reasons; for example, <code class="language-plaintext highlighter-rouge">ZONE_DMA32</code> is needed to support devices limited to 32-bit addresses. For hardware using NUMA, there’s at least one zone per NUMA node.</p>

<p>The partition of addresses to zones is fixed: we cannot transfer pages between them. It is possible to copy pages between zones and the kernel might do it outside of the memory reclamation process.</p>

<h3 id="buddy-allocation">Buddy Allocation</h3>

<p>The <em>Page Table</em> stores the mapping from virtual to physical, but how does it decide which physical page to map to? The kernel uses an implementation of the <a href="https://www.kuniga.me/blog/2020/07/31/buddy-memory-allocation.html">Buddy Memory Allocation</a>, which is also used by the <a href="https://www.kuniga.me/blog/2025/07/15/jemalloc.html">Jemalloc Memory Allocator</a>.</p>

<p>We don’t need to go into the details of the algorithm, except that each zone has its own buddy allocator and its “domain” is pretty much the entire physical address space of that zone. The minimum granularity of the allocator is 4KB, i.e., one physical page, which is typically what the page fault trigger requests. The kernel might ask for larger chunks for other purposes.</p>

<p>The buddy allocator knows how much free memory it has.</p>

<h3 id="tlb">TLB</h3>

<p>TLB stands for <strong>Translation Lookaside Buffer</strong>, and it’s a cache that exists in the CPU. When the CPU executes instructions, the addresses it sees in registers are in virtual space. So if it’s to read and write data to/from memory, it needs to resolve the physical address.</p>

<p>This is an expensive operation, so it caches entries in the TLB. We mentioned TLB in the context of <a href="https://www.kuniga.me/blog/2020/04/24/cpu-cache.html">CPU Cache</a>. If it gets a cache miss, it needs to traverse the page table from the PGD node, which can be done with 5 lookups (one per level). Note that this process doesn’t involve the kernel.</p>

<h3 id="folio">Folio</h3>

<p>A folio is a sequence of contiguous physical pages. The crazy thing is that a <code class="language-plaintext highlighter-rouge">struct folio</code> is compatible with a <code class="language-plaintext highlighter-rouge">struct page</code>. For example, suppose PFN 10 is the head of a sequence of physical pages. Then if we do:</p>

<figure class="highlight"><pre><code class="language-c" data-lang="c"><span class="kt">void</span> <span class="o">*</span><span class="n">X</span> <span class="o">=</span> <span class="p">(</span><span class="kt">void</span> <span class="o">*</span><span class="p">)(</span><span class="n">vmemmap</span> <span class="o">+</span> <span class="mi">10</span><span class="p">);</span>
<span class="k">struct</span> <span class="n">page</span> <span class="o">*</span><span class="n">p</span> <span class="o">=</span> <span class="p">(</span><span class="k">struct</span> <span class="n">page</span> <span class="o">*</span><span class="p">)</span><span class="n">X</span><span class="p">;</span>
<span class="k">struct</span> <span class="n">folio</span> <span class="o">*</span><span class="n">f</span> <span class="o">=</span> <span class="p">(</span><span class="k">struct</span> <span class="n">folio</span> <span class="o">*</span><span class="p">)</span><span class="n">X</span><span class="p">;</span></code></pre></figure>

<p>Here <code class="language-plaintext highlighter-rouge">p</code> represents a <code class="language-plaintext highlighter-rouge">struct page</code>, but the bytes in memory can also represent a <code class="language-plaintext highlighter-rouge">struct folio</code>.</p>

<h3 id="mglru">MGLRU</h3>

<p>MGLRU stands for <strong>Multi-Generational Least Recently Used</strong>. It’s a structure that can tell which mapped pages are more suitable to be swapped. It’s similar to an LRU cache, but it cannot afford to keep the LRU order up-to-date like a user-space structure such as <a href="https://www.kuniga.me/blog/2026/08/28/cachelib.html">CacheLib</a> can. It actually stores folios (a run of pages), not individual pages.</p>

<p>It uses an interesting algorithm based on generations. Whenever a page is accessed, the CPU sets a bit in the corresponding entry in the PTE (recall it has 12 bits for metadata).</p>

<p><strong>Aging.</strong> Conceptually, when a request comes for reclaiming pages, it might decide to create a new generation node which contains a linked list. It scans all the pages and adds the ones with the bit set in the PTE to the list, setting the bit back to 0. The implementation is more clever: the <code class="language-plaintext highlighter-rouge">struct folio</code> has fields for making it a node in a doubly linked list, i.e., <code class="language-plaintext highlighter-rouge">prev</code> and <code class="language-plaintext highlighter-rouge">next</code> pointers to other folios (which is also what <a href="https://www.kuniga.me/blog/2026/08/28/cachelib.html">CacheLib</a> does), so it builds the list by changing these pointers.</p>

<p>Then the generation node points to the first “node”. We don’t create a new node every time a new generation is created: this structure is a circular queue or a ring buffer.</p>

<h3 id="kswapd">kswapd</h3>

<p>This is the kernel swap daemon. It’s actually an OS thread that sleeps until memory pressure wakes it up (see <em>Watermark</em>). It then tries to reclaim memory by asking the MGLRU to give it a candidate.</p>

<p>A reason I was given for it being a background thread that is idle / sleeping most of the time instead of being created on demand is that it’s mostly useful during memory pressure, and having to create a thread and allocate resources at that time is risky.</p>

<h3 id="watermark">Watermark</h3>

<p>The watermarks are actually thresholds, not like “highest value we’ve seen so far” as in <a href="https://www.kuniga.me/blog/2022/12/29/watermarks.html">stream processing</a>. There are three watermarks: high, low, min.</p>

<p>If the amount of free memory (see <em>Buddy Allocation</em>) drops below the low threshold, it wakes up the kswapd which tries to reclaim memory until the level goes above high (this is similar to the 2-threshold approach used by thermostats to avoid flapping on/off). This is the asynchronous path. On the other hand, if a thread would cause free memory to fall below min, it will be synchronously required to perform memory reclamation. We’ll cover this synchronous path as an example flow later.</p>

<h3 id="cgroups">cgroups</h3>

<p>So far we’ve only considered memory at a global level. However, cgroups are taken into account as well. At a high level, MGLRU has knowledge about cgroups, so memory pressure at individual cgroups can be taken into account to decide which pages to evict. So, for example, if we had two candidate pages that haven’t been accessed recently, we could look at their cgroup stats to make a decision.</p>

<p>Cgroups have the so-called <strong>interface files</strong> which are listed under <code class="language-plaintext highlighter-rouge">/sys/fs/cgroup/&lt;my_cgroup_path&gt;/</code>, and many of them are memory-related, such as <code class="language-plaintext highlighter-rouge">memory.current</code>, <code class="language-plaintext highlighter-rouge">memory.min</code>, <code class="language-plaintext highlighter-rouge">memory.low</code>, <code class="language-plaintext highlighter-rouge">memory.high</code> and <code class="language-plaintext highlighter-rouge">memory.max</code>. The easiest is <code class="language-plaintext highlighter-rouge">memory.current</code>, which corresponds to how much memory a given cgroup is using.</p>

<p>The file <code class="language-plaintext highlighter-rouge">memory.min</code> indicates the threshold for which memory is protected: the kernel will not try to reclaim memory from that cgroup if the resulting <code class="language-plaintext highlighter-rouge">memory.current</code> dips below that value. The threshold <code class="language-plaintext highlighter-rouge">memory.low</code> is similar, but it’s a soft limit: the kernel will avoid reclaiming memory for that cgroup, but if it can’t find any candidate cgroups, it will still reclaim memory.</p>

<p>Memory reclamation can happen at the cgroup level as well. When a task/thread for a given process causes <code class="language-plaintext highlighter-rouge">memory.current &gt;= memory.high</code>, this thread is synchronously required to reclaim memory. The thread might also be explicitly put to sleep (throttled) as a backpressure mechanism. If <code class="language-plaintext highlighter-rouge">memory.current &gt;= memory.max</code> and the thread cannot bring it down via reclamation, the OOM killer kills either the requesting process or the entire cgroup (depending on the <code class="language-plaintext highlighter-rouge">memory.oom.group</code> setting).</p>

<h2 id="flows">Flows</h2>

<p>Now that we covered the major components involved in memory reclamation, we can focus on a specific flow, starting with a page fault.</p>

<h3 id="page-fault">Page Fault</h3>

<p>As we discussed in <em>TLB</em>, when the CPU tries to execute an instruction accessing memory, it needs to resolve the physical address. It will first look in the TLB, then traverse the page table for that address.</p>

<p>If it doesn’t find it and it’s a read, it will raise a page fault exception. The kernel has a fault handler that then gets executed. The first thing it does is to determine if this virtual address is part of a valid VMA by looking it up in the VMA tree (see <em>Virtual memory</em>). If not, it throws a SIGSEGV (segmentation fault). Sometimes this is displayed as:</p>

<blockquote>
  <p>code: address not mapped to object.</p>
</blockquote>

<p>This can be misleading because “address not mapped to object” is essentially why a page fault happens, and that’s technically the “happy case”: the fault handler is expected to run. In a SIGSEGV, though, it won’t because this is not a valid VMA.</p>

<p>If it is a valid address, then it’s now that the mapping happens. If this is from user-space code, most likely the kernel will choose <code class="language-plaintext highlighter-rouge">ZONE_NORMAL</code>. The corresponding buddy allocator will attempt to give it a physical page.</p>

<p>If it succeeds, the page fault handler will add a new entry to the page table, based on the virtual address. It adds “nodes” to the table if they don’t exist already and returns. The CPU will retry the instruction and succeed this time.</p>

<p>Now let’s cover the scenario in which the amount of free physical memory falls below the <code class="language-plaintext highlighter-rouge">low</code> watermark.</p>

<h3 id="memory-reclamation">Memory Reclamation</h3>

<p>The first thing the kernel will do is to wake up the kswapd thread. The kernel will continue running and potentially executing other instructions.</p>

<p>As we mentioned, the kswapd will check MGLRU, which will look for its oldest generations. If it finds pages/folios there, it gives them back to kswapd. It might also create a new generation as part of this process (see <em>Aging</em> in <em>MGLRU</em>).</p>

<p>If this page/folio is file-backed (i.e., a cache of a file in memory), it first determines if it’s clean (i.e., it hasn’t been modified in memory). If not, it first needs to write it back to the file. If it’s clean, it can just remove the page and the necessary references. We will not cover this flow here.</p>

<p>Suppose the page/folio is not file-backed. If the system does not have swap enabled, it might invoke the OOM killer. Let’s consider the case in which swap is enabled.</p>

<h3 id="swap">Swap</h3>

<p>There are 2 sinks of swap: a partition and a file. A partition is a region of disk/flash that is dedicated for swap. Writing to it does not involve the file system. A file-based swap involves writing the page to the partition dedicated to the general filesystem. In practice, for modern Linux kernels the difference between these two is not very substantial, however. This process of writing to disk is called <strong>swap out</strong>.</p>

<p>Once a page is successfully copied to the appropriate swap region/device, the page is “returned” back to the corresponding buddy allocator. It must also be evicted from the TLB of every CPU core that might have it.</p>

<p>The swap is identified by the device type plus an offset. This identifier is then used in the page table, but the page is marked as not present, so if the CPU tries to read/write to this page, a page fault occurs. It then goes through the usual flow of requesting a physical page from the buddy allocator or trying to evict an existing page. Once it gets a new physical address, it writes to the page table and copies the contents from disk to that page; this process is known as <strong>swap in</strong>.</p>

<p>If every time a page is swapped in, it requires swapping out another page, the system is essentially using the disk as its RAM and performance degrades. This is called <strong>thrashing</strong>.</p>

<h3 id="zswap">Zswap</h3>

<p>At a high level, zswap intercepts pages about to be swapped and instead compresses them using encoders such as zstd (see <a href="https://www.kuniga.me/blog/2026/09/05/lz77.html">LZ77</a>) and keeps them in memory instead. Note that this is an implementation detail under the swap code, so from the perspective of callers, they don’t know that zswap exists. When a swap call happens, zswap runs the content of that page through zstd and writes the compressed data to a buffer.</p>

<p>Zswap has a dedicated memory allocator, called <strong>zsmalloc</strong>, which is in a way similar to a user-space allocator such as <a href="https://www.kuniga.me/blog/2025/07/15/jemalloc.html">jemalloc</a>. So after compressing the data, it requests that amount of memory from the allocator. If the request succeeds, it then copies the data there.</p>

<p>Zswap uses an index to map the swap identifier (device type, offset) to the virtual address where the compressed data ends up being stored, so if the time comes to swap in this page, zswap can look this data up, decompress it and go through the same process as if the data had been stored on disk.</p>

<p>The allocator zsmalloc can grow its memory dynamically, but it might determine at some point it’s too big, at which point it can fall back to regular swap.</p>

<h2 id="conclusion">Conclusion</h2>

<p>This is one of the posts where I started with a very simple question but ended up in a rabbit hole, which caused the post to be much longer but also allowed me to learn a ton in the process.</p>

<p>Dealing with memory is particularly tricky because the metadata about memory is also stored in memory, so there’s a high degree of self-reference that can be hard to grok.</p>

<h2 id="related-posts">Related Posts</h2>

<p>A lot of these memory-related flows are mentioned in Brendan Gregg’s books <a href="https://www.kuniga.me/blog/2025/10/10/review-systems-performance.html">Systems Performance</a> and <a href="https://www.kuniga.me/blog/2025/12/28/book-bpf-performance-tools.html">BPF Performance Tools</a>, which describe how to observe them. I recall some of the tools went over my head in terms of what they did, but having a deeper picture of these memory flows should help when I revisit them.</p>

<p>The post about <a href="https://www.kuniga.me/blog/2025/04/12/elf.html">ELF: Executable and Linkable Format</a> discusses virtual memory from the process perspective.</p>

<p>In <a href="https://www.kuniga.me/blog/2024/12/07/local-ipc.html">Local Inter-Process Communication</a>, we briefly mentioned shared memory and memory-mapped files, both of which are relevant to this post but we didn’t cover them due to space. Shared memory is when physical addresses are mapped by multiple processes and poses extra challenges for memory reclamation.</p>

<p>Memory-mapped files are when disks have RAM semantics, so to make things more efficient, the kernel ends up keeping caches in memory which, as we saw, are the first to be reclaimed when under pressure.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="operating systems" />


        <summary type="html"><![CDATA[For most operating systems, when memory usage grows beyond what the hardware can support, the kernel starts swapping, i.e. moving data from memory to disk. In this post, we’ll study how the Linux kernel does this, as part of the more general memory reclamation process. We’ll also cover the memory allocation flow, because memory reclamation is just one part of it, one of the unhappy paths. First, we’ll go over the different components involved, and then how they fit together in the memory allocation flow and then memory reclamation via swap and zswap.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">LZ77</title>
      <link href="https://www.kuniga.me/blog/2026/09/05/lz77.html" rel="alternate" type="text/html" title="LZ77" />
      <published>2026-09-05T00:00:00+00:00</published>
      <updated>2026-09-05T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/09/05/lz77</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/09/05/lz77.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/2026-09-05-lz77/cats.jpeg" alt="2 cats merging into one." />
</figure>

<p>Jacob Ziv and Abraham Lempel were both faculty at the Technion in Haifa, Israel, when in 1977 they published a paper called <em>A Universal Algorithm for Sequential Data Compression</em> in which they described a compression algorithm which, unlike <a href="https://www.kuniga.me/blog/2020/06/11/huffman-coding.html">Huffman coding</a>, doesn’t rely on knowing the frequency of symbols upfront.</p>

<p>Ziv was an information theorist from the Electrical Engineering department while Lempel was part of the Computer Science department. They met due to their interest in lossless compression and Ziv said [1] that their skills complemented each other well:</p>

<blockquote>
  <p>I knew all about information theory and statistics, and Abraham was well-equipped in Boolean algebra and computer science.</p>
</blockquote>

<p>This algorithm is now known as LZ77 (their last name initials + the year the paper was published). A popular algorithm called DEFLATE combines LZ77 with Huffman and is used by tons of software including gzip, git, png, etc.</p>

<p>In this post we’ll cover the LZ77 algorithm.</p>

<!--more-->

<h2 id="intuition">Intuition</h2>

<p>Suppose we have a programming language with only two instructions: <code class="language-plaintext highlighter-rouge">literal &lt;symbol&gt;</code> and <code class="language-plaintext highlighter-rouge">copy &lt;rewind&gt; &lt;length&gt;</code>. The program starts with an empty output buffer. The instruction <code class="language-plaintext highlighter-rouge">literal &lt;symbol&gt;</code> adds <code class="language-plaintext highlighter-rouge">&lt;symbol&gt;</code> to the buffer. <code class="language-plaintext highlighter-rouge">copy</code> moves the cursor back <code class="language-plaintext highlighter-rouge">&lt;rewind&gt;</code> positions and copies the symbol under the cursor to the end of output <code class="language-plaintext highlighter-rouge">&lt;length&gt;</code> times.</p>

<p>Let’s do an example:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">literal</span> <span class="n">a</span><span class="p">;</span> <span class="c1">// a</span>
<span class="n">literal</span> <span class="n">b</span><span class="p">;</span> <span class="c1">// ab</span>
<span class="n">literal</span> <span class="n">c</span><span class="p">;</span> <span class="c1">// abc</span>
<span class="n">copy</span> <span class="mi">2</span> <span class="mi">1</span><span class="p">;</span>  <span class="c1">// abcb</span>
<span class="n">copy</span> <span class="mi">2</span> <span class="mi">2</span><span class="p">;</span>  <span class="c1">// abcbcb</span></code></pre></figure>

<p>The comments explain what’s going on. For the literals, we see it’s just adding symbols to the end of the output. For <code class="language-plaintext highlighter-rouge">copy 2 1</code>, we rewind the cursor to <code class="language-plaintext highlighter-rouge">a[b]c</code> and then copy it to the output <code class="language-plaintext highlighter-rouge">abcb</code>. We now rewind the cursor to <code class="language-plaintext highlighter-rouge">ab[c]b</code> and then copy the next two symbols to the end, <code class="language-plaintext highlighter-rouge">abcbcb</code>.</p>

<p>Here’s another example to highlight the <em>overlap</em> effect:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">literal</span> <span class="n">a</span><span class="p">;</span> <span class="c1">// a</span>
<span class="n">literal</span> <span class="n">b</span><span class="p">;</span> <span class="c1">// ab</span>
<span class="n">literal</span> <span class="n">c</span><span class="p">;</span> <span class="c1">// abc</span>
<span class="n">copy</span> <span class="mi">3</span> <span class="mi">6</span><span class="p">;</span>  <span class="c1">// abcabcabc</span></code></pre></figure>

<p>The literals are the same as before. When we get to <code class="language-plaintext highlighter-rouge">copy 3 6</code>, and rewind 3 positions we have <code class="language-plaintext highlighter-rouge">[a]bc</code>. How is it possible to have <code class="language-plaintext highlighter-rouge">&lt;length&gt; &gt; &lt;rewind&gt;</code>? The key thing is that we’re moving the cursor on a string that is growing at the same time, so when we add <code class="language-plaintext highlighter-rouge">a</code> to the output, we end up with <code class="language-plaintext highlighter-rouge">a[b]ca</code>, then <code class="language-plaintext highlighter-rouge">ab[c]ab</code>, then <code class="language-plaintext highlighter-rouge">abc[a]bc</code>, <code class="language-plaintext highlighter-rouge">abca[b]ca</code>, <code class="language-plaintext highlighter-rouge">abcab[c]ab</code> and finally <code class="language-plaintext highlighter-rouge">abcabc[a]bc</code>.</p>

<p>It would be a bit clearer if this language had, say, a <code class="language-plaintext highlighter-rouge">rewind &lt;rewind&gt;</code> command that moved the cursor <code class="language-plaintext highlighter-rouge">&lt;rewind&gt;</code> positions back and <code class="language-plaintext highlighter-rouge">copy</code> just copied the current symbol to the end and moved the cursor by one unit. Then our previous example would be:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">literal</span> <span class="n">a</span><span class="p">;</span> <span class="c1">// a[]</span>
<span class="n">literal</span> <span class="n">b</span><span class="p">;</span> <span class="c1">// ab[]</span>
<span class="n">literal</span> <span class="n">c</span><span class="p">;</span> <span class="c1">// abc[]</span>
<span class="n">rewind</span> <span class="mi">3</span><span class="p">;</span>  <span class="c1">// [a]bc</span>
<span class="n">copy</span><span class="p">;</span>      <span class="c1">// a[b]ca</span>
<span class="n">copy</span><span class="p">;</span>      <span class="c1">// ab[c]ab</span>
<span class="n">copy</span><span class="p">;</span>      <span class="c1">// abc[a]bc</span>
<span class="n">copy</span><span class="p">;</span>      <span class="c1">// abca[b]ca</span>
<span class="n">copy</span><span class="p">;</span>      <span class="c1">// abcab[c]ab</span>
<span class="n">copy</span><span class="p">;</span>      <span class="c1">// abcabc[a]bc</span></code></pre></figure>

<p>But this version is much more verbose. Even the original one we provided is very verbose. We can get away with having the literals as a single string, <code class="language-plaintext highlighter-rouge">abc</code> in our example, and <code class="language-plaintext highlighter-rouge">copy</code> now takes 3 arguments: <code class="language-plaintext highlighter-rouge">lit_cnt</code>, <code class="language-plaintext highlighter-rouge">length</code> and <code class="language-plaintext highlighter-rouge">rewind</code>. The only new one is <code class="language-plaintext highlighter-rouge">lit_cnt</code> which counts after how many <code class="language-plaintext highlighter-rouge">literal</code> instructions we inject this <code class="language-plaintext highlighter-rouge">copy</code>.</p>

<p>The previous example could be encoded as:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">literal</span> <span class="n">abc</span><span class="p">;</span>
<span class="n">copy</span> <span class="mi">3</span> <span class="mi">6</span> <span class="mi">3</span><span class="p">;</span></code></pre></figure>

<p>We’re basically saying the <code class="language-plaintext highlighter-rouge">copy</code> appears after all 3 literals which is not very instructive. Let’s consider a more complicated example with <code class="language-plaintext highlighter-rouge">literal</code> and <code class="language-plaintext highlighter-rouge">copy</code> interleaved:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">literal</span> <span class="n">a</span><span class="p">;</span> <span class="c1">// a</span>
<span class="n">literal</span> <span class="n">b</span><span class="p">;</span> <span class="c1">// ab</span>
<span class="n">copy</span> <span class="mi">2</span> <span class="mi">2</span><span class="p">;</span>  <span class="c1">// abab</span>
<span class="n">literal</span> <span class="n">c</span><span class="p">;</span> <span class="c1">// ababc</span>
<span class="n">copy</span> <span class="mi">4</span> <span class="mi">3</span><span class="p">;</span>  <span class="c1">// ababcbab</span>
<span class="n">literal</span> <span class="n">d</span><span class="p">;</span> <span class="c1">// ababcbabd</span></code></pre></figure>

<p>This could be represented more compactly as</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">literal</span> <span class="n">abcd</span><span class="p">;</span>
<span class="n">copy</span> <span class="mi">2</span> <span class="mi">2</span> <span class="mi">2</span><span class="p">;</span>  <span class="c1">// inserted after 2 literals: a and b</span>
<span class="n">copy</span> <span class="mi">1</span> <span class="mi">3</span> <span class="mi">4</span><span class="p">;</span>  <span class="c1">// inserted after 1 literal: c</span></code></pre></figure>

<p>This is essentially the LZ77 encoding! The decoding part consists in “running” this program. The tricky part is the encoding, so let’s cover that.</p>

<h2 id="encoding">Encoding</h2>

<p>We’ll start with a greedy algorithm. We iterate over each character on the input. At a given position <code class="language-plaintext highlighter-rouge">i</code>, we try rewinding <code class="language-plaintext highlighter-rouge">r</code> positions and find the maximum prefix between a string starting at <code class="language-plaintext highlighter-rouge">i</code> and at <code class="language-plaintext highlighter-rouge">i - r</code>.</p>

<p>If the longest prefix found is at least 3 (this is because each <code class="language-plaintext highlighter-rouge">copy</code> requires 3 integers, so to be worth using it it must replace at least 3 characters) we emit a <code class="language-plaintext highlighter-rouge">copy</code> command for that prefix. Otherwise we emit the current position <code class="language-plaintext highlighter-rouge">i</code> as a literal.</p>

<p>In Python it could look like this:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">longest_prefix</span><span class="p">(</span><span class="n">s</span><span class="p">,</span> <span class="n">i</span><span class="p">,</span> <span class="n">j</span><span class="p">):</span>
    <span class="s">"""
    Finds the length of the longest common prefix
    between s[i:] and s[j:]. Assumes i &gt;= j
    """</span>
    <span class="n">p</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="k">while</span> <span class="n">i</span> <span class="o">+</span> <span class="n">p</span> <span class="o">&lt;</span> <span class="nb">len</span><span class="p">(</span><span class="n">s</span><span class="p">)</span> <span class="ow">and</span> <span class="n">s</span><span class="p">[</span><span class="n">i</span> <span class="o">+</span> <span class="n">p</span><span class="p">]</span> <span class="o">==</span> <span class="n">s</span><span class="p">[</span><span class="n">j</span> <span class="o">+</span> <span class="n">p</span><span class="p">]:</span>
        <span class="n">p</span> <span class="o">+=</span> <span class="mi">1</span>
    <span class="k">return</span> <span class="n">p</span>

<span class="k">def</span> <span class="nf">best_rewind</span><span class="p">(</span><span class="n">s</span><span class="p">,</span> <span class="n">i</span><span class="p">):</span>
    <span class="s">"""
    Finds the r such that the longest common prefix between
    s[i:] and s[i-r:] is the longest. Return r and the prefix
    length.
    """</span>
    <span class="n">best_l</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="n">best_r</span> <span class="o">=</span> <span class="o">-</span><span class="mi">1</span>

    <span class="k">for</span> <span class="n">r</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span> <span class="n">i</span> <span class="o">+</span> <span class="mi">1</span><span class="p">):</span>
        <span class="n">l</span> <span class="o">=</span> <span class="n">longest_prefix</span><span class="p">(</span><span class="n">s</span><span class="p">,</span> <span class="n">i</span><span class="p">,</span> <span class="n">i</span> <span class="o">-</span> <span class="n">r</span><span class="p">)</span>

        <span class="k">if</span> <span class="n">l</span> <span class="o">&gt;</span> <span class="n">best_l</span><span class="p">:</span>
            <span class="n">best_l</span> <span class="o">=</span> <span class="n">l</span>
            <span class="n">best_r</span> <span class="o">=</span> <span class="n">r</span>

    <span class="k">return</span> <span class="n">best_r</span><span class="p">,</span> <span class="n">best_l</span>

<span class="k">def</span> <span class="nf">encode</span><span class="p">(</span><span class="nb">input</span><span class="p">):</span>
    <span class="n">i</span><span class="p">,</span> <span class="n">prev_i</span> <span class="o">=</span> <span class="mi">0</span><span class="p">,</span> <span class="mi">0</span>
    <span class="n">lits</span><span class="p">,</span> <span class="n">cps</span> <span class="o">=</span> <span class="s">''</span><span class="p">,</span> <span class="p">[]</span>

    <span class="k">while</span> <span class="n">i</span> <span class="o">&lt;</span> <span class="nb">len</span><span class="p">(</span><span class="nb">input</span><span class="p">):</span>

        <span class="n">best_r</span><span class="p">,</span> <span class="n">best_l</span> <span class="o">=</span> <span class="n">best_rewind</span><span class="p">(</span><span class="nb">input</span><span class="p">,</span> <span class="n">i</span><span class="p">)</span>

        <span class="k">if</span> <span class="n">best_l</span> <span class="o">&gt;=</span> <span class="mi">3</span><span class="p">:</span>
            <span class="n">cps</span><span class="p">.</span><span class="n">append</span><span class="p">((</span><span class="n">i</span> <span class="o">-</span> <span class="n">prev_i</span><span class="p">,</span> <span class="n">best_l</span><span class="p">,</span> <span class="n">best_r</span><span class="p">))</span>
            <span class="n">prev_i</span> <span class="o">=</span> <span class="n">i</span>
            <span class="n">i</span> <span class="o">+=</span> <span class="n">best_l</span>

        <span class="k">else</span><span class="p">:</span>
            <span class="n">lits</span> <span class="o">+=</span> <span class="nb">input</span><span class="p">[</span><span class="n">i</span><span class="p">]</span>
            <span class="n">i</span> <span class="o">+=</span> <span class="mi">1</span>

    <span class="k">return</span> <span class="n">lits</span><span class="p">,</span> <span class="n">cps</span></code></pre></figure>

<p>The comments and code are easy to follow. The only observation is that when we append the triple <code class="language-plaintext highlighter-rouge">(i - prev_i, best_l, best_r)</code>, we don’t store the current length of the <code class="language-plaintext highlighter-rouge">literals</code> but how many literals appeared between the current <code class="language-plaintext highlighter-rouge">copy</code> instruction and the previous one.</p>

<p>If $n$ is the length of the input, this algorithm is $O(n^3)$ in the worst case. We can bound this complexity by capping how far back we rewind in <code class="language-plaintext highlighter-rouge">best_rewind()</code> by changing:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">for</span> <span class="n">r</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span> <span class="n">i</span> <span class="o">+</span> <span class="mi">1</span><span class="p">):</span>
  <span class="p">...</span></code></pre></figure>

<p>to</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">for</span> <span class="n">r</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="mi">1</span><span class="p">,</span> <span class="nb">min</span><span class="p">(</span><span class="n">i</span> <span class="o">+</span> <span class="mi">1</span><span class="p">,</span> <span class="n">window</span><span class="p">)):</span>
  <span class="p">...</span></code></pre></figure>

<p>There’s another practical consideration in that we can’t afford to load the entire input into memory, so we can’t look forward or backward too far, so we can also limit how far <code class="language-plaintext highlighter-rouge">longest_prefix()</code> scans.</p>

<h2 id="decoding">Decoding</h2>

<p>Decoding is a bit simpler. As we discussed, it consists in running the program:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">decode</span><span class="p">(</span><span class="n">lits</span><span class="p">,</span> <span class="n">cps</span><span class="p">):</span>
    <span class="n">out</span> <span class="o">=</span> <span class="s">''</span>
    <span class="n">prev</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="k">for</span> <span class="n">cnt</span><span class="p">,</span> <span class="n">l</span><span class="p">,</span> <span class="n">r</span> <span class="ow">in</span> <span class="n">cps</span><span class="p">:</span>
        <span class="n">out</span> <span class="o">+=</span> <span class="n">lits</span><span class="p">[</span><span class="n">prev</span><span class="p">:</span><span class="n">prev</span> <span class="o">+</span> <span class="n">cnt</span><span class="p">]</span>
        <span class="n">prev</span> <span class="o">+=</span> <span class="n">cnt</span>

        <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">l</span><span class="p">):</span>
            <span class="n">out</span> <span class="o">+=</span> <span class="n">out</span><span class="p">[</span><span class="nb">len</span><span class="p">(</span><span class="n">out</span><span class="p">)</span> <span class="o">-</span> <span class="n">r</span><span class="p">]</span>

    <span class="n">out</span> <span class="o">+=</span> <span class="n">lits</span><span class="p">[</span><span class="n">prev</span><span class="p">:]</span>
    <span class="k">return</span> <span class="n">out</span></code></pre></figure>

<p>Note that inside the innermost loop, <code class="language-plaintext highlighter-rouge">len(out)</code> changes as we append characters to it.</p>

<p>As for complexity, decoding is linear on the output, which we must emit anyway, so we can’t expect to do better than that.</p>

<h2 id="composition">Composition</h2>

<p>As we mentioned at the start, LZ77 is typically not used on its own but rather combined with other encoders for further compression. We cover two popular composite encoders that use LZ77: DEFLATE and zstd.</p>

<p>At a very high level, DEFLATE applies LZ77 but uses the less compact form, the one that interleaves literals and the copy instructions. It counts the frequency of symbols and instructions on this output and then it applies Huffman coding.</p>

<p>The zstd algorithm applies LZ77 first using the compact form. It then either uses <a href="https://en.wikipedia.org/wiki/Run-length_encoding">run-length encoding</a> or Huffman coding for the literals and a variant of <a href="https://www.kuniga.me/blog/2026/08/20/ans.html">ANS</a> called FSE (Finite State Entropy) for the copy instructions.</p>

<h2 id="lzw">LZW</h2>

<p>When I ran into LZ77, I could swear I had heard of Lempel Ziv before. Doing some searches on my email, I found that I had implemented the algorithm <a href="https://en.wikipedia.org/wiki/Lempel%E2%80%93Ziv%E2%80%93Welch">Lempel-Ziv-Welch</a> or LZW in 2006, <strong>in assembly</strong>, for a class in college. I had no recollection of this implementation.</p>

<p>This is funny because when I first saw LZ77 encoding framed as a programming language with instructions <code class="language-plaintext highlighter-rouge">literal</code> and <code class="language-plaintext highlighter-rouge">copy</code> it reminded me of Assembly.</p>

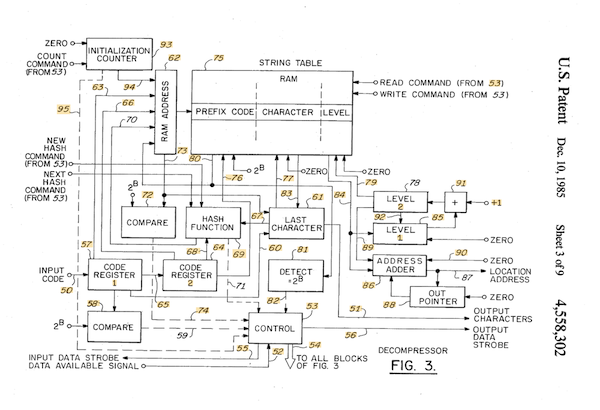
<p>There’s an interesting story behind LZW. Lempel and Ziv improved upon LZ77 in 1978 and named it LZ78. In 1983, Terry Welch improved on LZ78 and called it LZW. Welch did so while working at Sperry Corporation, later Unisys, who <a href="https://patents.google.com/patent/US4558302A/en">patented</a> the algorithm.</p>

<p>In 1987 CompuServe released the image format GIF, which used LZW. In 1994 Unisys started requiring software developers implementing LZW to pay license fees. Creating or distributing GIF images was not subject to this.</p>

<p>In 1993 Phil Katz invented the DEFLATE algorithm. As a response to the LZW controversy, the PNG image format was created in 1995 which used DEFLATE for compression. The patent for LZW expired in 2003 but due to the licensing requirements and DEFLATE’s better compression LZW isn’t widely adopted.</p>

<h2 id="conclusion">Conclusion</h2>

<p>There are many tweaks and optimizations (e.g. not loading the entire input into memory) we can do but my main goal was to have a high level understanding of how LZ77 works! My main objective was to get a better sense of what goes into zstd.</p>

<h2 id="references">References</h2>

<ul>
  <li>[<a href="https://spectrum.ieee.org/remembering-jacob-ziv">1</a>] IEEE Spectrum: Remembering Data Compression Pioneer Jacob Ziv.</li>
</ul>

<h2 id="related-posts">Related Posts</h2>

<p>It’s interesting that both LZW and <a href="https://www.kuniga.me/blog/2026/08/20/ans.html">Asymmetric Numeral Systems</a> have some drama around patents. Encoders have an interesting trait that make them subject to this: once you use a given encoder, you are required to use the corresponding decoder. Another factor seems to be that encoding is low-level enough to be implemented in hardware, which has a stronger precedence of patenting vs. algorithms in general that cannot be patented because they’re abstract ideas.</p>

<p>If we look at the <a href="https://patents.google.com/patent/US4558302A/en">patent</a> it’s actually describing hardware:</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-09-05-lz77/patent.png" alt="See caption." />
  <figcaption>Figure 1: Page 3 of the LZW patent.</figcaption>
</figure>

<p>In the post <a href="https://www.kuniga.me/blog/2016/03/13/tree-ring-matching-using-the-kmp-algorithm.html">Tree Ring Matching using the KMP Algorithm</a> we’re trying to solve the problem of finding the largest overlap between a suffix and prefix of two strings. This is similar to finding the largest overlap between the prefixes in <code class="language-plaintext highlighter-rouge">longest_prefix()</code>.</p>

<p>The LZ77 reminds me both of the KMP algorithm mentioned above and the <a href="https://www.kuniga.me/blog/2019/11/09/aho-corasick.html">Aho-Corasick</a> where we have to efficiently find patterns in the input text.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="data structures" />


        <summary type="html"><![CDATA[Jacob Ziv and Abraham Lempel were both faculty at the Technion in Haifa, Israel, when in 1977 they published a paper called A Universal Algorithm for Sequential Data Compression in which they described a compression algorithm which, unlike Huffman coding, doesn’t rely on knowing the frequency of symbols upfront. Ziv was an information theorist from the Electrical Engineering department while Lempel was part of the Computer Science department. They met due to their interest in lossless compression and Ziv said [1] that their skills complemented each other well: I knew all about information theory and statistics, and Abraham was well-equipped in Boolean algebra and computer science. This algorithm is now known as LZ77 (their last name initials + the year the paper was published). A popular algorithm called DEFLATE combines LZ77 with Huffman and is used by tons of software including gzip, git, png, etc. In this post we’ll cover the LZ77 algorithm.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">CacheLib</title>
      <link href="https://www.kuniga.me/blog/2026/08/28/cachelib.html" rel="alternate" type="text/html" title="CacheLib" />
      <published>2026-08-28T00:00:00+00:00</published>
      <updated>2026-08-28T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/08/28/cachelib</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/08/28/cachelib.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/2026-08-28-cachelib/cachelib-logo.png" alt="CacheLib Logo" />
</figure>

<p>CacheLib is an open-source C++ library from Meta for constructing in-process caches. At a high level, we can think of it as a hash table in memory with the option to spill to flash storage.</p>

<p>In this post we’ll study this library, mainly the in-memory portion based on the paper <em>The CacheLib Caching Engine: Design and Experiences at Scale</em> [1] and the code.</p>

<!--more-->

<h2 id="motivation">Motivation</h2>

<p>The paper [1] states the problem CacheLib aims to solve: different systems reinvent the wheel when writing an in-process cache system. The argument for that is different systems require specialized cache solutions, so they can’t use off the shelf solutions.</p>

<p>CacheLib challenges that assumption by providing a flexible cache library that supports a multitude of production use cases including CDN, distributed application cache (e.g. memcached), general in-process cache, etc.</p>

<p>It also provides efficient multi-thread support and a secondary layer of flash storage.</p>

<h2 id="example">Example</h2>

<p>I always understand things better via examples, so let’s start with one, even though some parts need explaining later. The plan is to write a simple key to the cache, then query for that key and then another key that is not in there.</p>

<p>The API can feel a bit un-ergonomic because it’s meant to support multiple use cases, but we can define helpers that make it look more like a hash-table. First inserting an element:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="kt">bool</span> <span class="nf">put</span><span class="p">(</span>
  <span class="n">Cache</span><span class="o">&amp;</span> <span class="n">cache</span><span class="p">,</span>
  <span class="n">PoolId</span> <span class="n">pid</span><span class="p">,</span>
  <span class="k">const</span> <span class="n">std</span><span class="o">::</span><span class="n">string</span><span class="o">&amp;</span> <span class="n">key</span><span class="p">,</span>
  <span class="k">const</span> <span class="n">std</span><span class="o">::</span><span class="n">string</span><span class="o">&amp;</span> <span class="n">value</span><span class="p">)</span> <span class="p">{</span>

  <span class="k">auto</span> <span class="n">handle</span> <span class="o">=</span> <span class="n">cache</span><span class="p">.</span><span class="n">allocate</span><span class="p">(</span><span class="n">pid</span><span class="p">,</span> <span class="n">key</span><span class="p">,</span> <span class="n">value</span><span class="p">.</span><span class="n">size</span><span class="p">());</span>
  <span class="k">if</span> <span class="p">(</span><span class="o">!</span><span class="n">handle</span><span class="p">)</span> <span class="p">{</span>
    <span class="k">return</span> <span class="nb">false</span><span class="p">;</span> <span class="c1">// pool is full and nothing was evictable</span>
  <span class="p">}</span>
  <span class="n">std</span><span class="o">::</span><span class="n">memcpy</span><span class="p">(</span><span class="n">handle</span><span class="o">-&gt;</span><span class="n">getMemory</span><span class="p">(),</span> <span class="n">value</span><span class="p">.</span><span class="n">data</span><span class="p">(),</span> <span class="n">value</span><span class="p">.</span><span class="n">size</span><span class="p">());</span>
  <span class="n">cache</span><span class="p">.</span><span class="n">insertOrReplace</span><span class="p">(</span><span class="n">handle</span><span class="p">);</span>
  <span class="k">return</span> <span class="nb">true</span><span class="p">;</span>
<span class="p">}</span></code></pre></figure>

<p>The API requires a pool, which we’ll cover later. When calling <code class="language-plaintext highlighter-rouge">.allocate()</code> it gets an <code class="language-plaintext highlighter-rouge">ItemHandle</code> if the library was able to find available memory. Then we copy the data from the value to the handle’s memory and finally signal to the handle to perform the write.</p>

<p>A natural question to ask is why the API is split into 3 pieces. I haven’t found an explicit motivation, but a legit one is that by giving you the memory buffer, you can construct the object directly there instead of copying. In our case we did end up copying anyway, but there might be cases where we don’t have to.</p>

<p>The <code class="language-plaintext highlighter-rouge">get()</code> is simpler:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">std</span><span class="o">::</span><span class="n">optional</span><span class="o">&lt;</span><span class="n">std</span><span class="o">::</span><span class="n">string</span><span class="o">&gt;</span> <span class="n">get</span><span class="p">(</span><span class="n">Cache</span><span class="o">&amp;</span> <span class="n">cache</span><span class="p">,</span> <span class="k">const</span> <span class="n">std</span><span class="o">::</span><span class="n">string</span><span class="o">&amp;</span> <span class="n">key</span><span class="p">)</span> <span class="p">{</span>
  <span class="k">auto</span> <span class="n">handle</span> <span class="o">=</span> <span class="n">cache</span><span class="p">.</span><span class="n">find</span><span class="p">(</span><span class="n">key</span><span class="p">);</span>
  <span class="k">if</span> <span class="p">(</span><span class="o">!</span><span class="n">handle</span><span class="p">)</span> <span class="p">{</span>
    <span class="k">return</span> <span class="n">std</span><span class="o">::</span><span class="n">nullopt</span><span class="p">;</span>
  <span class="p">}</span>
  <span class="k">auto</span> <span class="o">*</span><span class="n">payload</span> <span class="o">=</span> <span class="k">reinterpret_cast</span><span class="o">&lt;</span><span class="k">const</span> <span class="kt">char</span><span class="o">*&gt;</span><span class="p">(</span><span class="n">handle</span><span class="o">-&gt;</span><span class="n">getMemory</span><span class="p">());</span>
  <span class="k">return</span> <span class="n">std</span><span class="o">::</span><span class="n">string</span><span class="p">(</span><span class="n">payload</span><span class="p">,</span> <span class="n">handle</span><span class="o">-&gt;</span><span class="n">getSize</span><span class="p">());</span>
<span class="p">}</span></code></pre></figure>

<p>The only observation is that we store raw bytes in the cache so we need to cast them back to the expected type. Here’s an example on how to write and read back from it:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="cp">#include</span> <span class="cpf">&lt;cachelib/allocator/CacheAllocator.h&gt;</span><span class="cp">
</span>
<span class="k">using</span> <span class="n">Cache</span> <span class="o">=</span> <span class="n">facebook</span><span class="o">::</span><span class="n">cachelib</span><span class="o">::</span><span class="n">LruAllocator</span><span class="p">;</span>
<span class="k">using</span> <span class="n">facebook</span><span class="o">::</span><span class="n">cachelib</span><span class="o">::</span><span class="n">PoolId</span><span class="p">;</span>

<span class="n">Cache</span><span class="o">::</span><span class="n">Config</span> <span class="n">config</span><span class="p">;</span>

<span class="n">config</span><span class="p">.</span><span class="n">setCacheName</span><span class="p">(</span><span class="s">"example"</span><span class="p">)</span>
  <span class="p">.</span><span class="n">setCacheSize</span><span class="p">(</span><span class="mi">256</span> <span class="o">*</span> <span class="mi">1024</span> <span class="o">*</span> <span class="mi">1024</span><span class="p">)</span> <span class="c1">// 256 MB of DRAM</span>
  <span class="p">.</span><span class="n">validate</span><span class="p">();</span>

<span class="n">Cache</span> <span class="nf">cache</span><span class="p">(</span><span class="n">config</span><span class="p">);</span>

<span class="k">const</span> <span class="k">auto</span> <span class="n">pid</span> <span class="o">=</span>
  <span class="n">cache</span><span class="p">.</span><span class="n">addPool</span><span class="p">(</span><span class="s">"default"</span><span class="p">,</span> <span class="n">cache</span><span class="p">.</span><span class="n">getCacheMemoryStats</span><span class="p">().</span><span class="n">ramCacheSize</span><span class="p">);</span>

<span class="n">put</span><span class="p">(</span><span class="n">cache</span><span class="p">,</span> <span class="n">pid</span><span class="p">,</span> <span class="s">"hello"</span><span class="p">,</span> <span class="s">"world"</span><span class="p">);</span>

<span class="c1">// retrieval</span>
<span class="n">std</span><span class="o">::</span><span class="n">cout</span> <span class="o">&lt;&lt;</span> <span class="n">get</span><span class="p">(</span><span class="n">cache</span><span class="p">,</span> <span class="s">"my_key"</span><span class="p">).</span><span class="n">value_or</span><span class="p">(</span><span class="s">"&lt;miss&gt;"</span><span class="p">)</span> <span class="o">&lt;&lt;</span> <span class="s">"</span><span class="se">\n</span><span class="s">"</span><span class="p">;</span>
<span class="n">std</span><span class="o">::</span><span class="n">cout</span> <span class="o">&lt;&lt;</span> <span class="n">get</span><span class="p">(</span><span class="n">cache</span><span class="p">,</span> <span class="s">"other_key"</span><span class="p">).</span><span class="n">value_or</span><span class="p">(</span><span class="s">"&lt;miss&gt;"</span><span class="p">)</span> <span class="o">&lt;&lt;</span> <span class="s">"</span><span class="se">\n</span><span class="s">"</span><span class="p">;</span></code></pre></figure>

<p>The size we set to <code class="language-plaintext highlighter-rouge">setCacheSize()</code> is a hard ceiling on how much the pools can consume. The pools themselves have a size, which in this case is the same as the cache size since we only have a single pool.</p>

<p>It’s worth mentioning that the size passed to the <code class="language-plaintext highlighter-rouge">Cache::Config</code> is the “physical” amount of memory we allow it to use, including for overhead such as metadata. The size we provide to the pool is the “logical” amount, how much it can use to store actual data.</p>

<p>To make the point clearer, we can’t do:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">cache</span><span class="p">.</span><span class="n">addPool</span><span class="p">(</span><span class="s">"default"</span><span class="p">,</span> <span class="mi">256</span> <span class="o">*</span> <span class="mi">1024</span> <span class="o">*</span> <span class="mi">1024</span><span class="p">);</span></code></pre></figure>

<p>We have to use <code class="language-plaintext highlighter-rouge">cache.getCacheMemoryStats().ramCacheSize</code> which is the effective amount of space available for use.</p>

<h2 id="concepts">Concepts</h2>

<p>Now that we have some idea on how to use CacheLib, let’s cover the major components and connect it to the example we saw.</p>

<h3 id="slab">Slab</h3>

<p>The unit of memory used by CacheLib is called a <strong>slab</strong>, a chunk of contiguous 4MB memory. The slabs are 4MB-aligned too, meaning their starting address is divisible by 4MB. This allows us to optimize the logic to determine the slab address from a chunk address as we’ll see later (see <em>Chunk</em>).</p>

<p>Each slab carries 3 pieces of metadata: pool id (see <em>Pool</em>), class id (see <em>Allocation Classes</em>) and the chunk size (see <em>Chunk</em>).</p>

<p>Multiple items can be stored in a slab, but if its size is greater than 4MB, then an item is stored across multiple slabs connected as a linked list.</p>

<h3 id="slab-allocator">Slab Allocator</h3>

<p>The slabs are stored in a contiguous array, which is initialized when creating the cache (based on <code class="language-plaintext highlighter-rouge">setCacheSize()</code>). The library uses <code class="language-plaintext highlighter-rouge">mmap</code> to get a contiguous virtual address space, but the mapping to physical space is done lazily by the OS.</p>

<p>This array is byte-aligned to 4MB meaning the address of each slab is divisible by 4MB or $2^{22}$. The maximum number of slabs the allocator supports is $2^{32} - 1$.</p>

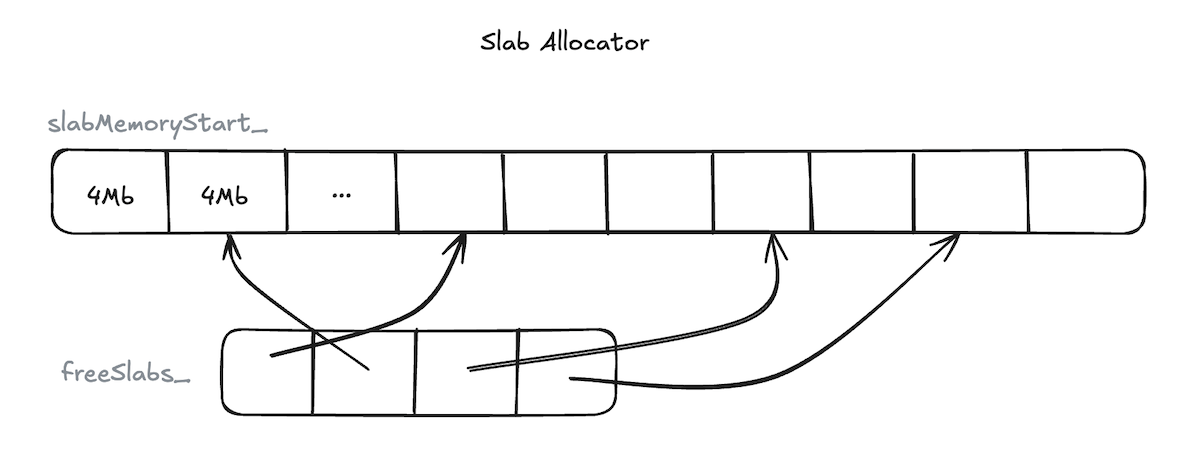
<p>This array is owned by the slab allocator and it also maintains a list of free slabs.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-08-28-cachelib/slab-allocator.png" alt="See caption" style="width: 600px;" />
  <figcaption>Figure 1. Slab allocator holds a fixed size mmap region containing all the slabs. It also contains a <code>std::vector&lt;Slab\*&gt; freeSlabs</code>.</figcaption>
</figure>

<h3 id="chunk">Chunk</h3>

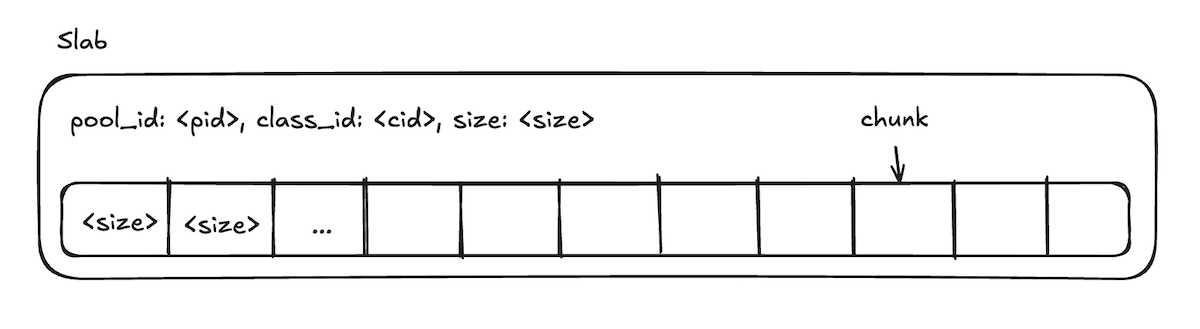
<p>A chunk is a subdivision of a slab. We can think of each slab having an array of chunks of a fixed size, called <strong>allocation class</strong> and stored as the slab’s metadata.</p>

<p>Each chunk stores exactly one item. This means we need to have slabs with lots of different sizes to avoid internal fragmentation. Because if an item has size 75B and the smallest chunk size is 1K, all the remaining space is wasted. The minimum chunk size is 64B ($2^6$), so each slab can hold at most 65,536 ($2^{16}$) chunks.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-08-28-cachelib/chunks.png" alt="See caption" style="width: 600px;" />
  <figcaption>Figure 2. Chunks inside a slab</figcaption>
</figure>

<p>In some situations we need to determine the slab address the chunk lives in with only the chunk address. Since we know slabs always have 4MB, first we can determine the slab index via:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="c1">// index of the slab in the slab array</span>
<span class="n">idx</span>  <span class="o">=</span> <span class="p">(</span><span class="n">p</span> <span class="o">-</span> <span class="n">slabMemoryStart_</span><span class="p">)</span> <span class="o">&gt;&gt;</span> <span class="mi">22</span><span class="p">;</span>
<span class="c1">// address of the slab</span>
<span class="n">slab</span> <span class="o">=</span> <span class="n">slabMemoryStart_</span> <span class="o">+</span> <span class="p">(</span><span class="n">idx</span> <span class="o">&lt;&lt;</span> <span class="mi">22</span><span class="p">);</span></code></pre></figure>

<p>But since we know it’s aligned at 4MB, we can simply zero the least significant 22 bits of the chunk address:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">slab</span> <span class="o">=</span> <span class="n">p</span> <span class="o">&amp;</span> <span class="o">~</span><span class="p">((</span><span class="mi">1</span> <span class="o">&lt;&lt;</span> <span class="mi">22</span><span class="p">)</span> <span class="o">-</span> <span class="mi">1</span><span class="p">);</span></code></pre></figure>

<h3 id="item">Item</h3>

<p>An item (<code class="language-plaintext highlighter-rouge">CacheItem</code>) is a class containing the key and value of the stored entry. It also stores metadata such as TTL. There’s a 1:1 mapping between a chunk and an item, so conceptually we can treat them as the same thing, as we’ll do throughout the post.</p>

<p>A chunk is a blob of memory, whereas the item is the data that lives in that location. A chunk has fixed size whereas the item size depends on what it’s storing. The chunk is not deleted when an item is evicted.</p>

<p>An item also represents a node in two linked lists, which we’ll call the <em>index-linked-list</em> and the <em>eviction-linked-list</em>. We’ll discuss them in <em>Index</em> and <em>Eviction-Order</em>, respectively. So while chunks have a fixed “physical” order inside a slab, the items have different logical orders for indexing and eviction purposes.</p>

<h3 id="allocation-classes">Allocation Classes</h3>

<p>We can think of an allocation class as an object that manages all slabs with chunks of a given size. This is the ultimate object that determines which address to return back to the <code class="language-plaintext highlighter-rouge">allocate()</code> API.</p>

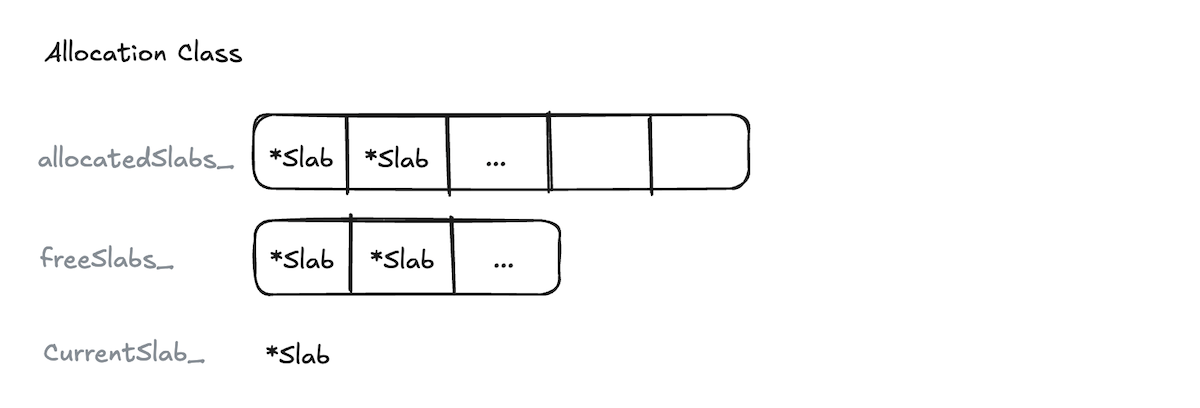
<p>It contains a few sets of information: a list of “active” slabs, a list of “free” slabs (empty slabs that it can use) and the current slab. All these are pointers to the global slab array. It also stores a stack of pointers to chunks that have been freed (<code class="language-plaintext highlighter-rouge">freedAllocations</code>).</p>

<p>An active slab never goes back to be a free slab. So as the program runs, and assuming the cache is fully utilized, we’ll get to an equilibrium state where there are no free slabs and each class is “right sized”. If item distribution changes though, there’s a background process to rebalance things (see <em>Rebalancing</em>).</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-08-28-cachelib/alloc-class.png" alt="See caption" style="width: 600px;" />
  <figcaption>Figure 3. Lists of slabs of an allocation class</figcaption>
</figure>

<h3 id="pool">Pool</h3>

<p>A <strong>pool</strong> (class <code class="language-plaintext highlighter-rouge">MemoryPool</code>) is a collection of allocation classes. We can think of pools as strict partitions of the cache memory, because it has a specified size that is honored by the system. This is not true for allocation classes within a pool. As we’ll see in <em>Rebalancing</em>, the rebalancer can move slabs between allocation classes within a pool.</p>

<p>Pools are stored as an array by the pool manager (class <code class="language-plaintext highlighter-rouge">MemoryPoolManager</code>) and the pool id is just an index on that array. You can use multiple pools if you want the cache to be shared by different use cases with different quotas. At most 64 pools can be used, but in most cases a single pool is often enough.</p>

<p>The <code class="language-plaintext highlighter-rouge">addPool()</code> method hints at the responsibilities of the pool:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">PoolId</span> <span class="nf">addPool</span><span class="p">(</span>
    <span class="n">folly</span><span class="o">::</span><span class="n">StringPiece</span> <span class="n">name</span><span class="p">,</span>
    <span class="kt">size_t</span> <span class="n">size</span><span class="p">,</span>
    <span class="k">const</span> <span class="n">std</span><span class="o">::</span><span class="n">set</span><span class="o">&lt;</span><span class="kt">uint32_t</span><span class="o">&gt;&amp;</span> <span class="n">allocSizes</span><span class="p">,</span>
    <span class="k">const</span> <span class="n">MMConfig</span><span class="o">&amp;</span> <span class="n">config</span> <span class="o">=</span> <span class="p">{},</span>
    <span class="n">std</span><span class="o">::</span><span class="n">shared_ptr</span><span class="o">&lt;</span><span class="n">RebalanceStrategy</span><span class="o">&gt;</span> <span class="n">rebalanceStrategy</span> <span class="o">=</span> <span class="nb">nullptr</span><span class="p">,</span>
    <span class="p">...,</span>
<span class="p">);</span></code></pre></figure>

<p>The <code class="language-plaintext highlighter-rouge">allocSizes</code> determines the allocation classes available to this pool, that is, the chunk sizes it supports. Note that it takes a set because it doesn’t make sense to have 2 classes with the same size. The <code class="language-plaintext highlighter-rouge">MMConfig config</code> is for the eviction policy (see <em>Eviction-Order Container</em>) and the others are related to rebalancing (see <em>Rebalancing</em>).</p>

<h3 id="index">Index</h3>

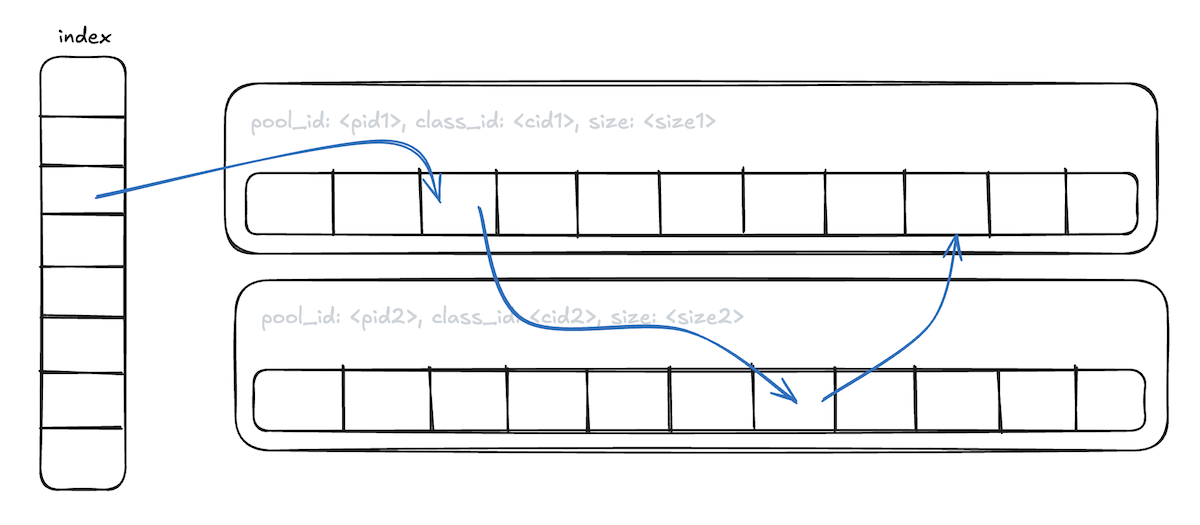
<p>The index is a hash table which conceptually maps a key to the chunk holding the value. The implementation is a fixed size array of 32-bit integers. The array size represents the number of buckets and it’s fixed throughout the cache lifetime. So when we insert a key into this array we hash the key to an integer, and take the modulo with the bucket count to find the index.</p>

<p>The 32-bit integer is used to store the location of a chunk. The 16 least significant bits identify the index of the slab in the global slab array while the 16 most significant bits identify the index of the chunk within that slab. With this addressing only $2^{16}$ or 65,536 slabs can be addressed, but we mentioned there can be up to $2^{32} - 1$ (see <em>Slab</em>). In this case a different address mechanism is used but we’ll not discuss it here.</p>

<p>To insert an entry in the index, the key is hashed and a bucket id is computed, and then the corresponding entry on the array points to the chunk address. If there was already a chunk at that bucket, the new chunk’s “next” pointer will now point to that previous chunk. In other words, on collisions we insert at the head of the linked list, like in a typical hash table.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-08-28-cachelib/index.png" alt="See caption" style="width: 600px;" />
  <figcaption>Figure 4. Index and the linked list for a given bucket formed by the <code>next</code> pointer of the <code>Item</code>. Note that this logical list can be from different slabs from different allocation-classes and pools. They're "linked" based on their hash value.</figcaption>
</figure>

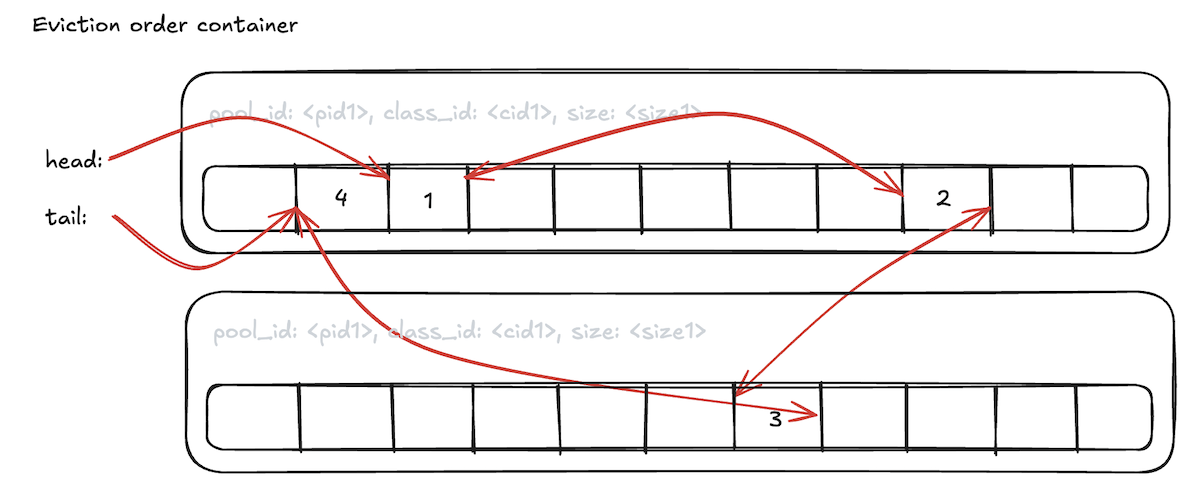
<h3 id="eviction-order-container">Eviction-Order Container</h3>

<p>Conceptually an eviction-order container is a doubly linked list containing the elements of a given pool-allocation class pair. Each such container implements different eviction policies, but let’s assume it’s LRU (least recently used) for simplicity.</p>

<p>At any given time, the order in this list represents the eviction order, such that the last element on the list will be evicted first when needed. So assuming LRU, whenever an item is inserted in the cache, it’s inserted at the head. The container has a pointer to both the head and tail of the list.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-08-28-cachelib/eviction-order-container.png" alt="See caption" style="width: 600px;" />
  <figcaption>Figure 5. Eviction container and the double linked list for a given pool + allocation class. The chunks can cross slabs but they must belong to the same allocation class.</figcaption>
</figure>

<p>The problem with eviction policies is that we often need to update the order when we <em>read</em> from the cache. Suppose we read a given chunk belonging to a linked list. We need to move it to the head of the list. This can be done in $O(1)$ because we get access to the chunk via the index and the “prev” and “next” pointers are part of the chunk. So we just do some pointer stitching to move it to the head.</p>

<h2 id="data-flows">Data Flows</h2>

<p>Let’s now cover a few data flows, the main one being insertion and see how the components fit together.</p>

<h3 id="insertion">Insertion</h3>

<p>When we call <code class="language-plaintext highlighter-rouge">cache.allocate(pid, key, size)</code> like in the example, it will internally ask the pool corresponding to <code class="language-plaintext highlighter-rouge">pid</code> for a chunk of at least <code class="language-plaintext highlighter-rouge">size</code> amount of memory. The pool will look at the different size classes it has and will ask the one with the smallest size that is greater or equal to <code class="language-plaintext highlighter-rouge">size</code>.</p>

<p>Within the class, the request for a new chunk is: if <code class="language-plaintext highlighter-rouge">freedAllocations</code> is not empty it returns the top of the stack. Otherwise, it gets a new chunk on the current slab. If the current slab is full, it chooses a free slab and makes it current. If no free slabs remain, the pool will try to give it more slabs.</p>

<p>The pool has its own set of free slabs. If it has it available, it gives it to the allocation class. If not and it’s within its budget, it requests to the slab allocator which has a global set of free slabs.</p>

<p>If no such slab can be found, then the cache might try to evict items from the allocation class. In <em>Eviction-Order Container</em> we mentioned how chunks are kept in “eviction order” so it will give that chunk to the requester. It’s not always possible to evict a chunk so it may still fail to return one.</p>

<p>It will not insert the item in the chunk until <code class="language-plaintext highlighter-rouge">insertOrReplace()</code> is called, so it will not update the <em>index-linked-list</em> nor the <em>eviction-linked-list</em> until this method is called. This means this item is not “visible” to other threads until then, but its chunk is reserved.</p>

<p><strong>Existing Key.</strong> One interesting difference in behavior from a hash table is that <code class="language-plaintext highlighter-rouge">allocate()</code> does not check if the key already exists in the cache. It first acquires a chunk and then when calling <code class="language-plaintext highlighter-rouge">insertOrReplace()</code> the old item is removed.</p>

<h3 id="eviction">Eviction</h3>

<p>Let’s focus on a flow mentioned during insertion: eviction. As we’ve seen the most common way to evict an item is when we run out of available space. Before we return it to the requester, we need to remove the chunk from the eviction order container’s doubly linked list and from the linked list on the allocator class.</p>

<p>An entry can be explicitly removed via <code class="language-plaintext highlighter-rouge">remove()</code> or via <code class="language-plaintext highlighter-rouge">insertOrReplace()</code>: recall that it allocates a new chunk and then removes the old one, it doesn’t update the chunk in-place. In these cases, the chunk is also added to the <code class="language-plaintext highlighter-rouge">freedAllocations</code> of its allocation class. It might need to update the index too (if this was the first chunk on the list).</p>

<p>There’s also a background thread, the reaper, which runs every 5 seconds by default. It traverses the array of slabs and within each slab the array of chunks. Within each chunk it will check the item’s TTL and if it’s expired it gets evicted.</p>

<h3 id="lookup">Lookup</h3>

<p>A lookup for a key consists of hashing the key, finding the right entry in the index and then traversing the corresponding linked list formed by the items, until we find the one matching the key. A handle is then returned to that item from which we can read the data.</p>

<p>As we discussed in <em>Eviction-Order Container</em>, the item might need to be moved depending on the eviction policy. For policies such as LRU it can be done in $O(1)$.</p>

<h3 id="rebalancing">Rebalancing</h3>

<p>Rebalancing is done by a background thread that runs every second. For each pool, it transfers slabs from the most empty class to the most full one.</p>

<p>If the source class has slabs in its free slabs list, the move is straightforward. If any of the active slabs is actually empty, it’s chosen. If it has some items in it, they’re <code class="language-plaintext highlighter-rouge">std::move</code>d to a different slab (defragmented) and this slab is chosen.</p>

<h2 id="concurrency">Concurrency</h2>

<p>In describing the data flows above we glossed over the intricacies of concurrency. CacheLib is designed to support multiple threads at a time so some designs that may seem arbitrarily complex might make sense in light of thread safety.</p>

<h3 id="index-and-eviction-container-locks">Index and Eviction-Container Locks</h3>

<p>The first layer of lock is on the index table. In theory we could have one lock per row, but if we use a mutex, it’s 4 bytes per row, which would double the memory size of the index table. On the other hand, if we locked the entire table with a single lock we’d run into massive contention. A middle ground is for a lock to be responsible for a subset of rows. There’s contention only for rows on the same set, but we use fewer locks.</p>

<p>During a lookup, it acquires a read lock on the index to find the right chunk to retrieve. Note that this conceptually gives a read lock to the index-linked-list associated with that bucket. Implementation wise, the “next” pointer for the index-linked-list can only be used after acquiring the appropriate lock.</p>

<p>To “move” the item within an eviction-order container, a <em>write</em> lock is acquired, which analogously gives write access to the eviction-linked-list, and that is implemented by requiring a lock to read/write the “prev” / “next” pointer for that list.</p>

<p>For the <code class="language-plaintext highlighter-rouge">put()</code> it needs to acquire a write lock on the index in addition to write locks on the eviction-order container. There are several other locks involved, especially when a new slab is needed, but the linked list ones are the more interesting.</p>

<h3 id="item-1">Item</h3>

<p>The <code class="language-plaintext highlighter-rouge">ItemHandle</code> returned by <code class="language-plaintext highlighter-rouge">cache.allocate()</code> has a reference count. If the reference count is non-zero, then the cache won’t evict the corresponding item.</p>

<p>Recall from <em>Data Flows &gt; Insertion</em> that when we do <code class="language-plaintext highlighter-rouge">cache.allocate(pid, key, size)</code> we don’t update the linked lists, so effectively the <code class="language-plaintext highlighter-rouge">ItemHandle</code> is not visible to other threads. So doing</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">std</span><span class="o">::</span><span class="n">memcpy</span><span class="p">(</span><span class="n">handle</span><span class="o">-&gt;</span><span class="n">getMemory</span><span class="p">(),</span> <span class="n">value</span><span class="p">.</span><span class="n">data</span><span class="p">(),</span> <span class="n">value</span><span class="p">.</span><span class="n">size</span><span class="p">());</span></code></pre></figure>

<p>in <code class="language-plaintext highlighter-rouge">put()</code> is thread safe. Note that it’s possible multiple threads call <code class="language-plaintext highlighter-rouge">put()</code> on the same key, and the last one to call <code class="language-plaintext highlighter-rouge">insertOrReplace()</code>, which is thread safe, will win.</p>

<h2 id="flash">Flash</h2>

<p>All we’ve discussed so far is about the structure in memory. CacheLib has a second layer of caching backed by Flash. We won’t cover too many details in this post though.</p>

<p>When an eviction happens in memory, there’s an option to save the data in flash. There are some tricks described in [1] to avoid writing to flash excessively due to limited write lifetime.</p>

<p>Once the entry is written to flash it’s also written to an in-memory per-bucket <a href="https://www.kuniga.me/blog/2015/01/29/bloom-filters.html">Bloom filter</a>. During lookup, when the in-memory lookups fail, it will check if the entry is on the bloom filter.</p>

<p>If yes, there’s a chance it exists in flash, so it tries to read the entry from flash. If a match is found, the entry that was in flash is moved to memory again.</p>

<h2 id="conclusion">Conclusion</h2>

<p>I’m having a lot of fun studying these data structures such as CacheLib and <a href="https://www.kuniga.me/blog/2026/08/07/f14.html">F14Map</a>. They have lots of interesting tricks to make it efficient and perform well under concurrent use. I especially liked the fact that an item is a node in multiple linked lists.</p>

<p>These complex data structures also make me think of the joke that tech interviews ask interviewees how to reverse a linked list but that no one uses that in their job. To be fair this is pretty rare or unheard of for many programmers but I found the deeper one goes on the stack the more likely they’ll need Computer Science knowledge.</p>

<p>I was surprised that the paper focuses so much on unification and use cases instead of the technical details (the exception seems to be about writing to flash). Maybe because these are standard tricks in cache implementation, but they felt all novel to me.</p>

<h2 id="references">References</h2>

<ul>
  <li>[1] The CacheLib Caching Engine: Design and Experiences at Scale</li>
  <li>[<a href="https://github.com/facebook/CacheLib">2</a>] Github: CacheLib</li>
</ul>

<h2 id="related-posts">Related Posts</h2>

<p>There are a lot of similarities in how systems memory allocators manage memory. One of them is hierarchy: we see them in arenas in <a href="https://www.kuniga.me/blog/2025/07/15/jemalloc.html">Jemalloc</a> and pools in <a href="https://www.kuniga.me/blog/2026/08/04/velox-memory.html">Velox: Memory</a>, the latter having an entire tree of hierarchy. Velox also has disk spill capabilities, much like CacheLib can “spill” to flash.</p>

<p>At a very high level, an in-process cache is a hash table, but it has substantial differences from a general purpose hash map such as <a href="https://www.kuniga.me/blog/2026/08/07/f14.html">Folly F14 Map</a>. It typically has a fixed size and it evicts entries automatically, which leads to very different design decisions.</p>

<p>Memory allocators also have to worry about fragmentation, which can lead to inefficient use of space. This is also a concern of the <a href="https://www.kuniga.me/blog/2020/07/31/buddy-memory-allocation.html">Buddy Memory Allocation</a>.</p>

<p>In terms of similar use cases, the CPU also has a cache, as we’ve studied in <a href="https://www.kuniga.me/blog/2020/04/24/cpu-cache.html">CPU Cache</a>. We also discussed CDNs before in <a href="https://www.kuniga.me/blog/2019/07/21/content-delivery-network.html">Content Delivery Network</a>.</p>

<p>Finally, speaking of nodes that belong to multiple linked lists, we talked about <em>Dancing Links</em> in <a href="https://www.kuniga.me/blog/2013/04/28/the-algorithm-x-and-the-dancing-links.html">The Algorithm X and the Dancing Links</a> which is a way to represent sparse matrices.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="c++" />
      
        <category term="data structures" />


        <summary type="html"><![CDATA[CacheLib is an open-source C++ library from Meta for constructing in-process caches. At a high level, we can think of it as a hash table in memory with the option to spill to flash storage. In this post we’ll study this library, mainly the in-memory portion based on the paper The CacheLib Caching Engine: Design and Experiences at Scale [1] and the code.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">Asymmetric Numeral Systems</title>
      <link href="https://www.kuniga.me/blog/2026/08/20/ans.html" rel="alternate" type="text/html" title="Asymmetric Numeral Systems" />
      <published>2026-08-20T00:00:00+00:00</published>
      <updated>2026-08-20T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/08/20/ans</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/08/20/ans.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/2026-08-20-ans/ans.jpeg" alt="Cartoon of a bespoke machine to compress a cloud. Generated with Nano Banana." />
</figure>

<p>Jarosław Duda is a Polish professor at the Jagiellonian University in Kraków. He developed a family of entropy coding methods called asymmetric numeral systems (ANS), mainly used in data compression. He wanted these to remain patent-free but has had mixed success.</p>

<p>Google worked with Duda around 2014 in a paper <em>Mixed boolean-token ANS coefficient coding</em> and tried to patent a coder for video, but Duda pushed back and Google abandoned the attempt. In 2019 Microsoft was able to patent a variant and since then other patents have been granted internationally.</p>

<p>A variant of ANS, known as FSE, is used by Meta’s compression library called zstd. I wanted to learn more about it and decided to study this algorithm first.</p>

<!--more-->

<h2 id="setup">Setup</h2>

<p>We’ll develop the Python code as we follow along, both to make the explanations more precise and to define common boilerplate gradually so each code snippet stays shorter. Since we’ll be developing and comparing encoders, we define an abstract class:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">Encoder</span><span class="p">(</span><span class="n">ABC</span><span class="p">):</span>
    <span class="o">@</span><span class="n">abstractmethod</span>
    <span class="k">def</span> <span class="nf">desc</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="s">"Human-friendly description of this encoder"</span>

    <span class="o">@</span><span class="n">abstractmethod</span>
    <span class="k">def</span> <span class="nf">encode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="nb">input</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bytes</span><span class="p">:</span>
        <span class="s">"Gets an input, encodes to bytes"</span>

    <span class="o">@</span><span class="n">abstractmethod</span>
    <span class="k">def</span> <span class="nf">decode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">encoded</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="s">"Decodes bytes to the string"</span></code></pre></figure>

<p>A dummy encoder is simply converting strings to bytes using UTF-8. Not very useful but it gives us a working implementation:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">UTFEncoder</span><span class="p">(</span><span class="n">Encoder</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">desc</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="k">return</span> <span class="s">"UTF-8"</span>

    <span class="k">def</span> <span class="nf">encode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="nb">input</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bytes</span><span class="p">:</span>
        <span class="k">return</span> <span class="nb">input</span><span class="p">.</span><span class="n">encode</span><span class="p">(</span><span class="s">'utf-8'</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">decode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">encoded</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="k">return</span> <span class="n">encoded</span><span class="p">.</span><span class="n">decode</span><span class="p">(</span><span class="s">"utf-8"</span><span class="p">)</span></code></pre></figure>

<p>A simple way to evaluate the encoders is to encode an input, decode it and verify it matches the original input since we’re assuming lossless encoders. We can also compute the compression rate as <code class="language-plaintext highlighter-rouge">(1 - encoded/decoded)</code> and the time it takes to encode and decode.</p>

<details>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="n">encoders</span> <span class="o">=</span> <span class="p">[</span>
    <span class="n">UTFEncoder</span><span class="p">(),</span>
<span class="p">]</span>

<span class="n">decoded_sz</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">data</span><span class="p">)</span>
<span class="k">for</span> <span class="n">encoder</span> <span class="ow">in</span> <span class="n">encoders</span><span class="p">:</span>
    <span class="n">start</span> <span class="o">=</span> <span class="n">time</span><span class="p">.</span><span class="n">perf_counter</span><span class="p">()</span>

    <span class="n">encoded</span> <span class="o">=</span> <span class="n">encoder</span><span class="p">.</span><span class="n">encode</span><span class="p">(</span><span class="n">data</span><span class="p">)</span>
    <span class="n">encoded_sz</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">encoded</span><span class="p">)</span>
    <span class="n">rate</span> <span class="o">=</span> <span class="p">(</span><span class="mi">1</span> <span class="o">-</span> <span class="n">encoded_sz</span><span class="o">/</span><span class="n">decoded_sz</span><span class="p">)</span> <span class="o">*</span> <span class="mi">100</span>

    <span class="n">output</span> <span class="o">=</span> <span class="n">encoder</span><span class="p">.</span><span class="n">decode</span><span class="p">(</span><span class="n">encoded</span><span class="p">)</span>
    <span class="k">assert</span> <span class="n">data</span> <span class="o">==</span> <span class="n">output</span>

    <span class="n">elapsed</span> <span class="o">=</span> <span class="n">time</span><span class="p">.</span><span class="n">perf_counter</span><span class="p">()</span> <span class="o">-</span> <span class="n">start</span>

    <span class="n">rows</span><span class="p">.</span><span class="n">append</span><span class="p">([</span>
        <span class="n">encoder</span><span class="p">.</span><span class="n">desc</span><span class="p">(),</span>
        <span class="n">elapsed</span><span class="p">,</span>
        <span class="n">rate</span><span class="p">,</span>
    <span class="p">])</span>

<span class="k">print</span><span class="p">(</span><span class="n">tabulate</span><span class="p">(</span>
    <span class="n">rows</span><span class="p">,</span>
    <span class="n">headers</span><span class="o">=</span><span class="p">[</span><span class="s">"Encoder"</span><span class="p">,</span> <span class="s">"Time (s)"</span><span class="p">,</span> <span class="s">"Compression Rate"</span><span class="p">],</span>
    <span class="n">tablefmt</span><span class="o">=</span><span class="s">"rounded_grid"</span><span class="p">,</span>
    <span class="n">floatfmt</span><span class="o">=</span><span class="s">".3f"</span><span class="p">,</span>
<span class="p">))</span></code></pre></figure>

</details>

<h2 id="huffman-coding">Huffman Coding</h2>

<p>We wrote about <a href="https://www.kuniga.me/blog/2020/06/11/huffman-coding.html">Huffman coding</a> before. The idea is: given a probability distribution of symbols, we construct the Huffman tree which is a binary tree where symbols are at the leaves. Then we build a map from each symbol to a binary code representing the path to the corresponding leaf (0 is left, 1 is right).</p>

<p>We can then encode an input string character by character as a byte string. This encoding has the property of being prefix-free, which allows us to decode the byte string greedily by using the 0s and 1s to traverse the Huffman tree.</p>

<p>The Huffman encoding minimizes this function:</p>

\[\sum_{i=1}^{n} p_i l_i\]

<p>where $p_i$ is the probability of symbol $i$ and $l_i$ is the length of the path from the root to the leaf containing $i$. We then talked about <strong>entropy</strong> which is defined as:</p>

\[H = - \sum_{i=1}^{n} p_i \log(p_i)\]

<p>and that while the Huffman encoding doesn’t minimize it, it’s within $H + 1$.</p>

<p>Intuitively the gap is that $l_i$ is an integer, while $\log(p_i)$ is a real value. This is where Asymmetric Numeral Systems come in. Before we go there, let’s cover a more familiar concept but with an unfamiliar name: symmetric numeral systems.</p>

<p>We won’t cover the code for Huffman again, but we can assume a class <code class="language-plaintext highlighter-rouge">HuffmanEncoder</code> exists extending <code class="language-plaintext highlighter-rouge">Encoder</code>.</p>

<h2 id="symmetric-numeral-systems">Symmetric Numeral Systems</h2>

<p>Consider how we convert a binary string $b_n b_{n-1} b_{n-2} \cdots b_0$ (most significant bit first) to decimal. In Python it can look like:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">btoi</span><span class="p">(</span><span class="n">bits</span><span class="p">):</span>
    <span class="n">r</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="k">for</span> <span class="n">b</span> <span class="ow">in</span> <span class="n">bits</span><span class="p">:</span>
        <span class="n">r</span> <span class="o">=</span> <span class="n">r</span> <span class="o">*</span> <span class="mi">2</span> <span class="o">+</span> <span class="nb">int</span><span class="p">(</span><span class="n">b</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">r</span></code></pre></figure>

<p>Note how we use one bit per symbol <code class="language-plaintext highlighter-rouge">0</code> or <code class="language-plaintext highlighter-rouge">1</code> and note how the integer roughly doubles each time. Another way to implement this is via:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">encode_bit</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">b</span><span class="p">):</span>
    <span class="n">match</span> <span class="n">b</span><span class="p">:</span>
        <span class="n">case</span> <span class="s">'0'</span><span class="p">:</span>
            <span class="k">return</span> <span class="mi">2</span> <span class="o">*</span> <span class="n">x</span>
        <span class="n">case</span> <span class="s">'1'</span><span class="p">:</span>
            <span class="k">return</span> <span class="mi">2</span> <span class="o">*</span> <span class="n">x</span> <span class="o">+</span> <span class="mi">1</span>

<span class="k">def</span> <span class="nf">btoi</span><span class="p">(</span><span class="n">bits</span><span class="p">):</span>
    <span class="n">r</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="k">for</span> <span class="n">b</span> <span class="ow">in</span> <span class="n">bits</span><span class="p">:</span>
        <span class="n">r</span> <span class="o">=</span> <span class="n">encode_bit</span><span class="p">(</span><span class="n">r</span><span class="p">,</span> <span class="n">b</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">r</span></code></pre></figure>

<p>One way to interpret <code class="language-plaintext highlighter-rouge">encode_bit()</code> is as an explicit map where <code class="language-plaintext highlighter-rouge">0</code> gets the even integers and <code class="language-plaintext highlighter-rouge">1</code> gets the odd ones.  Then we create a mapping from the natural numbers to their respective subset.</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">    0  1  2  3  4  5 ...
0:  0  2  4  6  8 10 ...
1:  1  3  5  7  9 11 ...</code></pre></figure>

<p>Another way to see this is as a partition of the natural numbers into two subsets and the association of one to <code class="language-plaintext highlighter-rouge">0</code> and another to <code class="language-plaintext highlighter-rouge">1</code>. As we know, this function is reversible so we can convert an integer to a string of bits (if we know how many bits we started with).</p>

<p>A different way to see this is as a reversible operation is to look at which partition of the naturals the integer we’re decoding is at. If it’s an even number, it means it was last mapped by a <code class="language-plaintext highlighter-rouge">0</code>, whereas if it’s odd, it was mapped by a <code class="language-plaintext highlighter-rouge">1</code>. This interpretation will be more useful soon.</p>

<p>We can generalize this encoding for an arbitrary base, and thus we can also encode an input that used any alphabet. For example, if we have 3 symbols and the input <code class="language-plaintext highlighter-rouge">ACBAABCBA</code>, we can encode it as an integer by converting this as if it was a string of digits in base 3.</p>

<h2 id="asymmetric-numeral-systems">Asymmetric Numeral Systems</h2>

<p>Suppose now that <code class="language-plaintext highlighter-rouge">0</code>s are 3x more likely than <code class="language-plaintext highlighter-rouge">1</code>s to appear in the input. Intuitively we want to use fewer bits to encode <code class="language-plaintext highlighter-rouge">0</code> than <code class="language-plaintext highlighter-rouge">1</code>. We can now distribute the image non-uniformly: for every 4 numbers we assign the first 3 to <code class="language-plaintext highlighter-rouge">0</code> and the fourth to <code class="language-plaintext highlighter-rouge">1</code>:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">    0  1  2  3  4  5 ...
0:  0  1  2  4  5  6 ...
1:  3  7 11 15 19 23 ...</code></pre></figure>

<p>In the original example, we said each input maps to roughly <code class="language-plaintext highlighter-rouge">2x</code> its value. Now for <code class="language-plaintext highlighter-rouge">1</code> the input grows at <code class="language-plaintext highlighter-rouge">4x</code> rate, but for <code class="language-plaintext highlighter-rouge">0</code> it’s more like <code class="language-plaintext highlighter-rouge">4/3x</code>, which is closer to their distribution!</p>

<p>We can represent this distribution in <code class="language-plaintext highlighter-rouge">encode_bit()</code> via:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">encode_bit</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">b</span><span class="p">):</span>
    <span class="n">match</span> <span class="n">b</span><span class="p">:</span>
        <span class="n">case</span> <span class="s">'0'</span><span class="p">:</span>
            <span class="k">return</span> <span class="mi">4</span> <span class="o">*</span> <span class="p">(</span><span class="n">x</span> <span class="o">//</span> <span class="mi">3</span><span class="p">)</span> <span class="o">+</span> <span class="p">(</span><span class="n">x</span> <span class="o">%</span> <span class="mi">3</span><span class="p">)</span>
        <span class="n">case</span> <span class="s">'1'</span><span class="p">:</span>
            <span class="k">return</span> <span class="mi">4</span> <span class="o">*</span> <span class="n">x</span> <span class="o">+</span> <span class="mi">3</span></code></pre></figure>

<p>This numeral system, in which different digits have different weights, is called <em>Asymmetric Numeral Systems</em> or ANS. As in the symmetric case, we can think of a general base $n$ system in which digit/symbol $i$ occurs with probability $p_i$.</p>

<p>We find a suitable denominator and then the rational that is the closest approximation to the probability. For example, if we have 3 symbols (A, B, C) with probabilities $0.5$, $0.3$ and $0.2$ respectively and we choose a denominator $M = 16$, we can have $A = 8 / 16$, $B = 5 / 16$ and $C = 3 / 16$.</p>

<p>We can then distribute a chunk of 16 integers between them: the first 8 goes to A, the next 5 to B and the last 3 to C:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">0  1  2  3  4  5  6  7  8  9 10 11 12 13 14 15
A  A  A  A  A  A  A  A  B  B  B  B  B  C  C  C</code></pre></figure>

<p>Let $M$ be the chunk size, $f_i$ how many slots of $M$ we assign to symbol $i$, and $o_i$ the offset in the chunk where $i$ starts. So in the example above we have: $f_A = 8, f_B = 5, f_C = 3$, $o_A = 0, o_B = 8, o_C = 13$.</p>

<p>To find to which integer an input $x$ maps for a symbol $i$, we can first find the right chunk by doing $\lfloor{x / f_i\rfloor}$. So for $A$, 0-7 will map to the 1st chunk, 8-15 to the 2nd, etc. Then we compute the offset of that chunk by multiplying by $M$. Now we add the offset of $i$ within that chunk, $o_i$ and finally the offset of the $k$-th copy of $i$ in that segment, $k = x \pmod {f_i}$. The formula is a bit convoluted but you can try with a few examples to convince yourself.</p>

<p>Now to the implementation. We’ll first define the class <code class="language-plaintext highlighter-rouge">SimpleANSEncoder</code> extending <code class="language-plaintext highlighter-rouge">Encoder</code>, which computes $f$ (as <code class="language-plaintext highlighter-rouge">freq</code>) and $o$ (as <code class="language-plaintext highlighter-rouge">offsets</code>):</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="n">FrequencyTable</span> <span class="o">=</span> <span class="n">Sequence</span><span class="p">[</span><span class="nb">tuple</span><span class="p">[</span><span class="nb">str</span><span class="p">,</span> <span class="nb">int</span><span class="p">]]</span>

<span class="k">class</span> <span class="nc">SimpleANSEncoder</span><span class="p">(</span><span class="n">Encoder</span><span class="p">):</span>

    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">raw_freq</span><span class="p">:</span> <span class="n">FrequencyTable</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">M</span> <span class="o">=</span> <span class="mi">2</span><span class="o">**</span><span class="mi">12</span>

        <span class="c1"># least frequent first
</span>        <span class="n">sorted_freq</span> <span class="o">=</span> <span class="nb">sorted</span><span class="p">(</span><span class="n">raw_freq</span><span class="p">,</span> <span class="n">key</span><span class="o">=</span><span class="k">lambda</span> <span class="n">item</span><span class="p">:</span> <span class="n">item</span><span class="p">[</span><span class="mi">1</span><span class="p">])</span>
        <span class="n">total</span> <span class="o">=</span> <span class="nb">sum</span><span class="p">(</span><span class="n">cnt</span> <span class="k">for</span> <span class="n">_</span><span class="p">,</span> <span class="n">cnt</span> <span class="ow">in</span> <span class="n">sorted_freq</span><span class="p">)</span>

        <span class="n">freq_norm</span> <span class="o">=</span> <span class="p">[</span>
            <span class="p">(</span><span class="n">s</span><span class="p">,</span> <span class="nb">max</span><span class="p">(</span><span class="nb">int</span><span class="p">(</span><span class="n">cnt</span><span class="o">/</span><span class="n">total</span> <span class="o">*</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">),</span> <span class="mi">1</span><span class="p">))</span> <span class="k">for</span> <span class="n">s</span><span class="p">,</span> <span class="n">cnt</span> <span class="ow">in</span> <span class="n">sorted_freq</span>
        <span class="p">]</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">offsets</span> <span class="o">=</span> <span class="p">{}</span>
        <span class="n">acc</span> <span class="o">=</span> <span class="mi">0</span>
        <span class="k">for</span> <span class="n">s</span><span class="p">,</span> <span class="n">f</span> <span class="ow">in</span> <span class="n">freq_norm</span><span class="p">:</span>
            <span class="bp">self</span><span class="p">.</span><span class="n">offsets</span><span class="p">[</span><span class="n">s</span><span class="p">]</span> <span class="o">=</span> <span class="n">acc</span>
            <span class="n">acc</span> <span class="o">+=</span> <span class="n">f</span>

        <span class="c1"># tweak last symbol freq so it adds up to M
</span>        <span class="n">last</span> <span class="o">=</span> <span class="n">freq_norm</span><span class="p">[</span><span class="o">-</span><span class="mi">1</span><span class="p">]</span>
        <span class="n">freq_norm</span><span class="p">[</span><span class="o">-</span><span class="mi">1</span><span class="p">]</span> <span class="o">=</span> <span class="p">(</span><span class="n">last</span><span class="p">[</span><span class="mi">0</span><span class="p">],</span> <span class="n">last</span><span class="p">[</span><span class="mi">1</span><span class="p">]</span> <span class="o">+</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span> <span class="o">-</span> <span class="n">acc</span><span class="p">)</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">freq</span> <span class="o">=</span> <span class="nb">dict</span><span class="p">(</span><span class="n">freq_norm</span><span class="p">)</span></code></pre></figure>

<p>The code is a bit complicated because we want to make sure that <code class="language-plaintext highlighter-rouge">sum(prob) == M</code>, while we’re rounding floats to integers. A trick is to have the most frequent symbol have <code class="language-plaintext highlighter-rouge">M</code> - the sum of the probabilities of the least frequent items.</p>

<p>For incorporating a symbol into the integer <code class="language-plaintext highlighter-rouge">x</code> we follow the formula above:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">encode_symbol</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">symbol</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
    <span class="n">f</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">freq</span><span class="p">[</span><span class="n">symbol</span><span class="p">]</span>
    <span class="n">off</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">offsets</span><span class="p">[</span><span class="n">symbol</span><span class="p">]</span>
    <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span> <span class="o">*</span> <span class="p">(</span><span class="n">x</span> <span class="o">//</span> <span class="n">f</span><span class="p">)</span> <span class="o">+</span> <span class="p">(</span><span class="n">x</span> <span class="o">%</span> <span class="n">f</span><span class="p">)</span> <span class="o">+</span> <span class="n">off</span></code></pre></figure>

<p>The <code class="language-plaintext highlighter-rouge">encode()</code> consists in building the giant integer and encoding it as a byte string. We can use <code class="language-plaintext highlighter-rouge">BytesIO</code> to read/write to this byte string:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">encode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">:</span> <span class="n">BytesIO</span><span class="p">,</span> <span class="n">x</span><span class="p">:</span> <span class="nb">int</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bytes</span><span class="p">:</span>
    <span class="n">cursor</span><span class="p">.</span><span class="n">write</span><span class="p">(</span><span class="n">x</span><span class="p">.</span><span class="n">to_bytes</span><span class="p">(</span><span class="mi">4</span><span class="p">,</span> <span class="n">byteorder</span><span class="o">=</span><span class="s">"big"</span><span class="p">))</span>

<span class="k">def</span> <span class="nf">encode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="nb">input</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bytes</span><span class="p">:</span>
    <span class="n">r</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="k">for</span> <span class="n">c</span> <span class="ow">in</span> <span class="nb">input</span><span class="p">:</span>
        <span class="n">r</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">encode_symbol</span><span class="p">(</span><span class="n">r</span><span class="p">,</span> <span class="n">c</span><span class="p">)</span>

    <span class="n">cursor</span> <span class="o">=</span> <span class="n">BytesIO</span><span class="p">()</span>
    <span class="n">encode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="nb">input</span><span class="p">))</span>
    <span class="n">encode_bigint</span><span class="p">(</span><span class="n">cursor</span><span class="p">,</span> <span class="n">r</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">cursor</span><span class="p">.</span><span class="n">getvalue</span><span class="p">()</span></code></pre></figure>

<p>We also include the length of the original text because otherwise the decoder doesn’t know how many symbols to generate back. For example, in the binary to decimal encoding, leading zeros would be lost during encoding, so <code class="language-plaintext highlighter-rouge">0001</code> gets encoded as <code class="language-plaintext highlighter-rouge">1</code> and decoded as <code class="language-plaintext highlighter-rouge">1</code>.</p>

<p>The decoding is only a bit more complicated. Finding the symbol is easy: we just need to mod $M$, since this gives the offset within a chunk and then we can do a binary search on <code class="language-plaintext highlighter-rouge">off</code> to find to which offset it belongs. Alternatively we store an array of size $M$ with the symbols repeated, which we can compute upfront, in <code class="language-plaintext highlighter-rouge">__init__()</code>. In our example:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">SimpleANSEncoder</span><span class="p">(</span><span class="n">Encoder</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">raw_freq</span><span class="p">:</span> <span class="n">FrequencyTable</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
        <span class="c1"># ...
</span>        <span class="bp">self</span><span class="p">.</span><span class="n">lookup</span> <span class="o">=</span> <span class="s">""</span><span class="p">.</span><span class="n">join</span><span class="p">(</span><span class="n">s</span> <span class="o">*</span> <span class="bp">self</span><span class="p">.</span><span class="n">freq</span><span class="p">[</span><span class="n">s</span><span class="p">]</span> <span class="k">for</span> <span class="n">s</span><span class="p">,</span> <span class="n">_</span> <span class="ow">in</span> <span class="n">sorted_freq</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">get_symbol</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">lookup</span><span class="p">[</span><span class="n">x</span> <span class="o">%</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">]</span></code></pre></figure>

<p>The <code class="language-plaintext highlighter-rouge">decode_symbol()</code> is roughly the inverse of <code class="language-plaintext highlighter-rouge">encode_symbol</code> once we have the symbol:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">decode_symbol</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">:</span> <span class="nb">int</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">tuple</span><span class="p">[</span><span class="nb">str</span><span class="p">,</span> <span class="nb">int</span><span class="p">]:</span>
    <span class="n">symbol</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_symbol</span><span class="p">(</span><span class="n">x</span><span class="p">)</span>
    <span class="n">p</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">freq</span><span class="p">[</span><span class="n">symbol</span><span class="p">]</span>
    <span class="n">off</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">offsets</span><span class="p">[</span><span class="n">symbol</span><span class="p">]</span>
    <span class="k">return</span> <span class="n">symbol</span><span class="p">,</span> <span class="n">p</span> <span class="o">*</span> <span class="p">(</span><span class="n">x</span> <span class="o">//</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">)</span> <span class="o">+</span> <span class="p">(</span><span class="n">x</span> <span class="o">%</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">)</span> <span class="o">-</span> <span class="n">off</span></code></pre></figure>

<p>And so is the <code class="language-plaintext highlighter-rouge">decode()</code>:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">decode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">:</span> <span class="n">BytesIO</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
    <span class="k">return</span> <span class="nb">int</span><span class="p">.</span><span class="n">from_bytes</span><span class="p">(</span><span class="n">cursor</span><span class="p">.</span><span class="n">read</span><span class="p">(</span><span class="mi">4</span><span class="p">),</span> <span class="n">byteorder</span><span class="o">=</span><span class="s">"big"</span><span class="p">)</span>

<span class="k">def</span> <span class="nf">decode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">encoded</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
    <span class="n">cursor</span> <span class="o">=</span> <span class="n">BytesIO</span><span class="p">(</span><span class="n">encoded</span><span class="p">)</span>
    <span class="n">sz</span> <span class="o">=</span> <span class="n">decode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">)</span>
    <span class="n">value</span> <span class="o">=</span> <span class="n">decode_bigint</span><span class="p">(</span><span class="n">cursor</span><span class="p">)</span>

    <span class="n">output</span> <span class="o">=</span> <span class="s">''</span>
    <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">sz</span><span class="p">):</span>
        <span class="n">symbol</span><span class="p">,</span> <span class="n">value</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">decode_symbol</span><span class="p">(</span><span class="n">value</span><span class="p">)</span>
        <span class="n">output</span> <span class="o">+=</span> <span class="n">symbol</span>
    <span class="k">return</span> <span class="n">output</span><span class="p">[::</span><span class="o">-</span><span class="mi">1</span><span class="p">]</span></code></pre></figure>

<h3 id="efficiency">Efficiency</h3>

<p>The rational approximation probability of a symbol is $q_i = f_i / M$. The rough growth of <code class="language-plaintext highlighter-rouge">x</code> when going through <code class="language-plaintext highlighter-rouge">encode()</code> is roughly dominated by $M / f_i$, so $1 / q_i$. The approximate number of bits in this factor is $\log_2 1/q_i = - \log_2 q_i$. So the expected cost per symbol is a weighted sum:</p>

\[\mathbb{E}[L] = \sum_{i} p_i (- \log_2 q_i) = -\sum_{i} p_i \log_2 q_i\]

<p>Where $L$ is the cost of a random variable representing a symbol. This expected value is also equal to the cross-entropy which indicates how many bits on average we need if the symbols come from a distribution $P$, but we encode it using a distribution $Q$ and is denoted by $H(P, Q)$.</p>

<p>We can compare this with the true entropy:</p>

\[-\sum_{i} p_i \log_2 p_i\]

<p>which we’ve seen in Huffman coding is the theoretical optimal. So the closer we can approximate the rational $q_i$ to $p_i$ the better, so in theory we could use a gigantic value for $M$ but in practice working with large values is prohibitive.</p>

<p>Speaking of large integers, encoding an input as an integer has the major downside of the integer growing exponentially with the size of the input.</p>

<h2 id="renormalization">Renormalization</h2>

<p>One way to avoid working with arbitrarily large integers is to move the lowest bits to a bit stream whenever it grows too big. It will be part of the encoded output but is not going to participate in future multiplications. The idea is to have the invariant $M \le x \lt 2M$. If multiplying $x$ by a factor would tip it over $2M$ we first reduce it.</p>

<p>We define a class <code class="language-plaintext highlighter-rouge">RANSEncoder</code> extending from <code class="language-plaintext highlighter-rouge">SimpleANSEncoder</code> since they share a lot of the methods. For encoding, <code class="language-plaintext highlighter-rouge">encode_symbol()</code> is the same, but now we need to emit bits periodically. We use <code class="language-plaintext highlighter-rouge">bitarray</code> for that:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">encode_bitarray</span><span class="p">(</span><span class="n">cursor</span><span class="p">:</span> <span class="n">BytesIO</span><span class="p">,</span> <span class="n">x</span><span class="p">:</span> <span class="n">bitarray</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
    <span class="n">encode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="n">x</span><span class="p">))</span>
    <span class="n">cursor</span><span class="p">.</span><span class="n">write</span><span class="p">(</span><span class="n">x</span><span class="p">.</span><span class="n">tobytes</span><span class="p">())</span>

<span class="k">class</span> <span class="nc">RANSEncoder</span><span class="p">(</span><span class="n">SimpleANSEncoder</span><span class="p">):</span>

    <span class="c1"># ...
</span>
    <span class="k">def</span> <span class="nf">encode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="nb">input</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bytes</span><span class="p">:</span>
        <span class="n">stream</span> <span class="o">=</span> <span class="n">bitarray</span><span class="p">()</span>
        <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span>
        <span class="k">for</span> <span class="n">b</span> <span class="ow">in</span> <span class="nb">input</span><span class="p">:</span>
            <span class="k">while</span> <span class="p">(</span><span class="n">y</span> <span class="p">:</span><span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">encode_symbol</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">b</span><span class="p">))</span> <span class="o">&gt;=</span> <span class="mi">2</span> <span class="o">*</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">:</span>
                <span class="n">stream</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">x</span> <span class="o">&amp;</span> <span class="mi">1</span><span class="p">)</span>
                <span class="n">x</span> <span class="o">&gt;&gt;=</span> <span class="mi">1</span>
            <span class="n">x</span> <span class="o">=</span> <span class="n">y</span>

        <span class="n">cursor</span> <span class="o">=</span> <span class="n">BytesIO</span><span class="p">()</span>
        <span class="n">encode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="nb">input</span><span class="p">))</span>
        <span class="n">encode_bitarray</span><span class="p">(</span><span class="n">cursor</span><span class="p">,</span> <span class="n">stream</span><span class="p">)</span>
        <span class="n">encode_bigint</span><span class="p">(</span><span class="n">cursor</span><span class="p">,</span> <span class="n">x</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">cursor</span><span class="p">.</span><span class="n">getvalue</span><span class="p">()</span></code></pre></figure>

<p>Note how we start $x$ as $M$ as opposed to $0$ as we did before, so that we maintain the invariant $M \le x \lt 2M$ inside the loop.</p>

<p>For decoding, we can also maintain the invariant and consume bits from the stream to restore it:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">decode_bitarray</span><span class="p">(</span><span class="n">cursor</span><span class="p">:</span> <span class="n">BytesIO</span><span class="p">):</span>
    <span class="n">x</span> <span class="o">=</span> <span class="n">bitarray</span><span class="p">()</span>
    <span class="n">bit_cnt</span> <span class="o">=</span> <span class="n">decode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">.</span><span class="n">read</span><span class="p">(</span><span class="mi">4</span><span class="p">))</span>
    <span class="n">byte_cnt</span> <span class="o">=</span> <span class="p">(</span><span class="n">bit_cnt</span> <span class="o">+</span> <span class="mi">7</span><span class="p">)</span> <span class="o">//</span> <span class="mi">8</span>
    <span class="n">x</span><span class="p">.</span><span class="n">frombytes</span><span class="p">(</span><span class="n">cursor</span><span class="p">.</span><span class="n">read</span><span class="p">(</span><span class="n">byte_cnt</span><span class="p">))</span>
    <span class="n">x</span> <span class="o">=</span> <span class="n">x</span><span class="p">[:</span><span class="n">bit_cnt</span><span class="p">]</span>  <span class="c1"># remove padding
</span>    <span class="k">return</span> <span class="n">x</span>

<span class="k">class</span> <span class="nc">RANSEncoder</span><span class="p">(</span><span class="n">SimpleANSEncoder</span><span class="p">):</span>

    <span class="c1"># ...
</span>
    <span class="k">def</span> <span class="nf">decode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">encoded</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="n">cursor</span> <span class="o">=</span> <span class="n">BytesIO</span><span class="p">(</span><span class="n">encoded</span><span class="p">)</span>
        <span class="n">input_size</span> <span class="o">=</span> <span class="n">decode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">.</span><span class="n">read</span><span class="p">(</span><span class="mi">4</span><span class="p">))</span>
        <span class="n">stream</span> <span class="o">=</span> <span class="n">decode_bitarray</span><span class="p">(</span><span class="n">cursor</span><span class="p">)</span>

        <span class="n">out</span> <span class="o">=</span> <span class="s">''</span>
        <span class="n">x</span> <span class="o">=</span> <span class="n">decode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">.</span><span class="n">read</span><span class="p">())</span>
        <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">input_size</span><span class="p">):</span>
            <span class="n">s</span><span class="p">,</span> <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">decode_symbol</span><span class="p">(</span><span class="n">x</span><span class="p">)</span>
            <span class="k">while</span> <span class="n">x</span> <span class="o">&lt;</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">:</span>
                <span class="n">bit</span> <span class="o">=</span> <span class="n">stream</span><span class="p">.</span><span class="n">pop</span><span class="p">()</span>
                <span class="n">x</span> <span class="o">=</span> <span class="p">(</span><span class="n">x</span> <span class="o">&lt;&lt;</span> <span class="mi">1</span><span class="p">)</span> <span class="o">|</span> <span class="n">bit</span>
            <span class="n">out</span> <span class="o">+=</span> <span class="n">s</span>

        <span class="k">return</span> <span class="n">out</span><span class="p">[::</span><span class="o">-</span><span class="mi">1</span><span class="p">]</span></code></pre></figure>

<p>Not only does this allow us to operate with a small integer range, the set of values we pass for <code class="language-plaintext highlighter-rouge">x</code> to <code class="language-plaintext highlighter-rouge">encode_symbol()</code> is bounded between <code class="language-plaintext highlighter-rouge">[M, 2M[</code>, which is very useful as we’ll see next.</p>

<h2 id="tabular-ans">Tabular ANS</h2>

<p>Recall that in our 3-symbol example with distinct weights we laid them out like this:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">0  1  2  3  4  5  6  7  8  9 10 11 12 13 14 15
A  A  A  A  A  A  A  A  B  B  B  B  B  C  C  C</code></pre></figure>

<p>First the <code class="language-plaintext highlighter-rouge">A</code>’s, then the <code class="language-plaintext highlighter-rouge">B</code>’s and then the <code class="language-plaintext highlighter-rouge">C</code>’s. The problem with this approach is that <code class="language-plaintext highlighter-rouge">C</code> always gets penalized. For example, if the input is, say 1, and the symbol is <code class="language-plaintext highlighter-rouge">C</code>, it will be mapped to 14, while B gets mapped to 9 and A gets mapped to 1. So <code class="language-plaintext highlighter-rouge">C</code> grows a lot faster.</p>

<p>It will be more balanced if we interleave the symbols more evenly within one batch, for example:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">0  1  2  3  4  5  6  7  8  9 10 11 12 13 14 15
A  B  A  C  A  B  A  B  A  C  A  B  A  B  A  C</code></pre></figure>

<p>Now for input 1, <code class="language-plaintext highlighter-rouge">A</code> maps to 2, <code class="language-plaintext highlighter-rouge">B</code> to 5 and <code class="language-plaintext highlighter-rouge">C</code> to 9. The problem with this arbitrary order is that it becomes much harder to devise a formula that maps integers to their corresponding output. That’s where the renormalization helps: if we have a fixed range of values of input (<code class="language-plaintext highlighter-rouge">[M, 2M[</code>), we can write a table with <code class="language-plaintext highlighter-rouge">M</code> entries that map them exactly to the order above! This variant is called the <em>Tabular ANS</em>.</p>

<p>Let’s create the <code class="language-plaintext highlighter-rouge">TRANSEncoder</code> also extending from <code class="language-plaintext highlighter-rouge">SimpleANSEncoder</code>. The main difference on the initialization is that we’ll “shuffle” the <code class="language-plaintext highlighter-rouge">lookup</code> array and then pre-compute the encode and decode table.</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">TRANSEncoder</span><span class="p">(</span><span class="n">SimpleANSEncoder</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">raw_freq</span><span class="p">:</span> <span class="n">FrequencyTable</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
        <span class="nb">super</span><span class="p">().</span><span class="n">__init__</span><span class="p">(</span><span class="n">raw_freq</span><span class="p">)</span>

        <span class="n">step</span> <span class="o">=</span> <span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">M</span> <span class="o">&gt;&gt;</span> <span class="mi">1</span><span class="p">)</span> <span class="o">+</span> <span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">M</span> <span class="o">&gt;&gt;</span> <span class="mi">3</span><span class="p">)</span> <span class="o">+</span> <span class="mi">3</span>
        <span class="n">lookup</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="nb">str</span><span class="p">]</span> <span class="o">=</span> <span class="p">[</span><span class="s">''</span><span class="p">]</span> <span class="o">*</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span>

        <span class="n">pos</span> <span class="o">=</span> <span class="mi">0</span>
        <span class="k">for</span> <span class="n">symbol</span><span class="p">,</span> <span class="n">cnt</span> <span class="ow">in</span> <span class="bp">self</span><span class="p">.</span><span class="n">freq</span><span class="p">.</span><span class="n">items</span><span class="p">():</span>
            <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">cnt</span><span class="p">):</span>
                <span class="n">lookup</span><span class="p">[</span><span class="n">pos</span><span class="p">]</span> <span class="o">=</span> <span class="n">symbol</span>
                <span class="n">pos</span> <span class="o">=</span> <span class="p">(</span><span class="n">pos</span> <span class="o">+</span> <span class="n">step</span><span class="p">)</span> <span class="o">%</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">lookup</span> <span class="o">=</span> <span class="n">lookup</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">precompute_encode</span><span class="p">()</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">precompute_decode</span><span class="p">()</span></code></pre></figure>

<p>The method <code class="language-plaintext highlighter-rouge">precompute_encode()</code> is analogous to <code class="language-plaintext highlighter-rouge">RANSEncoder</code>’s <code class="language-plaintext highlighter-rouge">encode()</code> but it uses the <code class="language-plaintext highlighter-rouge">positions</code> computed above. It returns a table that for each <code class="language-plaintext highlighter-rouge">M &lt;= x &lt; 2*M</code> and symbol <code class="language-plaintext highlighter-rouge">s</code>, stores a pair <code class="language-plaintext highlighter-rouge">(x, bits)</code>, where <code class="language-plaintext highlighter-rouge">x</code> is the new value of <code class="language-plaintext highlighter-rouge">x</code> after incorporating <code class="language-plaintext highlighter-rouge">s</code> and the bits that will go into the stream.</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">precompute_encode</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
    <span class="n">positions</span> <span class="o">=</span> <span class="n">defaultdict</span><span class="p">(</span><span class="nb">list</span><span class="p">)</span>
    <span class="k">for</span> <span class="n">p</span><span class="p">,</span> <span class="n">s</span> <span class="ow">in</span> <span class="nb">enumerate</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">lookup</span><span class="p">):</span>
        <span class="n">positions</span><span class="p">[</span><span class="n">s</span><span class="p">].</span><span class="n">append</span><span class="p">(</span><span class="n">p</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">encode_symbol</span><span class="p">(</span><span class="n">x</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">s</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
        <span class="n">slots</span> <span class="o">=</span> <span class="n">positions</span><span class="p">[</span><span class="n">s</span><span class="p">]</span>
        <span class="n">f</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">slots</span><span class="p">)</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span> <span class="o">*</span> <span class="p">(</span><span class="n">x</span> <span class="o">//</span> <span class="n">f</span><span class="p">)</span> <span class="o">+</span> <span class="n">slots</span><span class="p">[</span><span class="n">x</span> <span class="o">%</span> <span class="n">f</span><span class="p">]</span>

    <span class="bp">self</span><span class="p">.</span><span class="n">encode_table</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="nb">dict</span><span class="p">[</span><span class="nb">str</span><span class="p">,</span> <span class="n">EncodeEntry</span><span class="p">]]</span> <span class="o">=</span> <span class="p">[</span>
        <span class="p">{}</span> <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">)</span>
    <span class="p">]</span>
    <span class="k">for</span> <span class="n">x0</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">,</span> <span class="mi">2</span> <span class="o">*</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">):</span>
        <span class="k">for</span> <span class="n">s</span> <span class="ow">in</span> <span class="bp">self</span><span class="p">.</span><span class="n">freq</span><span class="p">:</span>
            <span class="n">x</span> <span class="o">=</span> <span class="n">x0</span>

            <span class="n">slots</span> <span class="o">=</span> <span class="n">positions</span><span class="p">[</span><span class="n">s</span><span class="p">]</span>
            <span class="n">f</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">slots</span><span class="p">)</span>
            <span class="n">bits</span> <span class="o">=</span> <span class="n">bitarray</span><span class="p">()</span>
            <span class="k">while</span> <span class="p">(</span><span class="n">y</span> <span class="p">:</span><span class="o">=</span> <span class="n">encode_symbol</span><span class="p">(</span><span class="n">x</span><span class="p">,</span> <span class="n">s</span><span class="p">))</span> <span class="o">&gt;=</span> <span class="mi">2</span> <span class="o">*</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">:</span>
                <span class="n">bits</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">x</span> <span class="o">&amp;</span> <span class="mi">1</span><span class="p">)</span>
                <span class="n">x</span> <span class="o">&gt;&gt;=</span> <span class="mi">1</span>

            <span class="bp">self</span><span class="p">.</span><span class="n">encode_table</span><span class="p">[</span><span class="n">x0</span> <span class="o">-</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">][</span><span class="n">s</span><span class="p">]</span> <span class="o">=</span> <span class="p">(</span>
                <span class="n">y</span><span class="p">,</span>
                <span class="n">bits</span><span class="p">,</span>
            <span class="p">)</span></code></pre></figure>

<p>With this table, encoding becomes very simple (omitting the writes):</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">encode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="nb">input</span><span class="p">:</span> <span class="nb">str</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bytes</span><span class="p">:</span>
    <span class="n">stream</span> <span class="o">=</span> <span class="n">bitarray</span><span class="p">()</span>
    <span class="n">x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span>
    <span class="k">for</span> <span class="n">b</span> <span class="ow">in</span> <span class="nb">input</span><span class="p">:</span>
        <span class="n">x</span><span class="p">,</span> <span class="n">bits</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">encode_table</span><span class="p">[</span><span class="n">x</span> <span class="o">-</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">][</span><span class="n">b</span><span class="p">]</span>
        <span class="n">stream</span> <span class="o">+=</span> <span class="n">bits</span>
    <span class="c1"># ...</span></code></pre></figure>

<p>The decode table only depends on <code class="language-plaintext highlighter-rouge">M &lt;= x &lt; 2*M</code> and it maps to a pair: the previous state and how many bits it needs to consume from the stream to grow <code class="language-plaintext highlighter-rouge">x</code> back to the range.</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">precompute_decode</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="bp">None</span><span class="p">:</span>
    <span class="n">cnt</span> <span class="o">=</span> <span class="n">defaultdict</span><span class="p">(</span><span class="nb">int</span><span class="p">)</span>
    <span class="n">decode_table</span> <span class="o">=</span> <span class="p">[]</span>
    <span class="k">for</span> <span class="n">s</span> <span class="ow">in</span> <span class="bp">self</span><span class="p">.</span><span class="n">lookup</span><span class="p">:</span>
        <span class="n">rank</span> <span class="o">=</span> <span class="n">cnt</span><span class="p">[</span><span class="n">s</span><span class="p">]</span>
        <span class="n">cnt</span><span class="p">[</span><span class="n">s</span><span class="p">]</span> <span class="o">+=</span> <span class="mi">1</span>

        <span class="n">prev_x</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">freq</span><span class="p">[</span><span class="n">s</span><span class="p">]</span> <span class="o">+</span> <span class="n">rank</span>
        <span class="n">bit_cnt</span> <span class="o">=</span> <span class="mi">0</span>
        <span class="k">while</span> <span class="p">(</span><span class="n">prev_x</span> <span class="o">&lt;&lt;</span> <span class="n">bit_cnt</span><span class="p">)</span> <span class="o">&lt;</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span><span class="p">:</span>
            <span class="n">bit_cnt</span> <span class="o">+=</span> <span class="mi">1</span>

        <span class="n">prev_x</span> <span class="o">&lt;&lt;=</span> <span class="n">bit_cnt</span>

        <span class="n">decode_table</span><span class="p">.</span><span class="n">append</span><span class="p">((</span>
            <span class="n">prev_x</span><span class="p">,</span>
            <span class="n">bit_cnt</span>
        <span class="p">))</span>
    <span class="bp">self</span><span class="p">.</span><span class="n">decode_table</span>  <span class="o">=</span> <span class="n">decode_table</span></code></pre></figure>

<p>Decoding becomes:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">decode</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">encoded</span><span class="p">:</span> <span class="nb">bytes</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
    <span class="n">cursor</span> <span class="o">=</span> <span class="n">BytesIO</span><span class="p">(</span><span class="n">encoded</span><span class="p">)</span>
    <span class="n">input_size</span> <span class="o">=</span> <span class="n">decode_int</span><span class="p">(</span><span class="n">cursor</span><span class="p">)</span>
    <span class="n">stream</span> <span class="o">=</span> <span class="n">decode_bitarray</span><span class="p">(</span><span class="n">cursor</span><span class="p">)</span>

    <span class="n">out</span> <span class="o">=</span> <span class="s">''</span>
    <span class="n">x</span> <span class="o">=</span> <span class="n">decode_bigint</span><span class="p">(</span><span class="n">cursor</span><span class="p">)</span>
    <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">input_size</span><span class="p">):</span>
        <span class="n">off</span> <span class="o">=</span> <span class="n">x</span> <span class="o">-</span> <span class="bp">self</span><span class="p">.</span><span class="n">M</span>
        <span class="n">s</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_symbol</span><span class="p">(</span><span class="n">off</span><span class="p">)</span>
        <span class="n">base</span><span class="p">,</span> <span class="n">bit_cnt</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">decode_table</span><span class="p">[</span><span class="n">off</span><span class="p">]</span>

        <span class="n">suffix</span> <span class="o">=</span> <span class="mi">0</span>
        <span class="k">for</span> <span class="n">_</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">bit_cnt</span><span class="p">):</span>
            <span class="n">suffix</span> <span class="o">=</span> <span class="p">(</span><span class="n">suffix</span> <span class="o">&lt;&lt;</span> <span class="mi">1</span><span class="p">)</span> <span class="o">|</span> <span class="n">stream</span><span class="p">.</span><span class="n">pop</span><span class="p">()</span>

        <span class="n">x</span> <span class="o">=</span> <span class="n">base</span> <span class="o">|</span> <span class="n">suffix</span>
        <span class="n">out</span> <span class="o">+=</span> <span class="n">s</span>

    <span class="k">return</span> <span class="n">out</span><span class="p">[::</span><span class="o">-</span><span class="mi">1</span><span class="p">]</span></code></pre></figure>

<h2 id="experiments">Experiments</h2>

<p>I used Carroll’s <em>Alice in Wonderland</em> as a training dataset to estimate the character frequencies, then encoded Shakespeare’s <em>As You Like It</em> (125k characters):</p>

<table>
  <thead>
    <tr>
      <th>Encoder</th>
      <th style="text-align: right">Time (s)</th>
      <th style="text-align: right">Compression Rate</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>UTF-8</td>
      <td style="text-align: right">0.00</td>
      <td style="text-align: right">0.0</td>
    </tr>
    <tr>
      <td>Huffman</td>
      <td style="text-align: right">0.04</td>
      <td style="text-align: right">34.0</td>
    </tr>
    <tr>
      <td>ANS</td>
      <td style="text-align: right">26.5</td>
      <td style="text-align: right">36.2</td>
    </tr>
    <tr>
      <td>rANS</td>
      <td style="text-align: right">0.15</td>
      <td style="text-align: right">36.0</td>
    </tr>
    <tr>
      <td>tANS</td>
      <td style="text-align: right">0.83</td>
      <td style="text-align: right">36.0</td>
    </tr>
  </tbody>
</table>

<p>As expected, the no-op UTF-8 is pretty efficient! But it doesn’t compress anything. Huffman is very fast and is only slightly worse compression than ANS. Working with gigantic integers is very slow.</p>

<p>tANS was slower than rANS mostly because the overhead of constructing the tables wasn’t enough to pay off for 125k characters. To verify that, I also tried encoding a bigger text ($10^8$ characters):</p>

<table>
  <thead>
    <tr>
      <th>Encoder</th>
      <th style="text-align: right">Time (s)</th>
      <th style="text-align: right">Compression Rate</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>UTF-8</td>
      <td style="text-align: right">0.02</td>
      <td style="text-align: right">0.0</td>
    </tr>
    <tr>
      <td>Huffman</td>
      <td style="text-align: right">19.1</td>
      <td style="text-align: right">44.0</td>
    </tr>
    <tr>
      <td>rANS</td>
      <td style="text-align: right">111.3</td>
      <td style="text-align: right">44.0</td>
    </tr>
    <tr>
      <td>tANS</td>
      <td style="text-align: right">57.6</td>
      <td style="text-align: right">45.1</td>
    </tr>
  </tbody>
</table>

<p>Here the overhead paid off for tANS. It also achieved a better compression rate with the more spread out symbols in the chunk.</p>

<h2 id="conclusion">Conclusion</h2>

<p>I found it hard to grok ANS at first until realizing it is, in a way, a generalization of the binary to decimal algorithm!</p>

<p>I found it difficult to implement these in Python, and got a lot of “off-by-one” errors. Luckily, testing a lossless encoder is relatively easy, we just need to test the result is the same as the input.</p>

<h2 id="related-posts">Related Posts</h2>

<p>In <a href="https://www.kuniga.me/blog/2023/09/16/cardinality-of-complex.html">The Cardinality of Complex Numbers</a> we talk about bijective mapping between $\mathbb{C}$ and $\mathbb{R}$, which one can see as a lossless encoding. This also vaguely reminds me of the Gödel number system which maps mathematical expressions to natural numbers!</p>

<p>One of the most surprising coincidences is that in the recent post about <a href="https://www.kuniga.me/blog/2026/08/07/f14.html">Folly F14 Map</a> we discussed the idea of “shuffling” elements across chunks much in the same way <code class="language-plaintext highlighter-rouge">TRANSEncoder</code> shuffles the symbols over the array. Both choose the size to be a power of 2 and the stride or step to be an odd number.</p>

<p>Another connection is that Folly F14 Map is a hash table and the first hashing algorithm I learned and possibly the only one I ever implemented is related to <em>Symmetric Numeral System</em>: we treat the key string as a number in base, say 128 (for ASCII), and then convert it to an decimal modulo a prime number.</p>

<p>Like Huffman, ANS is a lossless compression, but in many cases a lossy compression is a tradeoff we can take, such as in <a href="https://www.kuniga.me/blog/2021/05/13/lpc-in-python.html">Linear Predictive Coding</a> and <a href="https://www.kuniga.me/blog/2021/11/29/t-digest.html">T-Digest</a>.</p>

<p>Finally, a weaker connection is with <a href="https://www.kuniga.me/blog/2017/09/01/numerical-representations-as-inspiration-for-data-structures.html">Numerical Representations as inspiration for Data Structures</a>, because it’s also based on number systems.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="python" />


        <summary type="html"><![CDATA[Jarosław Duda is a Polish professor at the Jagiellonian University in Kraków. He developed a family of entropy coding methods called asymmetric numeral systems (ANS), mainly used in data compression. He wanted these to remain patent-free but has had mixed success. Google worked with Duda around 2014 in a paper Mixed boolean-token ANS coefficient coding and tried to patent a coder for video, but Duda pushed back and Google abandoned the attempt. In 2019 Microsoft was able to patent a variant and since then other patents have been granted internationally. A variant of ANS, known as FSE, is used by Meta’s compression library called zstd. I wanted to learn more about it and decided to study this algorithm first.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">Euclidean Minimum Spanning Tree</title>
      <link href="https://www.kuniga.me/blog/2026/08/17/euclidean-mst.html" rel="alternate" type="text/html" title="Euclidean Minimum Spanning Tree" />
      <published>2026-08-17T00:00:00+00:00</published>
      <updated>2026-08-17T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/08/17/euclidean-mst</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/08/17/euclidean-mst.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/2026-08-17-euclidean-mst/mst-logo.png" alt="MST Logo." />
</figure>

<p>Otakar Borůvka was a Czech mathematician who is best known for his work in graph theory. Once, his friend Jindřich Saxel, an employee of the West Moravian Power Company, asked him for help optimizing electric distribution networks.</p>

<p>Borůvka modeled the problem as the minimum spanning tree problem and then came up with the first known algorithm to solve it, now known as the Borůvka algorithm.</p>

<p>In this post we’ll explore the Borůvka algorithm combined with <a href="https://www.kuniga.me/blog/2026/07/31/kd-tree.html">KD-trees</a> to solve the Euclidean Minimum Spanning Tree problem more efficiently.</p>

<!--more-->

<h2 id="problem">Problem</h2>

<p>The Euclidean Minimum Spanning Tree problem (EMST) consists in finding the <a href="https://en.wikipedia.org/wiki/Minimum_spanning_tree">minimum spanning tree</a> (MST) of a set of $N$ points in the Euclidean space.</p>

<p>Algorithms such as Kruskal can find the MST of a graph $G(V, E)$ in $O(\abs{E} \log \abs{E})$. However in EMST the edges are implicit. The graph is a complete one where the weight of the edge between two points is their Euclidean distance, so a naive implementation consisting in computing the edges explicitly leads to a $O(N^2 \log N)$ algorithm.</p>

<h2 id="solution">Solution</h2>

<p>In this post we’ll explore a more efficient implementation using the Borůvka algorithm with <a href="https://www.kuniga.me/blog/2026/07/31/kd-tree.html">KD-trees</a> which runs closer to $O(N \log^2 N)$ on average, even though the worst case is $O(N^2 \log N)$.</p>

<p>We’ll start by describing the <em>Borůvka Algorithm</em> to compute the MST. Note that there’s nothing special about it with respect to the Euclidean variant. It’s just that it operates in batches and we can leverage that to search on the KD-trees more efficiently.</p>

<h2 id="borůvka-algorithm">Borůvka Algorithm</h2>

<p>Interestingly enough, the problem that motivated the Borůvka algorithm can be modeled as a Euclidean graph, where vertices are cities and edges between them have costs corresponding to the Euclidean distance. However his algorithm works on general graphs and doesn’t exploit the Euclidean properties.</p>

<p>Like Kruskal and Prim, the Borůvka algorithm is greedy, at each step taking the optimal decision and that leads to the optimal solution. In high level terms:</p>

<p>At start, each vertex belongs to its own component. Then we loop until one component remains:</p>

<ul>
  <li>For each component, select the cheapest edge to another component. Collect all these edges first.</li>
  <li>For each edge:
    <ul>
      <li>If they connect two components, merge them into one, add the edge to the solution.</li>
    </ul>
  </li>
</ul>

<p>This algorithm feels like a fusion between Kruskal (add cheapest edges to the MST) and Prim (grow a component). I guess it’s not as popular as either because the implementation is less simple. The steps are very suggestive of the <a href="https://en.wikipedia.org/wiki/Disjoint-set_data_structure">union-find data structure</a> and indeed it’s used in the implementation.</p>

<p>First, let’s prove the correctness of this algorithm: the idea is that at any point in time, the solution contains a subset of a MST (<em>Lemma 1</em>). This then implies the edges in the solution form a forest (i.e. each component is a tree). Since only one component is left at the end, it must be a tree and hence a MST.</p>

<p><strong>Lemma 1.</strong> At each step of the iteration of the Borůvka algorithm the set of selected edges is a subset of the edges of <em>some</em> spanning tree of minimum cost.</p>

<proof>
We prove by induction. This is trivially true for the base, for an empty set is a subset of any set. Now assume the edges $E$ at the beginning of iteration are a subset of some MST. Consider a component $A$ and the edge $e$ we select to add between $A$ and some other component. If $E \cup \curly{e}$ is in some MST, we're done.
<br /><br />
Otherwise assume no MST contains $E \cup \curly{e}$. Since $A$ must be connected to the rest of the forest at some point, there's an edge $f$ leaving $A$ such that $E \cup \curly{f}$ is in some MST $T$. If we remove $f$, we're left with two components, $A$ and $V \setminus A$. By construction $e$ is also an edge from $A$ to $V \setminus A$, so we can replace $f$ with $e$ on the MST. By construction $w_{e} \le w_{f}$. If $w_e = w_f$ then we have another MST containing $E \cup \curly{e}$, but that's a contradiction. If $w_{e} \lt w_{f}$, then we found a new spanning tree with smaller cost, so $T$ is not a MST.

</proof>

<p>The simplest way to implement this algorithm is to keep a list of all candidate edges. Then at the beginning of the iteration, keep only edges that are across components (using union-find) and then for each component, track the cheapest edge. We can determine whether two vertices are in the same component of a union find in $O(1)$ amortized, and also merge two components in $O(1)$. This makes each iteration $O(\abs{E})$.</p>

<p>At each iteration, each component will be merged into some other component, so the number of components will at least halve. Thus there are only $O(\log \abs{V})$ iterations leading to a $O(\abs{E} \log \abs{V})$ algorithm.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-08-17-euclidean-mst/boruvka-app.png" alt="See caption." />
  <figcaption>Figure 1: Screenshot from the <a href="https://www.kuniga.me/resources/blog/2026-08-17-euclidean-mst/boruvka-demo.html">JavaScript applet</a> to compute a the MST step-by-step using Borůvka and showing the union-find state on the side.</figcaption>
</figure>

<h3 id="implementation">Implementation</h3>

<p>As discussed above, the algorithm uses the union find data structure, which we’ll implement using <code class="language-plaintext highlighter-rouge">UnionFind</code>. The implementation details are collapsed below. We just need to understand the methods: <code class="language-plaintext highlighter-rouge">.find(x) -&gt; int</code> which returns the component of a given member <code class="language-plaintext highlighter-rouge">x</code>, and <code class="language-plaintext highlighter-rouge">.union(x, y)</code> which merges the components of <code class="language-plaintext highlighter-rouge">x</code> and <code class="language-plaintext highlighter-rouge">y</code>.</p>

<details>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">UnionFind</span><span class="p">:</span>
    <span class="k">def</span> <span class="nf">__init__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">n</span><span class="p">):</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">p</span> <span class="o">=</span> <span class="nb">list</span><span class="p">(</span><span class="nb">range</span><span class="p">(</span><span class="n">n</span><span class="p">))</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">s</span> <span class="o">=</span> <span class="p">[</span><span class="mi">1</span><span class="p">]</span><span class="o">*</span><span class="n">n</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">sz</span> <span class="o">=</span> <span class="n">n</span>

    <span class="k">def</span> <span class="nf">find</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">):</span>
        <span class="n">p</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">p</span>
        <span class="k">if</span> <span class="n">p</span><span class="p">[</span><span class="n">x</span><span class="p">]</span> <span class="o">!=</span> <span class="n">x</span><span class="p">:</span>
            <span class="n">p</span><span class="p">[</span><span class="n">x</span><span class="p">]</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">find</span><span class="p">(</span><span class="n">p</span><span class="p">[</span><span class="n">x</span><span class="p">])</span>
        <span class="k">return</span> <span class="n">p</span><span class="p">[</span><span class="n">x</span><span class="p">]</span>

    <span class="k">def</span> <span class="nf">union</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">x</span><span class="p">,</span> <span class="n">y</span><span class="p">):</span>
        <span class="n">px</span><span class="p">,</span> <span class="n">py</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">find</span><span class="p">(</span><span class="n">x</span><span class="p">),</span> <span class="bp">self</span><span class="p">.</span><span class="n">find</span><span class="p">(</span><span class="n">y</span><span class="p">)</span>
        <span class="k">if</span> <span class="n">px</span> <span class="o">==</span> <span class="n">py</span><span class="p">:</span>
            <span class="k">return</span>

        <span class="n">s</span><span class="p">,</span> <span class="n">p</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">s</span><span class="p">,</span> <span class="bp">self</span><span class="p">.</span><span class="n">p</span>
        <span class="k">if</span> <span class="n">s</span><span class="p">[</span><span class="n">px</span><span class="p">]</span> <span class="o">&lt;</span> <span class="n">s</span><span class="p">[</span><span class="n">py</span><span class="p">]:</span>
            <span class="n">px</span><span class="p">,</span> <span class="n">py</span> <span class="o">=</span> <span class="n">py</span><span class="p">,</span> <span class="n">px</span>

        <span class="n">s</span><span class="p">[</span><span class="n">px</span><span class="p">]</span> <span class="o">+=</span> <span class="n">s</span><span class="p">[</span><span class="n">py</span><span class="p">]</span>
        <span class="n">p</span><span class="p">[</span><span class="n">py</span><span class="p">]</span> <span class="o">=</span> <span class="n">p</span><span class="p">[</span><span class="n">px</span><span class="p">]</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">sz</span> <span class="o">-=</span> <span class="mi">1</span>
        <span class="k">return</span> <span class="n">s</span><span class="p">[</span><span class="n">px</span><span class="p">]</span>

    <span class="k">def</span> <span class="nf">size</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">sz</span></code></pre></figure>

</details>

<p>We also define a few utility classes to help with syntax, but their meaning is intuitive, for example <code class="language-plaintext highlighter-rouge">Point</code> and <code class="language-plaintext highlighter-rouge">BoundingBox</code>. A bounding box is the smallest axis-aligned box containing a set of points. We represent it by its “lower” and “upper” corners.</p>

<details>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">norm_sq</span><span class="p">(</span><span class="n">p</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">float</span><span class="p">:</span>
    <span class="k">return</span> <span class="nb">sum</span><span class="p">(</span><span class="n">x</span><span class="o">*</span><span class="n">x</span> <span class="k">for</span> <span class="n">x</span> <span class="ow">in</span> <span class="n">p</span><span class="p">)</span>

<span class="o">@</span><span class="n">dataclass</span><span class="p">(</span><span class="n">frozen</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
<span class="k">class</span> <span class="nc">Point</span><span class="p">:</span>
    <span class="n">data</span><span class="p">:</span> <span class="nb">tuple</span><span class="p">[</span><span class="nb">int</span><span class="p">,</span> <span class="p">...]</span>

    <span class="k">def</span> <span class="nf">__getitem__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">dim</span><span class="p">:</span> <span class="n">Dimension</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">[</span><span class="n">dim</span><span class="p">.</span><span class="n">v</span><span class="p">]</span>

    <span class="k">def</span> <span class="nf">__len__</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
        <span class="k">return</span> <span class="nb">len</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">__abs__</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">float</span><span class="p">:</span>
        <span class="k">return</span> <span class="n">sqrt</span><span class="p">(</span><span class="n">norm_sq</span><span class="p">(</span><span class="bp">self</span><span class="p">))</span>

    <span class="k">def</span> <span class="nf">__sub__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">other</span><span class="p">:</span> <span class="n">Point</span><span class="p">):</span>
        <span class="n">sub</span> <span class="o">=</span> <span class="nb">tuple</span><span class="p">(</span><span class="n">a</span><span class="o">-</span><span class="n">b</span> <span class="k">for</span> <span class="n">a</span><span class="p">,</span><span class="n">b</span> <span class="ow">in</span> <span class="nb">zip</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">,</span> <span class="n">other</span><span class="p">.</span><span class="n">data</span><span class="p">))</span>
        <span class="k">return</span> <span class="n">Point</span><span class="p">(</span><span class="n">sub</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">__iter__</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
          <span class="k">return</span> <span class="nb">iter</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">)</span>

<span class="o">@</span><span class="n">dataclass</span>
<span class="k">class</span> <span class="nc">BoundingBox</span><span class="p">:</span>
    <span class="n">lo</span><span class="p">:</span> <span class="n">Point</span>
    <span class="n">hi</span><span class="p">:</span> <span class="n">Point</span>

    <span class="o">@</span><span class="nb">staticmethod</span>
    <span class="k">def</span> <span class="nf">for_point</span><span class="p">(</span><span class="n">p</span><span class="p">):</span>
        <span class="k">return</span> <span class="n">BoundingBox</span><span class="p">(</span><span class="n">p</span><span class="p">,</span> <span class="n">p</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">union</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">bb</span><span class="p">):</span>
        <span class="k">if</span> <span class="n">bb</span> <span class="ow">is</span> <span class="bp">None</span><span class="p">:</span>
            <span class="k">return</span> <span class="bp">self</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">lo</span> <span class="o">=</span>  <span class="n">Point</span><span class="p">(</span>
            <span class="nb">tuple</span><span class="p">(</span><span class="nb">min</span><span class="p">(</span><span class="n">px</span><span class="p">,</span> <span class="n">qx</span><span class="p">)</span> <span class="k">for</span> <span class="p">(</span><span class="n">px</span><span class="p">,</span> <span class="n">qx</span><span class="p">)</span> <span class="ow">in</span> <span class="nb">zip</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">lo</span><span class="p">,</span> <span class="n">bb</span><span class="p">.</span><span class="n">lo</span><span class="p">))</span>
        <span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">hi</span> <span class="o">=</span>  <span class="n">Point</span><span class="p">(</span>
            <span class="nb">tuple</span><span class="p">(</span><span class="nb">max</span><span class="p">(</span><span class="n">px</span><span class="p">,</span> <span class="n">qx</span><span class="p">)</span> <span class="k">for</span> <span class="p">(</span><span class="n">px</span><span class="p">,</span> <span class="n">qx</span><span class="p">)</span> <span class="ow">in</span> <span class="nb">zip</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">hi</span><span class="p">,</span> <span class="n">bb</span><span class="p">.</span><span class="n">hi</span><span class="p">))</span>
        <span class="p">)</span>

    <span class="k">def</span> <span class="nf">size</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="s">'Square length of the diagonal'</span>
        <span class="k">return</span> <span class="n">norm_sq</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">lo</span> <span class="o">-</span> <span class="bp">self</span><span class="p">.</span><span class="n">hi</span><span class="p">)</span></code></pre></figure>

</details>

<p>We can start defining an interface for any algorithms computing the Euclidean minimum spanning tree from a set of points:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">EMST</span><span class="p">(</span><span class="n">ABC</span><span class="p">):</span>
    <span class="o">@</span><span class="n">abstractmethod</span>
    <span class="k">def</span> <span class="nf">desc</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="s">"Describe the algorithm"</span>

    <span class="o">@</span><span class="n">abstractmethod</span>
    <span class="k">def</span> <span class="nf">get_mst_edges</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">points</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="n">Point</span><span class="p">])</span> <span class="o">-&gt;</span> <span class="nb">list</span><span class="p">[</span><span class="n">Edge</span><span class="p">]:</span>
        <span class="k">pass</span></code></pre></figure>

<p>And then define the specialization for Borůvka:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">Boruvka</span><span class="p">(</span><span class="n">EMST</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">setup</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">points</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="n">Point</span><span class="p">]):</span>
        <span class="k">pass</span>

    <span class="o">@</span><span class="n">abstractmethod</span>
    <span class="k">def</span> <span class="nf">fill_best_edge_by_component</span><span class="p">():</span>
        <span class="k">pass</span>

    <span class="k">def</span> <span class="nf">get_mst_edges</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">points</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="n">Point</span><span class="p">])</span> <span class="o">-&gt;</span> <span class="nb">list</span><span class="p">[</span><span class="n">Edge</span><span class="p">]:</span>
        <span class="n">n</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">points</span><span class="p">)</span>
        <span class="n">uf</span> <span class="o">=</span> <span class="n">UnionFind</span><span class="p">(</span><span class="n">n</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">_uf</span> <span class="o">=</span> <span class="n">uf</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">setup</span><span class="p">(</span><span class="n">points</span><span class="p">)</span>

        <span class="n">sol</span> <span class="o">=</span> <span class="p">[]</span>
        <span class="k">while</span> <span class="n">uf</span><span class="p">.</span><span class="n">size</span><span class="p">()</span> <span class="o">&gt;</span> <span class="mi">1</span><span class="p">:</span>
            <span class="bp">self</span><span class="p">.</span><span class="n">_best_edges</span> <span class="o">=</span> <span class="p">{}</span>
            <span class="bp">self</span><span class="p">.</span><span class="n">fill_best_edge_by_component</span><span class="p">()</span>
            <span class="k">for</span> <span class="n">e</span> <span class="ow">in</span> <span class="bp">self</span><span class="p">.</span><span class="n">_best_edges</span><span class="p">.</span><span class="n">values</span><span class="p">():</span>
                <span class="n">uc</span><span class="p">,</span> <span class="n">vc</span><span class="p">,</span> <span class="n">_</span> <span class="o">=</span> <span class="n">e</span>
                <span class="k">if</span> <span class="bp">self</span><span class="p">.</span><span class="n">merge_components</span><span class="p">(</span><span class="n">uc</span><span class="p">,</span> <span class="n">vc</span><span class="p">):</span>
                    <span class="n">sol</span><span class="p">.</span><span class="n">append</span><span class="p">(</span><span class="n">e</span><span class="p">)</span>
        <span class="k">return</span> <span class="n">sol</span></code></pre></figure>

<p>The core of this algorithm is <code class="language-plaintext highlighter-rouge">fill_best_edge_by_component()</code>, i.e. for each component in the union-find, determine the shortest edge from it to some other component. From there we determine which edges to keep and which components to merge.</p>

<p>We also add some helper functions that are used by different Borůvka implementations, mostly to avoid repeated code when dealing with the union find structure such as <code class="language-plaintext highlighter-rouge">merge_components()</code> and <code class="language-plaintext highlighter-rouge">process_edge()</code> (see if it’s worth adding an edge to the best edge by component).</p>

<details>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">Boruvka</span><span class="p">(</span><span class="n">EMST</span><span class="p">):</span>
    <span class="p">...</span>
    <span class="c1"># Helper methods
</span>
    <span class="k">def</span> <span class="nf">merge_components</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">p</span><span class="p">,</span> <span class="n">q</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">bool</span><span class="p">:</span>
        <span class="s">'Combine components of p and q into one'</span>
        <span class="k">if</span> <span class="bp">self</span><span class="p">.</span><span class="n">_uf</span><span class="p">.</span><span class="n">find</span><span class="p">(</span><span class="n">p</span><span class="p">)</span> <span class="o">==</span> <span class="bp">self</span><span class="p">.</span><span class="n">_uf</span><span class="p">.</span><span class="n">find</span><span class="p">(</span><span class="n">q</span><span class="p">):</span>
            <span class="k">return</span> <span class="bp">False</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">_uf</span><span class="p">.</span><span class="n">union</span><span class="p">(</span><span class="n">p</span><span class="p">,</span> <span class="n">q</span><span class="p">)</span>
        <span class="k">return</span> <span class="bp">True</span>

    <span class="k">def</span> <span class="nf">get_component</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">p</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">_uf</span><span class="p">.</span><span class="n">find</span><span class="p">(</span><span class="n">p</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">get_best_dist</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">p</span><span class="p">):</span>
        <span class="n">pc</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_component</span><span class="p">(</span><span class="n">p</span><span class="p">)</span>
        <span class="k">if</span> <span class="n">pc</span> <span class="ow">not</span> <span class="ow">in</span> <span class="bp">self</span><span class="p">.</span><span class="n">_best_edges</span><span class="p">:</span>
            <span class="k">return</span> <span class="n">inf</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">_best_edges</span><span class="p">[</span><span class="n">pc</span><span class="p">][</span><span class="mi">2</span><span class="p">]</span>

    <span class="k">def</span> <span class="nf">process_edge_for_component</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">c</span><span class="p">,</span> <span class="n">e</span><span class="p">):</span>
        <span class="n">_</span><span class="p">,</span> <span class="n">_</span><span class="p">,</span> <span class="n">w</span> <span class="o">=</span> <span class="n">e</span>
        <span class="k">if</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_best_dist</span><span class="p">(</span><span class="n">c</span><span class="p">)</span> <span class="o">&gt;</span> <span class="n">w</span><span class="p">:</span>
            <span class="bp">self</span><span class="p">.</span><span class="n">_best_edges</span><span class="p">[</span><span class="n">c</span><span class="p">]</span> <span class="o">=</span> <span class="n">e</span>

    <span class="k">def</span> <span class="nf">process_edge</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">e</span><span class="p">):</span>
        <span class="n">u</span><span class="p">,</span> <span class="n">v</span><span class="p">,</span> <span class="n">w</span> <span class="o">=</span> <span class="n">e</span>
        <span class="n">uc</span><span class="p">,</span> <span class="n">vc</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_component</span><span class="p">(</span><span class="n">u</span><span class="p">),</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_component</span><span class="p">(</span><span class="n">v</span><span class="p">)</span>
        <span class="k">if</span> <span class="n">uc</span> <span class="o">==</span> <span class="n">vc</span><span class="p">:</span>
            <span class="k">return</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">process_edge_for_component</span><span class="p">(</span><span class="n">uc</span><span class="p">,</span> <span class="n">e</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">process_edge_for_component</span><span class="p">(</span><span class="n">vc</span><span class="p">,</span> <span class="n">e</span><span class="p">)</span></code></pre></figure>


</details>

<p>Now we are ready for our first implementation of the “naïve” Borůvka, one where we compute the set of edges explicitly. With the helpers we defined, the code is straightforward: to compute the best edge set, we just process each of the $O(N^2)$ edges one at a time:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">NaiveBoruvka</span><span class="p">(</span><span class="n">Boruvka</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">desc</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="k">return</span> <span class="s">"Naive Boruvka"</span>

    <span class="k">def</span> <span class="nf">setup</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">points</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="n">Point</span><span class="p">]):</span>
        <span class="n">n</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">points</span><span class="p">)</span>
        <span class="n">edges</span> <span class="o">=</span> <span class="p">[]</span>
        <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">n</span><span class="p">):</span>
            <span class="k">for</span> <span class="n">j</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">i</span> <span class="o">+</span> <span class="mi">1</span><span class="p">,</span> <span class="n">n</span><span class="p">):</span>
                <span class="n">edges</span><span class="p">.</span><span class="n">append</span><span class="p">((</span><span class="n">i</span><span class="p">,</span> <span class="n">j</span><span class="p">,</span> <span class="n">dist</span><span class="p">(</span><span class="n">points</span><span class="p">[</span><span class="n">i</span><span class="p">],</span> <span class="n">points</span><span class="p">[</span><span class="n">j</span><span class="p">])))</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">_edges</span> <span class="o">=</span> <span class="n">edges</span>


    <span class="k">def</span> <span class="nf">fill_best_edge_by_component</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="k">for</span> <span class="n">e</span> <span class="ow">in</span> <span class="bp">self</span><span class="p">.</span><span class="n">_edges</span><span class="p">:</span>
            <span class="bp">self</span><span class="p">.</span><span class="n">process_edge</span><span class="p">(</span><span class="n">e</span><span class="p">)</span></code></pre></figure>

<h2 id="kd-tree">KD-Tree</h2>

<p>In <a href="https://www.kuniga.me/blog/2026/07/31/kd-tree.html">KD-Tree</a> we learned that this binary structure allows us to search for the nearest point by splitting clusters of points into different subtrees.</p>

<p>It works well in practice, closer to $O(\log N)$ search, even though in the worst case it’s $O(N)$. We can use it to find the closest point $p$ to each point $q$ so that the edges $(p, q)$ are the only ones that need to be accounted for. Conceptually we could implement <code class="language-plaintext highlighter-rouge">fill_best_edge_by_component()</code> as:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">KDTreeBoruvka</span><span class="p">(</span><span class="n">Boruvka</span><span class="p">):</span>
  <span class="p">...</span>
  <span class="k">def</span> <span class="nf">fill_best_edge_by_component</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
      <span class="k">for</span> <span class="n">q</span> <span class="ow">in</span> <span class="n">points</span><span class="p">:</span>
          <span class="n">p</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_closest_point</span><span class="p">(</span><span class="n">kd</span><span class="p">,</span> <span class="n">q</span><span class="p">)</span>
          <span class="bp">self</span><span class="p">.</span><span class="n">process_edge</span><span class="p">((</span><span class="n">q</span><span class="p">,</span> <span class="n">p</span><span class="p">,</span> <span class="n">dist</span><span class="p">(</span><span class="n">p</span><span class="p">,</span> <span class="n">q</span><span class="p">)))</span></code></pre></figure>

<p>Since on average we expect each search to be $O(\log N)$, <code class="language-plaintext highlighter-rouge">fill_best_edge_by_component()</code> is $O(N \log N)$ and the Borůvka becomes $O(N \log^2 N)$.</p>

<p>We can’t use a generic search for kd-tree because now we need to account for the components of the points: Points on the same component are not candidates for closest neighbors. The difference with <code class="language-plaintext highlighter-rouge">query_kd_tree()</code> in the <a href="https://github.com/kunigami/kunigami.github.io/blob/master/blog/code/2026-07-31-kd-tree/kd-tree.py">original implementation</a> is quite small though.</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">KDTreeBoruvka</span><span class="p">(</span><span class="n">KDTreeBoruvkaBased</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">desc</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="k">return</span> <span class="s">"KD-Tree Boruvka"</span>

    <span class="k">def</span> <span class="nf">setup</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">points</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="n">Point</span><span class="p">]):</span>
        <span class="n">n</span> <span class="o">=</span> <span class="nb">len</span><span class="p">(</span><span class="n">points</span><span class="p">)</span>
        <span class="n">view</span> <span class="o">=</span> <span class="n">View</span><span class="p">(</span><span class="n">points</span><span class="p">)</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">_kd</span> <span class="o">=</span> <span class="n">build_kd_tree</span><span class="p">(</span><span class="n">view</span><span class="p">,</span> <span class="n">Dimension</span><span class="p">(</span><span class="n">n</span><span class="o">=</span><span class="mi">3</span><span class="p">))</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">_points</span> <span class="o">=</span> <span class="n">points</span>

    <span class="k">def</span> <span class="nf">query_kd_tree</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">node</span><span class="p">,</span> <span class="n">q</span><span class="p">,</span> <span class="n">dim</span><span class="p">):</span>
        <span class="k">if</span> <span class="ow">not</span> <span class="n">node</span><span class="p">:</span>
            <span class="k">return</span>

        <span class="n">p</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">pivot</span>
        <span class="n">Q</span><span class="p">,</span> <span class="n">P</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_point</span><span class="p">(</span><span class="n">q</span><span class="p">),</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_point</span><span class="p">(</span><span class="n">p</span><span class="p">)</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">process_edge</span><span class="p">((</span><span class="n">q</span><span class="p">,</span> <span class="n">p</span><span class="p">,</span> <span class="n">dist</span><span class="p">(</span><span class="n">Q</span><span class="p">,</span> <span class="n">P</span><span class="p">)))</span>

        <span class="k">if</span> <span class="n">node</span><span class="p">.</span><span class="n">is_leaf</span><span class="p">():</span>
            <span class="k">return</span>

        <span class="k">if</span> <span class="n">Q</span><span class="p">[</span><span class="n">dim</span><span class="p">]</span> <span class="o">&lt;=</span> <span class="n">P</span><span class="p">[</span><span class="n">dim</span><span class="p">]:</span>
            <span class="n">main</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">left</span>
            <span class="n">other</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">right</span>
        <span class="k">else</span><span class="p">:</span>
            <span class="n">main</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">right</span>
            <span class="n">other</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">left</span>

        <span class="bp">self</span><span class="p">.</span><span class="n">query_kd_tree</span><span class="p">(</span><span class="n">main</span><span class="p">,</span> <span class="n">q</span><span class="p">,</span> <span class="n">dim</span><span class="p">.</span><span class="nb">next</span><span class="p">())</span>

        <span class="k">if</span> <span class="n">other</span><span class="p">:</span>
            <span class="n">lb</span> <span class="o">=</span> <span class="nb">abs</span><span class="p">(</span><span class="n">Q</span><span class="p">[</span><span class="n">dim</span><span class="p">]</span> <span class="o">-</span> <span class="n">P</span><span class="p">[</span><span class="n">dim</span><span class="p">])</span>
            <span class="n">ub</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">get_best_dist</span><span class="p">(</span><span class="n">q</span><span class="p">)</span>
            <span class="k">if</span> <span class="n">lb</span> <span class="o">&lt;</span> <span class="n">ub</span><span class="p">:</span>
                <span class="c1"># needs to search in the other tree
</span>                <span class="bp">self</span><span class="p">.</span><span class="n">query_kd_tree</span><span class="p">(</span><span class="n">other</span><span class="p">,</span> <span class="n">q</span><span class="p">,</span> <span class="n">dim</span><span class="p">.</span><span class="nb">next</span><span class="p">())</span>

    <span class="k">def</span> <span class="nf">fill_best_edge_by_component</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="nb">len</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">_points</span><span class="p">)):</span>
            <span class="bp">self</span><span class="p">.</span><span class="n">query_kd_tree</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">_kd</span><span class="p">,</span> <span class="n">i</span><span class="p">,</span> <span class="n">Dimension</span><span class="p">(</span><span class="n">n</span><span class="o">=</span><span class="mi">3</span><span class="p">))</span></code></pre></figure>

<p>Here, when comparing the query point <code class="language-plaintext highlighter-rouge">q</code> with a candidate (<code class="language-plaintext highlighter-rouge">node.pivot</code>), we call <code class="language-plaintext highlighter-rouge">self.process_edge()</code> which should ignore edges from points on the same component. We also work with indices of <code class="language-plaintext highlighter-rouge">points</code> instead of the points directly because we need the indices to do the union find properly. Other than that it’s exactly the same idea.</p>

<h3 id="optimizations">Optimizations</h3>

<p>There are several optimizations we can do such as:</p>

<p>1-) Keep a bounding box for each node, so that instead of calculating the lower bound as the distance to the pivot line:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="n">lb</span> <span class="o">=</span> <span class="nb">abs</span><span class="p">(</span><span class="n">Q</span><span class="p">[</span><span class="n">dim</span><span class="p">]</span> <span class="o">-</span> <span class="n">P</span><span class="p">[</span><span class="n">dim</span><span class="p">])</span></code></pre></figure>

<p>We can do it to the bounding box of that subtree, which is tighter:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="n">lb</span> <span class="o">=</span> <span class="n">point_box_distance</span><span class="p">(</span><span class="n">Q</span><span class="p">,</span> <span class="n">other</span><span class="p">.</span><span class="n">bb</span><span class="p">)</span></code></pre></figure>

<p>2-) Store the set of the component ids in each subtree. If there’s only one and it’s the same as the query point, the entire search can be short-circuited.</p>

<p>This approach requires re-calculation after each iteration because the components change after merge but it’s a $O(N)$ step and the iteration is dominated by $O(N \log N)$ anyway. Then we can add this check in <code class="language-plaintext highlighter-rouge">query_kd_tree()</code>:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">class</span> <span class="nc">KDTreeBoruvka</span><span class="p">(</span><span class="n">KDTreeBoruvkaBased</span><span class="p">):</span>
    <span class="k">def</span> <span class="nf">desc</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">str</span><span class="p">:</span>
        <span class="k">return</span> <span class="s">"KD-Tree Boruvka"</span>

    <span class="k">def</span> <span class="nf">query_kd_tree</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">node</span><span class="p">,</span> <span class="n">q</span><span class="p">,</span> <span class="n">dim</span><span class="p">):</span>
        <span class="k">if</span> <span class="ow">not</span> <span class="n">node</span><span class="p">:</span>
            <span class="k">return</span>

        <span class="c1"># prune: same component
</span>        <span class="k">if</span> <span class="n">node</span><span class="p">.</span><span class="n">components</span> <span class="o">==</span> <span class="p">{</span><span class="bp">self</span><span class="p">.</span><span class="n">get_component</span><span class="p">(</span><span class="n">q</span><span class="p">)}:</span>
            <span class="k">return</span>

        <span class="p">...</span></code></pre></figure>

<p>3-) A larger and more intrusive optimization is to not search the kd-tree for one point at a time, but instead traverse the kd-tree side by side and compute the distance for all points using a single traversal.</p>

<p>The algorithm is a lot more complicated and while my implementation of this version was 2x faster than the basic kd-tree one, it seems to be still a $O(N \log^2 N)$ process.</p>

<p>4-) Codex did a version with even more heuristics and optimizations, reaching a 4x speed up, but it removed a lot of the abstractions and the code became very hard to read, so I don’t think it’s very instructive.</p>

<p>The code for all these variants is on <a href="https://github.com/kunigami/kunigami.github.io/blob/master/blog/code/2026-08-17-euclidean-mst/boruvka.py">Github</a>.</p>

<h2 id="experiments">Experiments</h2>

<p>During my experiments, I also used SciPy’s Minimum Spanning Tree algorithm, mostly to check correctness, but ended up including it in the benchmark as well. Since it’s so easy to translate code between languages, I asked Codex to convert its optimized Python implementation into C++ and Rust.</p>

<p>I ran these algorithms with sets of random points in 3D: $10^3$, $10^4$ and $10^5$ points. The runtimes in seconds are tabulated below:</p>

<table>
  <thead>
    <tr>
      <th>Algorithm</th>
      <th style="text-align: right">$10^3$ points</th>
      <th style="text-align: right">$10^4$ points</th>
      <th style="text-align: right">$10^5$ points</th>
    </tr>
  </thead>
  <tbody>
    <tr>
      <td>Naïve Borůvka</td>
      <td style="text-align: right">1.35</td>
      <td style="text-align: right">182.63</td>
      <td style="text-align: right">-</td>
    </tr>
    <tr>
      <td>SciPy’s MST</td>
      <td style="text-align: right">0.77</td>
      <td style="text-align: right">83.638</td>
      <td style="text-align: right">-</td>
    </tr>
    <tr>
      <td>KD-Tree Boruvka</td>
      <td style="text-align: right">0.32</td>
      <td style="text-align: right">4.22</td>
      <td style="text-align: right">96.1</td>
    </tr>
    <tr>
      <td>KD-Tree Boruvka Dual</td>
      <td style="text-align: right">0.15</td>
      <td style="text-align: right">2.32</td>
      <td style="text-align: right">26.66</td>
    </tr>
    <tr>
      <td>Optimized Python (Codex)</td>
      <td style="text-align: right">0.08</td>
      <td style="text-align: right">1.31</td>
      <td style="text-align: right">36.63</td>
    </tr>
    <tr>
      <td>Naïve Borůvka C++ (Codex)</td>
      <td style="text-align: right">0.005</td>
      <td style="text-align: right">0.47</td>
      <td style="text-align: right">37.61</td>
    </tr>
    <tr>
      <td>Optimized Rust (Codex)</td>
      <td style="text-align: right">0.002</td>
      <td style="text-align: right">0.030</td>
      <td style="text-align: right">0.28</td>
    </tr>
    <tr>
      <td>Optimized C++ (Codex)</td>
      <td style="text-align: right">0.003</td>
      <td style="text-align: right">0.036</td>
      <td style="text-align: right">0.31</td>
    </tr>
  </tbody>
</table>

<p>We can see that C++/Rust are much faster than Python. The naive $O(N^2 \log N)$ C++ implementation is comparable to the optimized $O(N \log^2 N)$ ones even for $10^5$ and beats all the Python implementations for $10^4$.</p>

<h2 id="delaunay-triangulation">Delaunay Triangulation</h2>

<p>For the 2D case, a faster and simpler alternative exists, because it’s possible to show that the edges of a Euclidean MST of a set of points $P$ are a subset of the Delaunay triangulation of $P$.</p>

<p>The Delaunay triangulation of $N$ points in 2D has $O(N)$ edges and can be computed in $O(N \log N)$, so then running a regular $O(\abs{E} \log \abs{E})$ algorithm is very efficient. However for the 3D case, which is the case I was interested in, the number of edges can be $O(N^2)$.</p>

<p>So I studied <a href="https://www.kuniga.me/blog/2026/06/20/delaunay-triangulation.html">Delaunay triangulation</a> because I thought it was the best implementation for EMST but later I learned about the $O(N^2)$ edges.</p>

<h2 id="conclusion">Conclusion</h2>

<p>This concludes a series of posts, which includes <a href="https://www.kuniga.me/blog/2026/06/20/delaunay-triangulation.html">Delaunay triangulation</a>, <a href="https://www.kuniga.me/blog/2026/07/31/kd-tree.html">KD-trees</a> and now the Borůvka algorithm.</p>

<p>It was motivated by a problem in <a href="https://adventofcode.com/2025">Advent of Code</a> which reduced to finding an EMST for 1,000 points in 3D. My Kruskal $O(N^2 \log N)$ ran in a few seconds but I wondered how much better it could be, so I went on this rabbit hole. Little did I know that if I had reimplemented Kruskal in C++, it would be faster than the Borůvka + KD-tree, but it’s never about the destination: I learned a lot during this process.</p>

<h2 id="related-posts">Related Posts</h2>

<p>In <a href="https://www.kuniga.me/blog/2013/11/11/lawler-and-an-introduction-to-matroids.html">An Introduction to Matroids</a> we mentioned that the minimum/maximum spanning tree problem can be modeled as a matroid. Matroids can be solved by greedy polynomial-time algorithms and the Kruskal algorithm is the version that solves the matroid corresponding to MST. The Borůvka algorithm is also greedy.</p>

<p>There’s a generalization of the EMST called the <a href="https://en.wikipedia.org/wiki/Steiner_tree_problem">Steiner Tree Problem</a>, in which you can introduce intermediate nodes to try to reduce the cost of the solution, but solving this problem is NP-Complete.</p>

<p>The Steiner tree sounds a lot like the problem of <a href="https://www.kuniga.me/blog/2019/05/10/constructing-trees-from-a-distance-matrix.html">Constructing Trees from a Distance Matrix</a> which is also known as the <em>tree metric realization</em> problem, in which we can also introduce intermediate nodes, but in this case we’re deciding whether a tree can exist such that the distance between leaves (path length) matches a prescribed distance.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="computational geometry" />
      
        <category term="graph theory" />


        <summary type="html"><![CDATA[Otakar Borůvka was a Czech mathematician who is best known for his work in graph theory. Once, his friend Jindřich Saxel, an employee of the West Moravian Power Company, asked him for help optimizing electric distribution networks. Borůvka modeled the problem as the minimum spanning tree problem and then came up with the first known algorithm to solve it, now known as the Borůvka algorithm. In this post we’ll explore the Borůvka algorithm combined with KD-trees to solve the Euclidean Minimum Spanning Tree problem more efficiently.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">Atomic Posts</title>
      <link href="https://www.kuniga.me/blog/2026/08/15/atomic-posts.html" rel="alternate" type="text/html" title="Atomic Posts" />
      <published>2026-08-15T00:00:00+00:00</published>
      <updated>2026-08-15T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/08/15/atomic-posts</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/08/15/atomic-posts.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/2026-08-15-atomic-posts/ship_containers.jpeg" alt="Ship containers, cartoon style. Generated with nano banana" />
</figure>

<p>I’m using the term <em>atomic post</em> in reference to the concept of <a href="https://www.kuniga.me/books/2025/10/18/atomic-habits.html">atomic habits</a>. The idea is for posts to be as narrow as possible in scope, while still being self-contained.</p>

<!--more-->

<p>Like with atomic habits, the idea is to lower the bar for posting in hopes of posting more often. I mentioned before the desire to write <a href="https://www.kuniga.me/blog/2024/12/02/centralizing-thoughts.html">shower thoughts</a> more often and that:</p>

<blockquote>
  <p>I still need a forcing function to make such posts, because otherwise I keep waiting until I have enough to write about them and it never happens.</p>
</blockquote>

<p>In software development we strive for functions to be <strong>modular</strong>: short but also conceptually self-contained and with the right level of abstraction, so that they can be more easily reused. For posts, the same idea applies, but the ‘reuse’ is so that I can reference the idea in other posts and avoid repeating the same argument over and over.</p>

<p>A new motivation for doing this is that I started using LLMs to find connections between posts and it sometimes surprises me. My expectation is that the more content I have out the higher the chances of interesting connections.</p>

<p>I’ve set up some methodology to help with this. I keep Google docs for several topics I want to write about and whenever I read or think of something related, I add it to that document (this very post had a corresponding doc!). Whenever I find I have enough ideas collected, I will post them.</p>

<p>I’m also trying to be more deliberate on what <a href="https://www.kuniga.me/books/">non-ficcion books</a> I read: I’ll pick topics I already plan to write about instead of random ones that happen to seem interesting to me at the time. The first example of this is <a href="https://www.kuniga.me/books/2026/05/19/elbow-room.html">Elbow Room</a> by Daniel C. Dennett, since I’m interested in sharing my ideas on free will.</p>

<p>Once I have the notes, it should take me, ideally, less than an hour to finish the post. This way I don’t have to find a large block of time to write it. I won’t worry about being comprehensive, because I can always go back and edit the post.</p>

<h2 id="related-posts">Related Posts</h2>

<p>In <a href="https://www.kuniga.me/blog/2022/12/27/on-memory.html">On Memory</a> I described keeping book notes in Google Docs, but I’m gradually shifting to adding the notes under the a topic I’m interested in instead. Only when it’s something I hadn’t thought about or thoughts on the book/writing itself do I keep under the book note.</p>

<p>As early as 2021, in <a href="https://www.kuniga.me/blog/2021/09/01/writing-posts.html">Writing Posts</a> I mention I keep post drafts in Google Docs, but I do that when I already started the process of writing the post, while the new process is at an earlier stage, during ideation.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="meta" />


        <summary type="html"><![CDATA[I’m using the term atomic post in reference to the concept of atomic habits. The idea is for posts to be as narrow as possible in scope, while still being self-contained.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">Folly F14 Map</title>
      <link href="https://www.kuniga.me/blog/2026/08/07/f14.html" rel="alternate" type="text/html" title="Folly F14 Map" />
      <published>2026-08-07T00:00:00+00:00</published>
      <updated>2026-08-07T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/08/07/f14</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/08/07/f14.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/shared/folly-logo.svg" alt="Folly Logo" />
</figure>

<p><code class="language-plaintext highlighter-rouge">F14Map</code> is <a href="https://github.com/facebook/folly">Folly</a>’s alternative to <code class="language-plaintext highlighter-rouge">std::unordered_map</code> and in this post we’ll explore this data structure in detail.</p>

<p>We’ll start with <code class="language-plaintext highlighter-rouge">std::unordered_map</code> which implements a more textbook version of hash maps using linked lists to handle collisions and then cover <code class="language-plaintext highlighter-rouge">F14FastMap</code> which uses a chunked (14 entries / chunk) open addressing implementation and leverages SIMD instructions for efficiency.</p>

<!--more-->

<h2 id="stls-hash-map">STL’s Hash Map</h2>

<p>Recall that <code class="language-plaintext highlighter-rouge">std::unordered_map</code> is a hash map which uses linked lists for dealing with collision. Let’s cover the three main operations that can be performed: insertion, lookup and removal.</p>

<h3 id="insertion">Insertion</h3>

<p>When we insert a key-value pair, we first compute a hash <code class="language-plaintext highlighter-rouge">h</code> for the key to obtain a <code class="language-plaintext highlighter-rouge">size_t</code> (the hash function is configurable). Then we determine which bucket this key falls into by doing <code class="language-plaintext highlighter-rouge">h % bucket_count</code>. If two keys fall into the same bucket, we add to the bucket’s list.</p>

<p>In practice <code class="language-plaintext highlighter-rouge">std::unordered_map</code> uses a single linked list, but each bucket knows where its own list starts, for example:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">sentinel ──&gt; A ──&gt; C ──&gt; B ──&gt; null
   ▲               ▲
   │               │
bucket[0]      bucket[2]     bucket[1] = nullptr</code></pre></figure>

<p>If we were to insert a new node for bucket 2, we can insert it between <code class="language-plaintext highlighter-rouge">A</code> and <code class="language-plaintext highlighter-rouge">C</code> and have <code class="language-plaintext highlighter-rouge">bucket[2]</code> point to this new node. The nodes store the value for the item.</p>

<p><strong>Duplicates.</strong> We can’t just insert the item at the head and call it a day because if the key exists in the hash table we must update it instead of inserting, so we must traverse all the elements in the bucket to make sure if that’s the case. Since this is effectively what <em>Lookup</em> does, we’ll leave the details to that section.</p>

<p>In practice these operations get fused to avoid redoing work, for example determining the right bucket to insert is only done once.</p>

<p><strong>Growing.</strong> As we insert more and more items in the hash table, the list for each bucket will grow and in the worst case degenerate to $O(n)$ insertion / lookup. So when the number of elements crosses a threshold, it increases the number of buckets by ~2x.</p>

<p>There are two “tracks” of thresholds, the default being primes that are roughly 2x apart:</p>

<figure class="highlight"><pre><code class="language-text" data-lang="text">2  5  11  23  47  97  197  397  797  1597  3203  6421  12853  25717</code></pre></figure>

<p>The other is power of 2. Primes are slower to apply <code class="language-plaintext highlighter-rouge">%</code> of (we cannot use bit shifting as with powers of 2), but they tend to hash more uniformly. In any case, every time the number of buckets changes, we need to rehash.</p>

<p>With a new <code class="language-plaintext highlighter-rouge">bucket_count</code>, the nodes will be reshuffled to different buckets so it reconstructs a new linked list from scratch by updating the <code class="language-plaintext highlighter-rouge">next</code> pointer of the nodes. This operation is done in $O(n)$. Note that the nodes themselves are not changed, so if we hold a reference to this node, it will be valid after the growing.</p>

<p>One way to avoid or reduce this overhead is to use <code class="language-plaintext highlighter-rouge">.reserve()</code>, much like we do for <a href="https://www.kuniga.me/blog/2025/01/25/vector-views-in-cpp.html">std::vector</a>.</p>

<h3 id="lookup">Lookup</h3>

<p>For searching a key <code class="language-plaintext highlighter-rouge">q</code>, we need to traverse the whole list of a given bucket. How do we know when we “crossed” into the next bucket list? Each node stores the key hash (before the modular arithmetic), so when searching for an item it checks:</p>

<ul>
  <li>Is the <code class="language-plaintext highlighter-rouge">q</code> hash equal to the node hash? If so, check for equality (<code class="language-plaintext highlighter-rouge">==</code>) on the key. If yes, return the value.</li>
  <li>If not, move forward. However, we also check if we crossed into the next bucket. We do so by doing <code class="language-plaintext highlighter-rouge">% bucket_count</code>: if it doesn’t match the one from <code class="language-plaintext highlighter-rouge">q</code>, it means it’s from a different bucket and we stop the search.</li>
</ul>

<p>Note that we can’t store <code class="language-plaintext highlighter-rouge">h % bucket_count</code> in the node, because as we’ve seen, <code class="language-plaintext highlighter-rouge">bucket_count</code> can change.</p>

<h3 id="removal">Removal</h3>

<p>Removal is straightforward, we search for an element via <em>Lookup</em> and remove the node from the linked list, potentially updating pointers on the <code class="language-plaintext highlighter-rouge">bucket</code> array.</p>

<p>The <code class="language-plaintext highlighter-rouge">bucket_count</code> never shrinks, even if most of the entries are removed.</p>

<h2 id="f14map">F14Map</h2>

<p>There are a few variants of F14Map and <code class="language-plaintext highlighter-rouge">F14FastMap</code> in particular decides which implementation to use at compile time based on the size of the item (key + value) being stored. If smaller than a threshold, it uses <code class="language-plaintext highlighter-rouge">F14ValueMap</code> which stores the items inline. Otherwise it uses <code class="language-plaintext highlighter-rouge">F14VectorMap</code> which externalizes the items to a vector. We’ll cover <code class="language-plaintext highlighter-rouge">F14ValueMap</code> first, then the differences with <code class="language-plaintext highlighter-rouge">F14VectorMap</code>.</p>

<p>F14Map relies on a lot of SIMD instructions which are not standardized between x86 and ARM architectures. For the sake of brevity we’ll use the x86 instructions, more specifically the 128-bit family SSE2.</p>

<p>As we did with <code class="language-plaintext highlighter-rouge">std::unordered_map</code> we’ll cover the 3 main operations – insertion, lookup and removal – at a high level, but then dive into some of the optimizations it uses that cannot be performed with the STL implementation, due to node allocation being done independently and hence fragmented in memory.</p>

<h3 id="insertion-1">Insertion</h3>

<p>The way <code class="language-plaintext highlighter-rouge">F14Map</code> handles collision is very different: first, the number of entries in a given bucket is fixed to 12 or 14 depending on the type of the item. The family of structures <code class="language-plaintext highlighter-rouge">F14*</code> is named after the latter value! I’m assuming 12 came later, probably due to some fine tuning for specific types. In any case, we’ll assume 14 for the remainder of the post for simplicity.</p>

<p>A structure holding the 14 entries is called a <strong>chunk</strong>. To determine which chunk an item should go to, we do <code class="language-plaintext highlighter-rouge">h % chunk_count</code>, much like in <code class="language-plaintext highlighter-rouge">std::unordered_map</code>. Note that <code class="language-plaintext highlighter-rouge">chunk_count</code> is always a power of 2. If that chunk is full, we try another chunk.</p>

<p>Before we explain how we search for the next chunk, we define the <strong>tag</strong>, which is an 8-bit value with the most significant bit set to 1 (we’ll explain the reason later) and the other 7 bits are extracted from the hash <code class="language-plaintext highlighter-rouge">h</code>, but the exact method for extraction varies.</p>

<p>We then calculate the <strong>stride</strong>, which is essentially <code class="language-plaintext highlighter-rouge">2 * tag + 1</code>, which is always an odd number. This is the amount we’ll keep adding to the current index until we find a non-full chunk, wrapping around when it exceeds <code class="language-plaintext highlighter-rouge">chunk_count</code>. Because <code class="language-plaintext highlighter-rouge">stride</code> an odd number and <code class="language-plaintext highlighter-rouge">chunk_count</code> is a power of 2, they’re always co-prime, so we guarantee that by iterating by <code class="language-plaintext highlighter-rouge">stride</code> steps, we’ll cover all chunks before we repeat a chunk.</p>

<details>
This result is not obvious, so we can prove more formally: if $k$ and $M$ are coprimes, i.e. $\gcd(k, M) = 1$, then $ik \pmod M$ are unique for $i \in \curly{0, \dots, M - 1}$.
<br /><br />
Let's prove by contradiction. Assume $i \ne j$ but that $ik \equiv jk \pmod M$ for some $i, j \in \curly{0, \dots, M - 1}$. Then $(ik - jk) = (i - j)k \equiv 0 \pmod M$ and since $k$ is coprime with $M$, $i - j \equiv 0 \pmod M$ or $i \equiv j \pmod M$. Since bot are smaller than $M$, their "remainder" with $M$ equals themselves, which implies $i = j$, a contradiction.
</details>

<p>The fact that <code class="language-plaintext highlighter-rouge">stride</code> is dependent on the tag which has 7 bits of entropy should help make sure different keys have a different distribution of <code class="language-plaintext highlighter-rouge">strides</code>. In other words, the order in which chunks are visited for each item should be uniformly distributed, which should keep the expected number of chunks to visit until we find a valid chunk small.</p>

<p><strong>First Free Position.</strong> It’s not enough to determine that a chunk is not full. We need to determine the position at which to insert the item in a chunk. This is the first optimization that leverages SIMD (Single-Instruction Multiple Data). The chunk structure has this shape:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="k">struct</span> <span class="nc">F14Chunk</span><span class="o">&lt;</span><span class="k">typename</span> <span class="n">Item</span><span class="o">&gt;</span> <span class="p">{</span>
    <span class="n">std</span><span class="o">::</span><span class="n">array</span><span class="o">&lt;</span><span class="kt">uint8_t</span><span class="p">,</span> <span class="mi">14</span><span class="o">&gt;</span> <span class="n">tags_</span><span class="p">;</span>
    <span class="kt">uint8_t</span> <span class="n">control_</span><span class="p">;</span>
    <span class="kt">uint8_t</span> <span class="n">outboundOverflowCount_</span><span class="p">;</span>
    <span class="n">std</span><span class="o">::</span><span class="n">array</span><span class="o">&lt;</span><span class="n">Item</span><span class="p">,</span> <span class="mi">14</span><span class="o">&gt;</span> <span class="n">rawItems_</span><span class="p">;</span>
<span class="p">};</span></code></pre></figure>

<p>The variable <code class="language-plaintext highlighter-rouge">control_</code> clubs 2 pieces of information, but for this post we only care about the highest 4 bits, <code class="language-plaintext highlighter-rouge">hostedOverflowCount_</code>, which counts “how many items currently living in this chunk don’t belong here?”. We increment it whenever we insert an item on a chunk that wasn’t its first choice.</p>

<p>The variable <code class="language-plaintext highlighter-rouge">outboundOverflowCount_</code> counts “how many items wanted this chunk at any point in their search but it was full?”. We increment it whenever we try to insert an item in a chunk that was already full.</p>

<p>Note that these 2 variables pad the 14 bytes of <code class="language-plaintext highlighter-rouge">tags_</code> into a 16-byte value which is the “unit” for the SIMD instructions it uses.</p>

<p>The data is stored in <code class="language-plaintext highlighter-rouge">rawItems_</code>. Each item in <code class="language-plaintext highlighter-rouge">tags_</code> corresponds to an item in <code class="language-plaintext highlighter-rouge">rawItems_</code> and it stores the <code class="language-plaintext highlighter-rouge">tag</code> we just discussed. If the position <code class="language-plaintext highlighter-rouge">i</code> is free, then <code class="language-plaintext highlighter-rouge">tags_[i] = 0</code>. Recall that tags have the most significant bit (MSB) set to 1. So if we want to find the first free position, we just need to find the first position that has MSB 0. This is done by this code:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="kt">uint16_t</span> <span class="n">occupied</span> <span class="o">=</span> <span class="n">_mm_movemask_epi8</span><span class="p">(</span><span class="n">_mm_load_si128</span><span class="p">(</span><span class="o">&amp;</span><span class="n">tags_</span><span class="p">[</span><span class="mi">0</span><span class="p">]))</span> <span class="o">&amp;</span> <span class="mh">0x3FFF</span><span class="p">;</span>
<span class="kt">uint16_t</span> <span class="n">empty</span> <span class="o">=</span> <span class="n">occupied</span> <span class="o">^</span> <span class="mh">0x3FFF</span><span class="p">;</span>
<span class="k">if</span> <span class="p">(</span><span class="n">empty</span> <span class="o">==</span> <span class="mi">0</span><span class="p">)</span> <span class="p">{</span> <span class="cm">/* chunk is full */</span> <span class="p">}</span>
<span class="kt">unsigned</span> <span class="n">slot</span> <span class="o">=</span> <span class="n">__builtin_ctz</span><span class="p">(</span><span class="n">empty</span><span class="p">);</span></code></pre></figure>

<p>The function <code class="language-plaintext highlighter-rouge">_mm_load_si128()</code> loads 16 bytes into a 128-bit SIMD register. Since we’re passing the address of <code class="language-plaintext highlighter-rouge">tags_[0]</code> it will load the 14 bytes of <code class="language-plaintext highlighter-rouge">tags_</code> and the 2-byte counters.</p>

<p>The function <code class="language-plaintext highlighter-rouge">_mm_movemask_epi8()</code> takes the MSB of each of the 16 bytes and packs that into a 16-bit integer. The mask <code class="language-plaintext highlighter-rouge">&amp; 0x3FFF</code> clears the bits from <code class="language-plaintext highlighter-rouge">control_</code> and <code class="language-plaintext highlighter-rouge">outboundOverflowCount_</code> because we don’t care about them. Then <code class="language-plaintext highlighter-rouge">^ 0x3FFF</code> flips the bits on the 14 LSB. So if all positions were occupied, we would have <code class="language-plaintext highlighter-rouge">occupied = 0x3FFF</code> and then <code class="language-plaintext highlighter-rouge">empty = 0</code>.</p>

<p>Finally <code class="language-plaintext highlighter-rouge">__builtin_ctz()</code> counts trailing zeros, so it returns the first bit of <code class="language-plaintext highlighter-rouge">empty</code> that is set, which was the bit in <code class="language-plaintext highlighter-rouge">occupied</code> that was 0 and thus the index of the first position that is free!</p>

<p><strong>Growing.</strong> As in the <code class="language-plaintext highlighter-rouge">std::unordered_map</code>, once enough entries are inserted the structure must grow. Differently from the STL version though, the chunks and the entries they hold are not stable. They need to be moved to a different location of contiguous memory because the <code class="language-plaintext highlighter-rouge">F14Chunk</code> is stored as a contiguous array.</p>

<p>It always allocates a new array though because it can’t update the chunks in place. Note that this increases the memory temporarily, while both structures are live. Then it iterates over the existing chunks and items inside each to reinsert (<code class="language-plaintext highlighter-rouge">std::move</code>) them into the new chunks using the same strategy except that now <code class="language-plaintext highlighter-rouge">chunk_count</code> is twice the previous value.</p>

<p>This implies that the address of the items in the hash map changes during this process, so references are not stable, which is a semantic difference with <code class="language-plaintext highlighter-rouge">std::unordered_map</code>.</p>

<p>One optimization that can be used is that during this process <code class="language-plaintext highlighter-rouge">tags_</code> is compact: there are no holes because there’s no removal until we finish the rehashing, so <em>First Free Position</em> can be found by keeping a counter of item count for the chunk.</p>

<p>Another optimization that can be done because we use <code class="language-plaintext highlighter-rouge">tags_</code> as the check for the presence of an element, is that when we <code class="language-plaintext highlighter-rouge">malloc</code> a new array of <code class="language-plaintext highlighter-rouge">F14Chunk</code> we don’t need to <code class="language-plaintext highlighter-rouge">memset()</code> the array <code class="language-plaintext highlighter-rouge">rawItems_</code>, we can leave garbage there. We just need to clear the first 16 bytes:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">std</span><span class="o">::</span><span class="n">memset</span><span class="p">(</span><span class="o">&amp;</span><span class="n">tags_</span><span class="p">[</span><span class="mi">0</span><span class="p">],</span> <span class="sc">'\0'</span><span class="p">,</span> <span class="mi">16</span><span class="p">);</span></code></pre></figure>

<p>which can be done with a single SIMD instruction.</p>

<h3 id="lookup-1">Lookup</h3>

<p>For lookup, first we compute the <code class="language-plaintext highlighter-rouge">tag</code> for the key and load into the SIMD register via <code class="language-plaintext highlighter-rouge">_mm_set1_epi8(tag)</code>. This replicates the same byte 16 times into a register, for parallel comparison.</p>

<p>Then, for each chunk it visits, we load the tags into a register (like we do during insertion) then compare with the key’s <code class="language-plaintext highlighter-rouge">tag</code> using a single SIMD instruction and then find the position where the bit is set. The code is roughly:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="c1">// once per search</span>
<span class="n">__m128i</span> <span class="n">needleV</span> <span class="o">=</span> <span class="n">_mm_set1_epi8</span><span class="p">(</span><span class="n">tag</span><span class="p">);</span>

<span class="c1">// for each chunk</span>
<span class="k">auto</span> <span class="n">tagV</span> <span class="o">=</span> <span class="n">_mm_load_si128</span><span class="p">(</span><span class="o">&amp;</span><span class="n">tags_</span><span class="p">[</span><span class="mi">0</span><span class="p">]);</span>
<span class="k">auto</span> <span class="n">eqV</span>  <span class="o">=</span> <span class="n">_mm_cmpeq_epi8</span><span class="p">(</span><span class="n">tagV</span><span class="p">,</span> <span class="n">needleV</span><span class="p">);</span>
<span class="k">auto</span> <span class="n">mask</span> <span class="o">=</span> <span class="n">_mm_movemask_epi8</span><span class="p">(</span><span class="n">eqV</span><span class="p">)</span> <span class="o">&amp;</span> <span class="mh">0x3FFF</span><span class="p">;</span>
<span class="k">if</span> <span class="p">(</span><span class="o">!</span><span class="n">mask</span><span class="p">)</span> <span class="p">{</span>
    <span class="c1">// tag not in chunk</span>
<span class="p">}</span>
<span class="kt">unsigned</span> <span class="n">slot</span> <span class="o">=</span> <span class="n">__builtin_ctz</span><span class="p">(</span><span class="n">mask</span><span class="p">);</span></code></pre></figure>

<p>The function <code class="language-plaintext highlighter-rouge">_mm_cmpeq_epi8</code> returns a 16-byte register. A byte is set to <code class="language-plaintext highlighter-rouge">0xFF</code> if the corresponding bytes of the input are equal or <code class="language-plaintext highlighter-rouge">0x00</code> otherwise. Recall that <code class="language-plaintext highlighter-rouge">_mm_movemask_epi8()</code> takes the MSB of each of the 16 bytes and packs that into a 16-bit integer. Again we need <code class="language-plaintext highlighter-rouge">0x3FFF</code> to exclude the bits from <code class="language-plaintext highlighter-rouge">control_</code> and <code class="language-plaintext highlighter-rouge">outboundOverflowCount_</code>.</p>

<p>This acts as an early filter (think of a simplified <a href="https://www.kuniga.me/blog/2015/01/29/bloom-filters.html">bloom filter</a>), but we still need to check if the key corresponding to that tag matches the searched one, so we’d check <code class="language-plaintext highlighter-rouge">rawItems_[slot]</code>. Note that <code class="language-plaintext highlighter-rouge">mask</code> might have multiple bits set if different keys map to the same <code class="language-plaintext highlighter-rouge">tag</code> and are on the same chunk, so we need to iterate.</p>

<p>The <code class="language-plaintext highlighter-rouge">outboundOverflowCount_</code> can be used to stop searching early: if it’s 0, then it means no entry tried to insert on this chunk and could not, including the item we’re looking for, so if we don’t find the key here, there’s no point in continuing the search. Without this check we’d always have to scan all $O(n)$ chunks to be sure a key doesn’t exist anywhere.</p>

<h3 id="removal-1">Removal</h3>

<p>The first part of the removal consists of finding the location of the element and this is exactly like <em>Lookup</em>. The second part consists of the cleanup. First we clear the corresponding byte in <code class="language-plaintext highlighter-rouge">tags_</code> and destroy the value in <code class="language-plaintext highlighter-rouge">rawItems_</code>.</p>

<p>Then we need to update <code class="language-plaintext highlighter-rouge">outboundOverflowCount_</code>. We do this by replaying the insertion of the key being removed. It will start at the initial chunk (which depends only on the hash of the key) and then we’ll move by <code class="language-plaintext highlighter-rouge">stride</code>s until we reach the chunk we’re at. On every chunk we visit we subtract from <code class="language-plaintext highlighter-rouge">outboundOverflowCount_</code>. The chunks we visit during removal are the same we did during insertion, no matter if other items were inserted or removed in between!</p>

<p><strong>Removal by Iterator.</strong> The flow described above is when we have the key and want to remove it. This involves a lookup to find the position before erasing.</p>

<p>Another case is when we already have the iterator, in which case we can go straight to the removal. This is useful to apply a “filter” over the hash table, for example:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="k">for</span> <span class="p">(</span><span class="k">auto</span> <span class="n">it</span> <span class="o">=</span> <span class="n">m</span><span class="p">.</span><span class="n">begin</span><span class="p">();</span> <span class="n">it</span> <span class="o">!=</span> <span class="n">m</span><span class="p">.</span><span class="n">end</span><span class="p">();</span> <span class="p">)</span> <span class="p">{</span>
    <span class="k">if</span> <span class="p">(</span><span class="n">pred</span><span class="p">(</span><span class="o">*</span><span class="n">it</span><span class="p">))</span> <span class="n">it</span> <span class="o">=</span> <span class="n">m</span><span class="p">.</span><span class="n">erase</span><span class="p">(</span><span class="n">it</span><span class="p">);</span>
    <span class="k">else</span> <span class="o">++</span><span class="n">it</span><span class="p">;</span>
<span class="p">}</span></code></pre></figure>

<p>Here <code class="language-plaintext highlighter-rouge">.erase(it)</code> returns an iterator to the next item. When we have the iterator we know the chunk and index to remove but we don’t have the hash nor the tag. To perform the loop to update <code class="language-plaintext highlighter-rouge">outboundOverflowCount_</code> we’d need to compute the hash from the key we’re at.</p>

<p>This is where the variable <code class="language-plaintext highlighter-rouge">hostedOverflowCount_</code> can help us if it’s 0. Recall it counts: “how many items currently living in this chunk don’t belong here?”. If it’s 0, it means this is the first chunk and we don’t need to look further and we’d not need to compute the hash!</p>

<p>Otherwise, we need to decrement <code class="language-plaintext highlighter-rouge">hostedOverflowCount_</code> after removing the element.</p>

<h3 id="f14vectormap">F14VectorMap</h3>

<p>We use <code class="language-plaintext highlighter-rouge">F14ValueMap</code> whenever <code class="language-plaintext highlighter-rouge">sizeof(std::pair&lt;Key, Value&gt;) &lt; 24</code>. Otherwise we do <code class="language-plaintext highlighter-rouge">F14VectorMap</code>. The main difference is that the item is not stored in the chunk’s <code class="language-plaintext highlighter-rouge">rawItems_</code>, but instead stored in an array, roughly:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="n">std</span><span class="o">::</span><span class="n">pair</span><span class="o">&lt;</span><span class="k">const</span> <span class="n">Key</span><span class="p">,</span> <span class="n">Value</span><span class="o">&gt;*</span> <span class="n">values_</span><span class="p">{</span><span class="nb">nullptr</span><span class="p">};</span></code></pre></figure>

<p>which is <code class="language-plaintext highlighter-rouge">malloc()</code>‘ed to have <code class="language-plaintext highlighter-rouge">chunk_count</code> entries, then <code class="language-plaintext highlighter-rouge">rawItems_</code> only stores indices/offsets to <code class="language-plaintext highlighter-rouge">values_</code>.</p>

<p><strong>Insertion.</strong> This is very similar to before, except that we now store the value in <code class="language-plaintext highlighter-rouge">values_[size]</code>, store <code class="language-plaintext highlighter-rouge">size</code> in <code class="language-plaintext highlighter-rouge">rawItems_</code> and then increment <code class="language-plaintext highlighter-rouge">size</code>. When we need to grow, we <code class="language-plaintext highlighter-rouge">malloc()</code> a new array of size <code class="language-plaintext highlighter-rouge">chunk_count * 2</code>, and move the old values there.</p>

<p><strong>Removal.</strong> The <code class="language-plaintext highlighter-rouge">values_</code> array is dense, meaning that the first <code class="language-plaintext highlighter-rouge">size</code> positions are always occupied and the remaining contain garbage. This invariant can be maintained when removing position <code class="language-plaintext highlighter-rouge">i</code> by moving the last element to there and decrementing <code class="language-plaintext highlighter-rouge">size</code> by one. Then the <code class="language-plaintext highlighter-rouge">rawItems_</code> corresponding to the swapped item must be updated to point to <code class="language-plaintext highlighter-rouge">i</code>. The way it’s done is by taking the key from that item to find the chunk + index using the same process as the insertion/lookup.</p>

<h2 id="comparison">Comparison</h2>

<p>The major difference between <code class="language-plaintext highlighter-rouge">std::unordered_map</code> and <code class="language-plaintext highlighter-rouge">F14FastMap</code> is that the former allocates a node for each entry, whereas for F14 it stores them in contiguous chunks of memory (both for the <code class="language-plaintext highlighter-rouge">F14Chunk</code> and <code class="language-plaintext highlighter-rouge">values_</code> array). The STL version performs one <code class="language-plaintext highlighter-rouge">malloc()</code> per entry while the F14 only does <code class="language-plaintext highlighter-rouge">malloc()</code> when growing.</p>

<p>The tag system from F14 allows leveraging SIMD instructions and because the chunk is aligned at 16 bytes:</p>

<figure class="highlight"><pre><code class="language-c--" data-lang="c++"><span class="k">template</span> <span class="o">&lt;</span><span class="k">typename</span> <span class="nc">ItemType</span><span class="p">&gt;</span>
<span class="k">struct</span> <span class="nc">alignas</span><span class="p">(</span><span class="mi">16</span><span class="p">)</span> <span class="n">F14Chunk</span> <span class="p">{</span>
    <span class="n">std</span><span class="o">::</span><span class="n">array</span><span class="o">&lt;</span><span class="kt">uint8_t</span><span class="p">,</span> <span class="mi">14</span><span class="o">&gt;</span> <span class="n">tags_</span><span class="p">;</span>
    <span class="p">...</span>
<span class="p">};</span></code></pre></figure>

<p>The <code class="language-plaintext highlighter-rouge">tags_</code> fit in the <a href="https://www.kuniga.me/blog/2020/04/24/cpu-cache.html">cache line</a>.</p>

<h2 id="conclusion">Conclusion</h2>

<p>In this post we learned how <code class="language-plaintext highlighter-rouge">std::unordered_map</code> and <code class="language-plaintext highlighter-rouge">folly::F14FastMap</code> work behind the scenes! I’m sure I got a bunch of details wrong but I have a cohesive understanding of the overall implementation. I’ve been curious about the 14 since I started working with <code class="language-plaintext highlighter-rouge">folly::F14FastMap</code> and it now all makes sense!</p>

<p>It was a delight to study <code class="language-plaintext highlighter-rouge">folly::F14FastMap</code>: both the data structure and the low-level optimizations are very clever!</p>

<h2 id="related-posts">Related Posts</h2>

<p>We mentioned the post <a href="https://www.kuniga.me/blog/2020/04/24/cpu-cache.html">CPU Cache</a> for cache lines, but also that post describes the implementation of a cache line as a hash table!</p>

<p>In <a href="https://www.kuniga.me/blog/2026/06/01/velox-vectors.html">Velox: The Vector</a> we discussed the dictionary-encoding in which we only store indices to the actual underlying data, similar to <code class="language-plaintext highlighter-rouge">F14VectorMap</code>. In <a href="https://www.kuniga.me/blog/2026/08/04/velox-memory.html">Velox: Memory</a> we mentioned that memory is never given back to the OS, which is the same behavior for <code class="language-plaintext highlighter-rouge">F14VectorMap</code>, it never shrinks the number of buckets. It makes sense statistically to not shrink given that it’s expensive and that, without more information, we can assume we’ll need the peak memory in the future.</p>

<p>The post <a href="https://www.kuniga.me/blog/2018/04/01/hyperloglog-in-rust.html">HyperLogLog in Rust</a> also uses a hash function to determine the bucket and a function <code class="language-plaintext highlighter-rouge">first_non_zero_bit_position</code> which is equivalent to <code class="language-plaintext highlighter-rouge">__builtin_ctz()</code>.</p>

<h2 id="references">References</h2>

<ul>
  <li>[1] Claude Code</li>
  <li>[<a href="https://github.com/facebook/folly">2</a>] Github - facebook/folly</li>
</ul>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="c++" />
      
        <category term="data structures" />


        <summary type="html"><![CDATA[F14Map is Folly’s alternative to std::unordered_map and in this post we’ll explore this data structure in detail. We’ll start with std::unordered_map which implements a more textbook version of hash maps using linked lists to handle collisions and then cover F14FastMap which uses a chunked (14 entries / chunk) open addressing implementation and leverages SIMD instructions for efficiency.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">Velox: Memory</title>
      <link href="https://www.kuniga.me/blog/2026/08/04/velox-memory.html" rel="alternate" type="text/html" title="Velox: Memory" />
      <published>2026-08-04T00:00:00+00:00</published>
      <updated>2026-08-04T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/08/04/velox-memory</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/08/04/velox-memory.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/shared/velox-logo.svg" alt="Velox Logo" />
</figure>

<p><a href="https://github.com/facebookincubator/velox">Velox</a> is an open source C++ library by Meta that can be used to perform computation common to distributed engines like Presto.</p>

<p>Its offerings include columnar operations, a rich type system, an expression parser and a smart resource management such as memory [1]. In this series of posts we’ll go over different components of Velox.</p>

<p>In this post we’ll study memory management done by Velox.</p>

<!--more-->

<p>Previous posts on the series:</p>

<ul>
  <li><a href="https://www.kuniga.me/blog/2026/06/01/velox-vectors.html">Vectors</a></li>
  <li><a href="https://www.kuniga.me/blog/2026/06/18/velox-application.html">A Simple Application</a></li>
  <li><a href="https://www.kuniga.me/blog/2026/07/23/velox-udfs.html">UDFs</a></li>
</ul>

<p>Velox has a custom memory allocator system because the same process can run short-lived queries from different clients. To avoid one query causing others to OOM, it cannot rely on OS-level limits such as cgroups and thus uses its own arbitrage.</p>

<h2 id="components">Components</h2>

<p>There are 4 main components involved in memory allocation: the manager, the allocator, the arbitrator and the pools. The pools themselves are subdivided into root pool, “inner” pool and leaf pool.</p>

<p>The memory allocator (<code class="language-plaintext highlighter-rouge">MemoryAllocator</code>) is the one interfacing with the OS and making the actual allocation.</p>

<p>The memory arbitrator (<code class="language-plaintext highlighter-rouge">MemoryArbitrator</code>) is an interface, and is implemented by classes like <code class="language-plaintext highlighter-rouge">SharedArbitrator</code>. Its purpose is to distribute quotas to the pools, but it doesn’t perform the memory allocation.</p>

<p>Memory pools (<code class="language-plaintext highlighter-rouge">MemoryPool</code>) are organized in a tree hierarchy: at the top there is the root pool, in between there are the inner pools and at the leaves the leaf pools. The root and inner pools are of aggregate type, meaning they are logical grouping of the leaf pools and they’re mostly used to keep aggregated statistics such as total memory used by the subtree. The leaf pool is the one Velox internals interface with.</p>

<p>The idea is that each query corresponds to a root pool. A given process can be executing a number of queries. Each query runs one or more tasks, each having a pool as a child of the query root pool. Then for each node in the plan (see <a href="https://www.kuniga.me/blog/2026/06/18/velox-application.html">Velox Application</a>) we have another pool. Each node might be converted into one or more operators and one instance of each operator will exist for each driver (in the parallel mode). Finally, each such instance of the operator has the leaf pool.</p>

<p>The memory manager (<code class="language-plaintext highlighter-rouge">MemoryManager</code>) is the singleton which can be used to construct the allocator and pools.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-08-04-velox-memory/class-diagram.png" alt="See caption" />
  <figcaption>Figure 1. Relationship between the different components involved in memory allocation.</figcaption>
</figure>

<h2 id="allocation">Allocation</h2>

<p>Allocation typically happens at the leaf pool and it might bubble up all the way to the memory arbitrator. Let’s go through the flow.</p>

<p>Each leaf pool tracks how much memory it’s using (we’ll name it <code class="language-plaintext highlighter-rouge">used</code>) and how much it has allocated to it (we’ll name it <code class="language-plaintext highlighter-rouge">reserved</code>), and both start at 0. When the caller requests <code class="language-plaintext highlighter-rouge">requested</code> amount of memory from the leaf pool, it will check if <code class="language-plaintext highlighter-rouge">used + requested &lt;= reserved</code>. If yes, then it just updates <code class="language-plaintext highlighter-rouge">used += requested</code>.</p>

<p>If <code class="language-plaintext highlighter-rouge">used + requested &gt; reserved</code>, it will ask the root pool to increase its reservation. The request goes through its parents because then they can update the aggregated reserved values. Once it reaches the root, it will check if it’s within its limit.</p>

<p>The root pool has two relevant properties: <code class="language-plaintext highlighter-rouge">capacity</code> and <code class="language-plaintext highlighter-rouge">maxCapacity</code>. The <code class="language-plaintext highlighter-rouge">capacity</code> is analogous to the leaf pool’s <code class="language-plaintext highlighter-rouge">reserved</code>: if the root pool exceeds this limit, it requests the arbitrator to increase its <code class="language-plaintext highlighter-rouge">capacity</code>. The <code class="language-plaintext highlighter-rouge">maxCapacity</code> is a limit on <code class="language-plaintext highlighter-rouge">capacity</code>. It’s a static amount that is set when creating the root pool (unbounded by default). If the increase in <code class="language-plaintext highlighter-rouge">capacity</code> would exceed this value, the pool will try reclaiming memory (see <em>Reclamation</em>).</p>

<p>The arbitrator also contains a limit, <code class="language-plaintext highlighter-rouge">capacity</code>, which is set by the application. If a request for more memory would exceed this value, it will attempt memory reclamation (see <em>Reclamation</em>). Note that the arbitrator limit is global.</p>

<p>So far, all this escalation from leaf pool → root pool → arbitrator is accounting. It checks if the allocation can be performed, but the actual allocation happens via the memory allocator and is initiated by the leaf pool.</p>

<p>The memory allocator also has a limit, also set by the application. If this limit is exceeded, it will result in the error <code class="language-plaintext highlighter-rouge">VELOX_MEM_ALLOC_ERROR</code>. Note that memory allocation can be requested by callers directly to the allocator, without using pools.</p>

<p>The arbitrator capacity must be less than that of the allocator. It’s not exactly the same because of the last point: not all memory allocated is accounted for by the arbitrator, only the ones requested from the pools.</p>

<h3 id="custom-allocator-vs-malloc">Custom Allocator vs. Malloc</h3>

<p>The allocator has 2 flavors: malloc or mmap, which uses <code class="language-plaintext highlighter-rouge">malloc()</code> and <code class="language-plaintext highlighter-rouge">mmap()</code> to allocate memory, respectively. Malloc is the default mode.</p>

<p>Recall that <code class="language-plaintext highlighter-rouge">malloc()</code> can itself be customized by linking a library such as <a href="https://www.kuniga.me/blog/2025/07/15/jemalloc.html">jemalloc</a> during compilation. As we’ve seen libraries like jemalloc do a lot of the heavy lifting on memory allocation, balancing performance and efficiency (reduce fragmentation) and making use of modern hardware and OS (e.g. memory layout and multi-thread). So for this flavor, the Velox memory allocator mostly delegates to <code class="language-plaintext highlighter-rouge">malloc()</code>.</p>

<p>For the <code class="language-plaintext highlighter-rouge">mmap()</code> version, since it requests larger pages to the OS, Velox has to add its custom logic to do the fine grained allocation and we won’t cover it here.</p>

<p>One of the major downsides of this allocator compared to jemalloc is when there are a lot of threads, contention can be significant. As we’ve seen, jemalloc avoids this by using arenas (see <em>Multi-threads and Arenas</em> in <a href="https://www.kuniga.me/blog/2025/07/15/jemalloc.html">jemalloc</a>).</p>

<h2 id="deallocation">Deallocation</h2>

<p>Freeing memory is almost the exact opposite of allocation. When called on a leaf pool, it reduces <code class="language-plaintext highlighter-rouge">used</code>. If the amount of free memory (<code class="language-plaintext highlighter-rouge">reserved - used</code>) crosses a threshold (the quantized sizes), then <code class="language-plaintext highlighter-rouge">reserved</code> is reduced and this amount flows back to the root pool.</p>

<h2 id="reclamation">Reclamation</h2>

<p>As we discussed, there are 2 cases in which memory reclamation can happen:</p>

<p>First is when the <code class="language-plaintext highlighter-rouge">maxCapacity</code> of a root pool would be exceeded, in which case it will choose a leaf pool from which it can reclaim memory. First it checks if the pool can reduce its <code class="language-plaintext highlighter-rouge">reserved</code> and give it back to the root. If not, it tries to find a leaf pool in its subtree to spill its state to disk. Once an operator spills to disk its <code class="language-plaintext highlighter-rouge">used</code> memory drops and it follows the <em>Deallocation</em> process. Only certain operators can do spilling (e.g. <code class="language-plaintext highlighter-rouge">HashBuild</code>, <code class="language-plaintext highlighter-rouge">OrderBy</code>, etc.).</p>

<p>The second case is when the <code class="language-plaintext highlighter-rouge">capacity</code> on the arbitrator is reached. It will choose a root pool from whom to reclaim memory and then the process is the same as above.</p>

<p>If reclamation cannot be done, a query gets killed. In the first case it’s the query making the request; in the second the arbitrator will select the query to be killed. After reclamation is done, the arbitrator can re-allocate the recouped memory to fulfill the original request.</p>

<h2 id="other">Other</h2>

<h3 id="cache">Cache</h3>

<p>Velox supports cache by building on top of the memory framework. The component is called <code class="language-plaintext highlighter-rouge">AsyncDataCache</code> and it allocates from the <code class="language-plaintext highlighter-rouge">MemoryAllocator</code> directly (not through pools).</p>

<p>This cache has a secondary (optional) layer backed by SSD. When enough bytes have been stored in memory, it eventually flushes to SSD. Data is kept in memory as well, but when memory reclamation arrives those can be easily dropped.</p>

<p>Eviction happens when no more data can be stored in RAM, which is the same trigger we’ve seen for the memory allocation.</p>

<h2 id="conclusion">Conclusion</h2>

<p>In this post we’ve learned about the memory management done by Velox. It was one of the most mysterious parts of it, and I think I have a much better grasp on it. It’s not as complex as I imagined, but it’s a lot more complicated than I though with lots of components.</p>

<p>Writing also provided some insights on the motivation, for example, being designed to run multiple independent queries in the same process, which seems to be modeled after the Presto query engine (which is the system it aimed to replace).</p>

<p>It also clarified my understanding of memory pools and the two underlying allocator systems, malloc and custom.</p>

<h2 id="related-posts">Related Posts</h2>

<p>We already discussed <a href="https://www.kuniga.me/blog/2025/07/15/jemalloc.html">jemalloc</a> which itself is a user-space, custom memory allocator that internally implements <a href="https://www.kuniga.me/blog/2020/07/31/buddy-memory-allocation.html">Buddy Memory Allocation</a>.</p>

<p>The summary <a href="https://www.kuniga.me/blog/2025/10/10/review-systems-performance.html">[Book] Systems Performance</a> mentions that allocators don’t return memory to the kernel once free is called, but keep them around. Another relevant behavior is that the virtual to physical mapping for memory is done lazily by the OS: it only happens when memory is written to. In a sense allocation and reclamation in Velox are also lazy.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="distributed systems" />
      
        <category term="databases" />


        <summary type="html"><![CDATA[Velox is an open source C++ library by Meta that can be used to perform computation common to distributed engines like Presto. Its offerings include columnar operations, a rich type system, an expression parser and a smart resource management such as memory [1]. In this series of posts we’ll go over different components of Velox. In this post we’ll study memory management done by Velox.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">On Doing Things Manually</title>
      <link href="https://www.kuniga.me/blog/2026/08/01/on-doing-things-manually.html" rel="alternate" type="text/html" title="On Doing Things Manually" />
      <published>2026-08-01T00:00:00+00:00</published>
      <updated>2026-08-01T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/08/01/on-doing-things-manually</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/08/01/on-doing-things-manually.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/2026-08-01-on-doing-things-manually/human-coder.png" alt="Human writing code via a computer. Generated with Nano Banana. I don't mind using AI to generate thumbnails for me." />
</figure>

<p>In my last post about <a href="https://www.kuniga.me/blog/2026/07/31/kd-tree.html">KD-tree</a>, I vibe-coded a <a href="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/build.html">JavaScript application</a> to demonstrate visually, step-by-step, how to construct and query a KD-tree. Codex one-shotted it in a few minutes; I spent a few minutes linking it to the blog post but did not even take a look at the code.</p>

<p>I’ve been using AI more and more both at work and for personal stuff but I also deliberately avoid using AI for specific tasks. I wanted to spend some time reflecting on this and document it.</p>

<!--more-->

<h2 id="writing">Writing</h2>

<h3 id="for-work">For Work</h3>

<p>Since the beginning of the year, I write effectively <a href="https://www.kuniga.me/blog/2026/02/14/on-ai.html">0% of my code by hand</a> at work. I don’t consider it vibe-coding because I spend a large amount of time <em>reading</em> the code and making sure I understand what it does. I do skim over details and most of the generated unit tests.</p>

<p>AI sometimes writes lengthy comments with too much context which make it cumbersome to understand. If it’s too much I manually erase chunks and sometimes rewrite it myself. I’m very close to the point of also not reading existing code directly so in theory I should not worry about walls of text which could be useful for AI.</p>

<p>I also write PR summaries manually, mostly to force myself to understand what the PR does. I found many times I had a gap in understanding of a change while drafting the PR summary.</p>

<h3 id="for-personal">For Personal</h3>

<p>For learning algorithms or solving <a href="https://github.com/kunigami/programming-contests">programming puzzles</a>, I write 100% of the code. I even turn off AI auto-complete. One reason is to keep my programming skills sharp (it’s like hiking instead of driving), even if I might not need them in the future. The more important reason is that I find I learn better when I do things myself.</p>

<p>That’s also the reason why I write 100% of my blog posts manually. I use AI to <a href="https://github.com/kunigami/kunigami.github.io/blob/master/CLAUDE.md">correct typos and grammatical errors</a> but explicitly ask it not to rephrase things, even if it improves clarity. I want my blog to reflect my way of thinking, even if it’s gradually but increasingly being influenced by AI.</p>

<p>A few times I did ask for feedback from AI on how to convey my ideas better, especially when <a href="https://www.kuniga.me/books/">reviewing books</a>, which helped clarify my understanding.</p>

<h3 id="verum-ipsum-factum">Verum Ipsum Factum</h3>

<p>This is a quote by Giambattista Vico, an Italian philosopher, and it translates to <em>We only know what we make</em>. I read this in the book <a href="https://www.kuniga.me/books/2026/08/22/building-a-second-brain.html">Building a Second Brain</a> and this is the main motivation to keep doing things manually and that’s the main reason I blog.</p>

<p>In college, I recall we had a physics class that consisted in running experiments and using machines such as an oscilloscope. We worked in groups of 3, and each experiment we rotate on who did the manual work and who did the note taking, etc.</p>

<p>There was this one experiment with complicated steps and I wasn’t the one doing the manual work. I tried as hard as I could to memorize how my classmate did it, but wasn’t sure I had internalized it. As chance would have it, this was exactly the experiment we were asked to reproduce in the final exam and I couldn’t do it properly. Luckily I didn’t fail the course but it’s a lesson I’ll always remember.</p>

<h2 id="reading">Reading</h2>

<p>I’ve been relying more and more on AI for learning, instead of reading textbooks or Wikipedia. I still love <a href="https://www.kuniga.me/books/">reading books</a> for fun, but for difficult subjects I find it more effective to do everything through AI. I have specific learning patterns and some textbooks are so dense I waste time trying to decipher missing information (I spent <a href="https://www.kuniga.me/blog/2026/04/05/book-complex-analysis.html">2 years</a> reading a book on Complex Analysis).</p>

<p>AI is very useful for digging into details on demand too. I might not care about details of a specific topic but want to keep asking for details on others. Printed books often cannot provide such a tailored experience. AI makes it easier to follow my curiosity. If I had to buy textbooks or spend hours researching, I’d just not do it.</p>

<p>The one concern with using AI is that some say that true learning only comes with struggle. If AI makes it too easy to digest things, am I learning optimally? Writing posts explaining stuff (even if no one reads it!) is even more important now, because it tests my understanding and keeps me honest, but I don’t know if it’s enough.</p>

<h2 id="principles">Principles</h2>

<p>My guiding principle for when to use AI vs. not: what’s the most effective way to learn and understand? I don’t have qualms about relying on AI to do 100% of my grunt work, but I also don’t aim to blindly automate my work without learning anything in the process.</p>

<p>I’m fine to blindly let AI build tools to advance my projects but I’d like to be on top of the architecture and the algorithms that it uses, trade-offs taken, how the system deals with corner cases, etc.</p>

<p>I still think it’s valuable to know and understand things instead of being an <a href="https://www.kuniga.me/books/manna">AI puppet</a>, but I also recognize that the value of knowledge might shrink the more AI can expand the scope of what it can do. I’d still want to learn for fun, even if it doesn’t matter, the same way I enjoy reading <a href="https://www.kuniga.me/books/the-body">biology books</a> even though I likely won’t make use of it. I have more thoughts on this but I’ll leave it for its own post.</p>

<h2 id="conclusion">Conclusion</h2>

<p>To circle back to the start of the post, learning as a goal makes it easy to justify vibe-coding the JavaScript app to better understand Delaunay triangulation and KD-trees. My goal is not to learn how to write JavaScript apps, it’s to learn the algorithms themselves.</p>

<h2 id="related-posts">Related Posts</h2>

<p>In my <a href="https://www.kuniga.me/blog/2026/01/01/2025-in-review.htm">2025 in Review post</a>, I mentioned how I found learning history from Wikipedia instead of books more effective. I’ve since switched to using AI entirely for it. Most of my <a href="https://www.kuniga.me/docs/">notes</a> for <em>History</em> have been through sessions with ChatGPT.</p>

<p>In <a href="https://www.kuniga.me/blog/2026/04/04/the-weiertrass-p-function.html">The Weierstrass ℘-Function</a> also mention:</p>

<blockquote>
  <p>This proof is also not provided in Ahlfors (in any obvious way at least) and I relied entirely on ChatGPT to understand it! Like with learning history, I’m finding using ChatGPT a lot more effective at learning math: I can ask for it to explain me things in different angles and dig into different parts.</p>
</blockquote>

<p>This has been a consistent theme in many of my recent posts, so now that I have a dedicated post on this point I can stop repeating them or just link to here.</p>

<p><a href="https://www.kuniga.me/blog/2023/05/02/on-documentation.html">On Documentation</a> I asked the question: <em>Who Should Write (documentation)?</em>. Now we have a new option: AI. We should also consider a new point: who is the audience of documentation now? Humans or AI? Worth a separate post when my thoughts on this mature.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="opinion" />


        <summary type="html"><![CDATA[In my last post about KD-tree, I vibe-coded a JavaScript application to demonstrate visually, step-by-step, how to construct and query a KD-tree. Codex one-shotted it in a few minutes; I spent a few minutes linking it to the blog post but did not even take a look at the code. I’ve been using AI more and more both at work and for personal stuff but I also deliberately avoid using AI for specific tasks. I wanted to spend some time reflecting on this and document it.]]></summary>


    </entry>
  
    <entry>
      

      <title type="html">KD-Tree</title>
      <link href="https://www.kuniga.me/blog/2026/07/31/kd-tree.html" rel="alternate" type="text/html" title="KD-Tree" />
      <published>2026-07-31T00:00:00+00:00</published>
      <updated>2026-07-31T00:00:00+00:00</updated>
      <id>https://www.kuniga.me/blog/2026/07/31/kd-tree</id>
      
      
        <content type="html" xml:base="https://www.kuniga.me/blog/2026/07/31/kd-tree.html"><![CDATA[<!-- This needs to be define as included html because variables are not inherited by Jekyll pages -->

<figure class="image_float_left">
  <img src="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/kd-tree.png" alt="KD-Tree" />
</figure>

<p>Jon Bentley is an American computer scientist, famously known for his book <em>Programming Pearls</em>. He also came up with the data structure called k-d tree while an undergrad at Stanford and published it in a paper titled <em>Multidimensional Binary Search Trees Used for Associative Searching</em> in 1975.</p>

<p>In this post we study the kd-tree data structure, how to construct and perform queries on it. Then we provide an implementation in Python.</p>

<!--more-->

<h2 id="nearest-neighbors">Nearest Neighbors</h2>

<p>The “kd” in kd-tree stands for k-dimensional tree. We can think of it as a generalization of a binary search. In one version of the binary search problem we are given an array and a query value $q$. We need to find the element in the array that is the closest to $q$. This is called <em>nearest neighbors search</em>.</p>

<p>The problem kd-tree solves is essentially the same but the values are points in a k-dimensional space instead of a scalar (1d). The variant we’re interested in is the static one, i.e. we don’t allow inserting, updating or removing points.</p>

<p>To solve the 1d case, we consider the points in the line and let $m$ be the median point. If $m &lt; q$ then we can discard half of the points from the input, those having values less than $m$. If $m &gt; q$, we do the same for the other half. If $m = q$, we found the closest point. This property allows us to find the nearest neighbor in 1d in $O(\log n)$ time by keeping the points sorted.</p>

<p>For the kd case, there’s no single ordering, so what can we do?</p>

<h2 id="partition">Partition</h2>

<p>One way to see the search space of the 1d case is that of partitions organized as a binary search tree (BST). First we partition the points into 2: those with value less or equal than the median $m$, and those with value greater than $m$. Each partition has roughly the same number of points. We then subdivide each partition the same way, recursively, so we end up with a BST.</p>

<p>For the kd-tree we use the same idea but we “alternate” on which dimension to partition on. This is most intuitive for 2d: first we partition on the $x$ axis, i.e. we split the points by finding the median of the $x$ coordinate $x_m$ and have one partition contain all points with $x \le x_m$ and another the points with $x \gt x_m$.</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/kd-tree-app.png" alt="See caption." />
  <figcaption>Figure 1: Screenshot from the <a href="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/build.html">JavaScript applet</a> to compute a k-d tree step-by-step.</figcaption>
</figure>

<p>For the next level we partition on the $y$ axis instead. Geometrically each node in the 2nd level of the BST represents a quadrant containing roughly 1/4 of the points.</p>

<h2 id="searching">Searching</h2>

<p>Unfortunately, for dimensions greater than 1, knowing which partition a query point $q$ belongs to does not allow us to discard the other half. Here’s a counter-example:</p>

<figure class="center_children">
  <img src="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/counter-example.png" alt="See caption." />
  <figcaption>Figure 2: Counter-example in which the closest point to $q$ is not in any of the partitions it recursed to initially. Screenshot from the <a href="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/search.html">JavaScript applet</a> to search a query point step-by-step.</figcaption>
</figure>

<p>However, once we do find the partition of $q$, we do get an upper bound for the distance of the closest neighbor. This helps prune searches to the other partitions if there is not a lot of degeneracy.</p>

<p>So the idea of the algorithm is: traverse the BST to find the right partition and note the distance $d$ from $q$ to the point on that partition. As we backtrack, we ask “could this alternative branch contain the closest point?”.</p>

<p>We can quickly determine the <em>lower bound</em> between $q$ and any point of that branch by computing the distance between $q$ and the hyperplane (or line in the 2d case) which is $\abs{k_q - k_m}$ where $k$ is the dimension chosen for the partition and $k_m$ the median point. If this value is higher than $d$ we don’t need to keep searching. Otherwise we repeat the process there.</p>

<p>Once we reach the leaf on that subtree, we’ll potentially update $d$ and repeat the exact same process. In the worst case, we might end up visiting each leaf in this tree which would lead to a $O(n)$ complexity.</p>

<h2 id="implementation">Implementation</h2>

<p>We’ll implement a static, general dimension, kd-tree in Python. First we define some helper classes.</p>

<h3 id="data-structures">Data Structures</h3>

<p>We start with <code class="language-plaintext highlighter-rouge">Point</code>, which is a thin wrapper on top of <code class="language-plaintext highlighter-rouge">tuple</code>, that implements some utility operators:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="o">@</span><span class="n">dataclass</span><span class="p">(</span><span class="n">frozen</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
<span class="k">class</span> <span class="nc">Point</span><span class="p">:</span>
    <span class="n">data</span><span class="p">:</span> <span class="nb">tuple</span><span class="p">[</span><span class="nb">int</span><span class="p">,</span> <span class="p">...]</span>

    <span class="k">def</span> <span class="nf">__getitem__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">dim</span><span class="p">:</span> <span class="n">Dimension</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">[</span><span class="n">dim</span><span class="p">.</span><span class="n">v</span><span class="p">]</span>

    <span class="k">def</span> <span class="nf">__len__</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
        <span class="k">return</span> <span class="nb">len</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">__abs__</span><span class="p">(</span><span class="bp">self</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">float</span><span class="p">:</span>
        <span class="k">return</span> <span class="n">sqrt</span><span class="p">(</span><span class="nb">sum</span><span class="p">(</span><span class="n">x</span><span class="o">*</span><span class="n">x</span> <span class="k">for</span> <span class="n">x</span> <span class="ow">in</span> <span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">))</span>

    <span class="k">def</span> <span class="nf">__sub__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">other</span><span class="p">:</span> <span class="n">Point</span><span class="p">):</span>
        <span class="n">sub</span> <span class="o">=</span> <span class="nb">tuple</span><span class="p">(</span><span class="n">a</span><span class="o">-</span><span class="n">b</span> <span class="k">for</span> <span class="n">a</span><span class="p">,</span><span class="n">b</span> <span class="ow">in</span> <span class="nb">zip</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">data</span><span class="p">,</span> <span class="n">other</span><span class="p">.</span><span class="n">data</span><span class="p">))</span>
        <span class="k">return</span> <span class="n">Point</span><span class="p">(</span><span class="n">sub</span><span class="p">)</span></code></pre></figure>

<p>Where <code class="language-plaintext highlighter-rouge">Dimension</code> is just a simple wrapper to carry around the max dimension so we can get the next dimension in modular fashion:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="o">@</span><span class="n">dataclass</span><span class="p">(</span><span class="n">frozen</span><span class="o">=</span><span class="bp">True</span><span class="p">)</span>
<span class="k">class</span> <span class="nc">Dimension</span><span class="p">:</span>
    <span class="n">n</span><span class="p">:</span> <span class="nb">int</span>
    <span class="n">v</span><span class="p">:</span> <span class="nb">int</span> <span class="o">=</span> <span class="mi">0</span>

    <span class="k">def</span> <span class="nf">next</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="n">next_v</span> <span class="o">=</span> <span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">v</span> <span class="o">+</span> <span class="mi">1</span><span class="p">)</span> <span class="o">%</span> <span class="bp">self</span><span class="p">.</span><span class="n">n</span>
        <span class="k">return</span> <span class="n">Dimension</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">n</span><span class="p">,</span> <span class="n">next_v</span><span class="p">)</span></code></pre></figure>

<p>Since the kd-tree is a binary tree, the node is straightforward. We also add an <code class="language-plaintext highlighter-rouge">is_leaf()</code> to help with readability:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="o">@</span><span class="n">dataclass</span>
<span class="k">class</span> <span class="nc">KDNode</span><span class="p">:</span>
    <span class="n">pivot</span><span class="p">:</span> <span class="n">Point</span>
    <span class="n">left</span><span class="p">:</span> <span class="n">KDNode</span>
    <span class="n">right</span><span class="p">:</span> <span class="n">KDNode</span>

    <span class="k">def</span> <span class="nf">is_leaf</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">left</span> <span class="ow">is</span> <span class="bp">None</span> <span class="ow">and</span> <span class="bp">self</span><span class="p">.</span><span class="n">right</span> <span class="ow">is</span> <span class="bp">None</span></code></pre></figure>

<p>Finally we define a <code class="language-plaintext highlighter-rouge">View</code> class representing a sub-range, or a <a href="https://www.kuniga.me/blog/2025/01/25/vector-views-in-cpp.html">view</a>, of a list. This is because we plan to avoid copying the array and instead work with sub-ranges of it:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="o">@</span><span class="n">dataclass</span>
<span class="k">class</span> <span class="nc">View</span><span class="p">:</span>
    <span class="n">pts</span><span class="p">:</span> <span class="nb">list</span><span class="p">[</span><span class="n">Point</span><span class="p">]</span>
    <span class="n">lo</span><span class="p">:</span> <span class="nb">int</span> <span class="o">=</span> <span class="mi">0</span>
    <span class="n">hi</span><span class="p">:</span> <span class="nb">int</span> <span class="o">|</span> <span class="bp">None</span> <span class="o">=</span> <span class="bp">None</span>

    <span class="k">def</span> <span class="nf">__post_init__</span><span class="p">(</span><span class="bp">self</span><span class="p">):</span>
        <span class="k">if</span> <span class="bp">self</span><span class="p">.</span><span class="n">hi</span> <span class="ow">is</span> <span class="bp">None</span><span class="p">:</span>
            <span class="nb">object</span><span class="p">.</span><span class="n">__setattr__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="s">'hi'</span><span class="p">,</span> <span class="nb">len</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">)</span> <span class="o">-</span> <span class="mi">1</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">range</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">lo</span><span class="p">,</span> <span class="n">hi</span><span class="p">):</span>
        <span class="k">return</span> <span class="n">View</span><span class="p">(</span><span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">,</span> <span class="n">lo</span><span class="p">,</span> <span class="n">hi</span><span class="p">)</span>

    <span class="k">def</span> <span class="nf">swap</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">i</span><span class="p">,</span> <span class="n">j</span><span class="p">):</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">[</span><span class="n">i</span><span class="p">],</span> <span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">[</span><span class="n">j</span><span class="p">]</span> <span class="o">=</span> <span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">[</span><span class="n">j</span><span class="p">],</span> <span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">[</span><span class="n">i</span><span class="p">]</span>

    <span class="k">def</span> <span class="nf">__getitem__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">i</span><span class="p">:</span> <span class="nb">int</span><span class="p">):</span>
        <span class="k">return</span> <span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">[</span><span class="n">i</span><span class="p">]</span>

    <span class="k">def</span> <span class="nf">__setitem__</span><span class="p">(</span><span class="bp">self</span><span class="p">,</span> <span class="n">i</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">p</span><span class="p">:</span> <span class="n">Point</span><span class="p">):</span>
        <span class="bp">self</span><span class="p">.</span><span class="n">pts</span><span class="p">[</span><span class="n">i</span><span class="p">]</span> <span class="o">=</span> <span class="n">p</span></code></pre></figure>

<h3 id="median">Median</h3>

<p>To construct the kd-tree we need to find the median point, i.e. a point such that half of the points in the set are smaller than it, and half are greater for a particular dimension. We can use the quick-select algorithm for this:</p>

<ul>
  <li>Choose a random element from the array. Call it <code class="language-plaintext highlighter-rouge">pivot</code></li>
  <li>Rearrange the array so that all elements smaller than <code class="language-plaintext highlighter-rouge">pivot</code> appear before it and all elements greater than it appear after.</li>
  <li>After this, if <code class="language-plaintext highlighter-rouge">pivot</code> is towards the beginning of the array, repeat for the right side of the array. If towards the end, repeat for the left side. The goal is to eventually have <code class="language-plaintext highlighter-rouge">pivot</code> appear at the middle of the array.</li>
</ul>

<p>The <code class="language-plaintext highlighter-rouge">partition()</code> function below implements the second bullet point:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">partition</span><span class="p">(</span><span class="n">pts</span><span class="p">:</span> <span class="n">View</span><span class="p">,</span> <span class="n">p</span><span class="p">:</span> <span class="nb">int</span><span class="p">,</span> <span class="n">dim</span><span class="p">:</span> <span class="n">Dimension</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
    <span class="s">"""
    Lomuto partition. Rearrange pts[lo:hi] so that
    if i &lt; p, then pts[i][dim] &lt;= pts[p][dim]
    if i &gt; p, then pts[i][dim] &gt; pts[p][dim]
    """</span>
    <span class="n">lo</span><span class="p">,</span> <span class="n">hi</span> <span class="o">=</span> <span class="n">pts</span><span class="p">.</span><span class="n">lo</span><span class="p">,</span> <span class="n">pts</span><span class="p">.</span><span class="n">hi</span>
    <span class="n">pivot</span> <span class="o">=</span> <span class="n">pts</span><span class="p">[</span><span class="n">p</span><span class="p">]</span>
    <span class="n">pts</span><span class="p">.</span><span class="n">swap</span><span class="p">(</span><span class="n">p</span><span class="p">,</span> <span class="n">hi</span><span class="p">)</span>
    <span class="n">store</span> <span class="o">=</span> <span class="n">lo</span>

    <span class="k">for</span> <span class="n">i</span> <span class="ow">in</span> <span class="nb">range</span><span class="p">(</span><span class="n">lo</span><span class="p">,</span> <span class="n">hi</span><span class="p">):</span>
        <span class="k">if</span> <span class="n">pts</span><span class="p">[</span><span class="n">i</span><span class="p">][</span><span class="n">dim</span><span class="p">]</span> <span class="o">&lt;=</span> <span class="n">pivot</span><span class="p">[</span><span class="n">dim</span><span class="p">]:</span>
            <span class="n">pts</span><span class="p">.</span><span class="n">swap</span><span class="p">(</span><span class="n">store</span><span class="p">,</span> <span class="n">i</span><span class="p">)</span>
            <span class="n">store</span> <span class="o">+=</span> <span class="mi">1</span>

    <span class="n">pts</span><span class="p">.</span><span class="n">swap</span><span class="p">(</span><span class="n">store</span><span class="p">,</span> <span class="n">hi</span><span class="p">)</span>
    <span class="k">return</span> <span class="n">store</span></code></pre></figure>

<p>The first and third points are implemented by the outer function:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">median_index</span><span class="p">(</span><span class="n">pts</span><span class="p">:</span> <span class="n">View</span><span class="p">,</span> <span class="n">dim</span><span class="p">:</span> <span class="n">Dimension</span><span class="p">)</span> <span class="o">-&gt;</span> <span class="nb">int</span><span class="p">:</span>
    <span class="n">lo</span><span class="p">,</span> <span class="n">hi</span> <span class="o">=</span> <span class="n">pts</span><span class="p">.</span><span class="n">lo</span><span class="p">,</span> <span class="n">pts</span><span class="p">.</span><span class="n">hi</span>
    <span class="n">k</span> <span class="o">=</span> <span class="n">lo</span> <span class="o">+</span> <span class="p">(</span><span class="n">hi</span> <span class="o">-</span> <span class="n">lo</span><span class="p">)</span> <span class="o">//</span> <span class="mi">2</span>
    <span class="k">while</span> <span class="bp">True</span><span class="p">:</span>
        <span class="k">if</span> <span class="n">lo</span> <span class="o">==</span> <span class="n">hi</span><span class="p">:</span>
            <span class="k">return</span> <span class="n">lo</span>
        <span class="n">p</span> <span class="o">=</span> <span class="n">partition</span><span class="p">(</span><span class="n">pts</span><span class="p">.</span><span class="nb">range</span><span class="p">(</span><span class="n">lo</span><span class="p">,</span> <span class="n">hi</span><span class="p">),</span> <span class="n">random</span><span class="p">.</span><span class="n">randint</span><span class="p">(</span><span class="n">lo</span><span class="p">,</span> <span class="n">hi</span><span class="p">),</span> <span class="n">dim</span><span class="p">)</span>
        <span class="k">if</span> <span class="n">p</span> <span class="o">==</span> <span class="n">k</span><span class="p">:</span>
            <span class="k">return</span> <span class="n">p</span>
        <span class="k">elif</span> <span class="n">p</span> <span class="o">&gt;</span> <span class="n">k</span><span class="p">:</span>
            <span class="n">hi</span> <span class="o">=</span> <span class="n">p</span> <span class="o">-</span> <span class="mi">1</span>
        <span class="k">else</span><span class="p">:</span>
            <span class="n">lo</span> <span class="o">=</span> <span class="n">p</span> <span class="o">+</span> <span class="mi">1</span></code></pre></figure>

<p>It’s possible to show this algorithm is $O(n)$ on average but $O(n^2)$ in the worst case.</p>

<h3 id="building">Building</h3>

<p><a href="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/build.html">Open the interactive applet that builds a kd-tree</a>.</p>

<p>Once we have the function to find the median, building the kd-tree is very simple:</p>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">build_kd_tree</span><span class="p">(</span><span class="n">pts</span><span class="p">,</span> <span class="n">dim</span><span class="p">):</span>
    <span class="k">if</span> <span class="n">pts</span><span class="p">.</span><span class="n">lo</span> <span class="o">&gt;</span> <span class="n">pts</span><span class="p">.</span><span class="n">hi</span><span class="p">:</span>
        <span class="k">return</span> <span class="bp">None</span>

    <span class="n">mi</span> <span class="o">=</span> <span class="n">median_index</span><span class="p">(</span><span class="n">pts</span><span class="p">,</span> <span class="n">dim</span><span class="p">)</span>

    <span class="n">left</span> <span class="o">=</span> <span class="n">build_kd_tree</span><span class="p">(</span><span class="n">pts</span><span class="p">.</span><span class="nb">range</span><span class="p">(</span><span class="n">pts</span><span class="p">.</span><span class="n">lo</span><span class="p">,</span> <span class="n">mi</span> <span class="o">-</span> <span class="mi">1</span><span class="p">),</span> <span class="n">dim</span><span class="p">.</span><span class="nb">next</span><span class="p">())</span>
    <span class="n">right</span> <span class="o">=</span> <span class="n">build_kd_tree</span><span class="p">(</span><span class="n">pts</span><span class="p">.</span><span class="nb">range</span><span class="p">(</span><span class="n">mi</span> <span class="o">+</span> <span class="mi">1</span><span class="p">,</span> <span class="n">pts</span><span class="p">.</span><span class="n">hi</span><span class="p">),</span> <span class="n">dim</span><span class="p">.</span><span class="nb">next</span><span class="p">())</span>

    <span class="k">return</span> <span class="n">KDNode</span><span class="p">(</span><span class="n">pivot</span><span class="o">=</span><span class="n">pts</span><span class="p">[</span><span class="n">mi</span><span class="p">],</span> <span class="n">left</span><span class="o">=</span><span class="n">left</span><span class="p">,</span> <span class="n">right</span><span class="o">=</span><span class="n">right</span><span class="p">)</span></code></pre></figure>

<h3 id="searching-1">Searching</h3>

<p><a href="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/search.html">Open the interactive nearest-neighbor search</a>.</p>

<p>Search is relatively simple too, when traversing a node:</p>

<ul>
  <li>Check if the current pivot is the closest point.</li>
  <li>Recurse on the query point’s partition.</li>
  <li>If the lower bound from the other partition is smaller than what we have so far, recurse on the other partition as well.</li>
</ul>

<figure class="highlight"><pre><code class="language-python" data-lang="python"><span class="k">def</span> <span class="nf">query_kd_tree</span><span class="p">(</span><span class="n">node</span><span class="p">,</span> <span class="n">q</span><span class="p">,</span> <span class="n">dim</span><span class="p">,</span> <span class="n">ub</span> <span class="o">=</span> <span class="n">inf</span><span class="p">):</span>
    <span class="k">if</span> <span class="ow">not</span> <span class="n">node</span><span class="p">:</span>
        <span class="k">return</span> <span class="bp">None</span>

    <span class="n">p</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">pivot</span>

    <span class="k">if</span> <span class="n">node</span><span class="p">.</span><span class="n">is_leaf</span><span class="p">():</span>
        <span class="k">return</span> <span class="n">p</span>

    <span class="k">if</span> <span class="n">q</span><span class="p">[</span><span class="n">dim</span><span class="p">]</span> <span class="o">&lt;=</span> <span class="n">p</span><span class="p">[</span><span class="n">dim</span><span class="p">]:</span>
        <span class="n">main</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">left</span>
        <span class="n">other</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">right</span>
    <span class="k">else</span><span class="p">:</span>
        <span class="n">main</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">right</span>
        <span class="n">other</span> <span class="o">=</span> <span class="n">node</span><span class="p">.</span><span class="n">left</span>

    <span class="n">c</span> <span class="o">=</span> <span class="bp">None</span>

    <span class="c1"># pivot is a candidate
</span>    <span class="k">if</span> <span class="n">dist</span><span class="p">(</span><span class="n">q</span><span class="p">,</span> <span class="n">p</span><span class="p">)</span> <span class="o">&lt;</span> <span class="n">ub</span><span class="p">:</span>
        <span class="n">c</span> <span class="o">=</span> <span class="n">p</span>
        <span class="n">ub</span> <span class="o">=</span> <span class="n">dist</span><span class="p">(</span><span class="n">q</span><span class="p">,</span> <span class="n">p</span><span class="p">)</span>

    <span class="c1"># main branch
</span>    <span class="n">c1</span> <span class="o">=</span> <span class="n">query_kd_tree</span><span class="p">(</span><span class="n">main</span><span class="p">,</span> <span class="n">q</span><span class="p">,</span> <span class="n">dim</span><span class="p">.</span><span class="nb">next</span><span class="p">(),</span> <span class="n">ub</span><span class="p">)</span>
    <span class="k">if</span> <span class="n">dist</span><span class="p">(</span><span class="n">q</span><span class="p">,</span> <span class="n">c1</span><span class="p">)</span> <span class="o">&lt;</span> <span class="n">ub</span><span class="p">:</span>
        <span class="n">c</span> <span class="o">=</span> <span class="n">c1</span>
        <span class="n">ub</span> <span class="o">=</span> <span class="n">dist</span><span class="p">(</span><span class="n">q</span><span class="p">,</span> <span class="n">c1</span><span class="p">)</span>

    <span class="c1"># minimum distance we can expect to find
</span>    <span class="c1"># on the other branch
</span>    <span class="n">lb</span> <span class="o">=</span> <span class="nb">abs</span><span class="p">(</span><span class="n">q</span><span class="p">[</span><span class="n">dim</span><span class="p">]</span> <span class="o">-</span> <span class="n">p</span><span class="p">[</span><span class="n">dim</span><span class="p">])</span>
    <span class="k">if</span> <span class="n">lb</span> <span class="o">&lt;</span> <span class="n">ub</span><span class="p">:</span>
        <span class="n">c2</span> <span class="o">=</span> <span class="n">query_kd_tree</span><span class="p">(</span><span class="n">other</span><span class="p">,</span> <span class="n">q</span><span class="p">,</span> <span class="n">dim</span><span class="p">.</span><span class="nb">next</span><span class="p">(),</span> <span class="n">ub</span><span class="p">)</span>
        <span class="k">if</span> <span class="n">dist</span><span class="p">(</span><span class="n">q</span><span class="p">,</span> <span class="n">c2</span><span class="p">)</span> <span class="o">&lt;</span> <span class="n">ub</span><span class="p">:</span>
            <span class="n">c</span> <span class="o">=</span> <span class="n">c2</span>

    <span class="k">return</span> <span class="n">c</span></code></pre></figure>

<p>In the best case the search behaves like binary search and it takes only $O(\log n)$ operations but in degenerate cases it can be $O(n)$ (i.e. all nodes of the tree need to be searched).</p>

<p>The full code is on <a href="https://github.com/kunigami/kunigami.github.io/blob/master/blog/code/2026-07-31-kd-tree/kd-tree.py">Github</a>.</p>

<h3 id="experiments">Experiments</h3>

<p>I ran this code with random inputs of 10,000 points with 100 query points. The average number of nodes visited was 34.59 ± 15.61 which is logarithmic on the input size.</p>

<h2 id="conclusion">Conclusion</h2>

<p>Kd-tree is on my list of data structures or algorithms I had heard of, possibly used some existing implementation, but never took the time to study in detail. Another recent example is the <a href="https://www.kuniga.me/blog/2026/06/20/delaunay-triangulation.html">Delaunay Triangulation</a>.</p>

<p>One thing I skipped for this post is any theoretical analysis that shows how kd-trees perform on average.</p>

<p>The <a href="https://www.kuniga.me/resources/blog/2026-07-31-kd-tree/build.html">JavaScript applet</a> was vibe-coded using Codex, which one-shot it (after finding a bug in my implementation) in less than 5 minutes, with this prompt verbatim:</p>

<blockquote>
  <p>I want to build a JavaScript self-contained app that shows how the kd-tree algoritm works. I’m going to use this implementation: /Users/kunigami/workspace/python/kd-tree/kd-tree.py . The idea: use svg to draw a 512 x 512 box, generate 13 random points. It should render the dividing line from the pivot. On the left, render a binary tree. Inside the node show the <code class="language-plaintext highlighter-rouge">pivot</code> point. Ok? We want to do this interactive, so we should have a parameter step. the rendering should go only up to step N while doing a pre-order ‘traversal’. Then we add buttons prev / next which increment N and re-render. Feasible?</p>
</blockquote>

<p>This was provided more or less on the spot: you can see I added details after such as the buttons, so it wasn’t a well thought out prompt. I was astonished by the result. I have been using Claude Code to generate code and sometimes it does generate entire code features for me, but maybe because this one was visual, I felt more impressed!</p>

<p>I’m pretty sure there are many such applets out there from which the model can learn, so it probably helped in it being so successful.</p>

<p>It would have taken me hours to implement this and I wouldn’t have found it worth spending the extra time. With AI I can not only enrich my posts with these visualizations but build these <em>while</em> studying to better understand things.</p>

<p>It also built the search version of it in one shot. I need to raise my expectations for what LLMs can accomplish. In <a href="https://www.kuniga.me/blog/2026/06/20/delaunay-triangulation.html">Delaunay Triangulation</a> I said:</p>

<blockquote>
  <p>It did cross my mind to write a JavaScript-based on for the Bowyer-Watson algorithm, especially if Claude can do most of the implementation, but it would still take some work to test, polish and read the code, so I decided to pass.</p>
</blockquote>

<h2 id="related-posts">Related Posts</h2>

<p>Finding the median of a set of points efficiently is an interesting problem. <a href="https://www.kuniga.me/blog/2021/11/29/t-digest.html">T-Digest in Python</a> tackles this statistical problem from a different angle: how to compute the P50 (and other percentiles) online, i.e. without storing all points explicitly.</p>

<p>Binary search trees, such as the red-black tree, implement the 1d version of the kd-tree but allow for efficient insertion and removal. In <a href="https://www.kuniga.me/blog/2019/04/12/consistent-hashing.html">Consistent Hashing</a> we use Rust’s implementation of a red-black tree to efficiently search the closest server of a given key in the “ring”.</p>

<p><a href="https://www.kuniga.me/blog/2012/09/25/skip-lists-in-python.html">Skip Lists</a> is a probabilistic alternative to binary search trees for range search. A natural question is: can skip lists be generalized to k dimensions? Eppstein et al. have papers on those: <a href="https://arxiv.org/abs/cs/0507049">The Skip Quadtree</a> and <a href="https://arxiv.org/abs/cs/0507050">Skip-webs</a>.</p>

<p>Another multi-dimensional probabilistic structure for nearest neighbor search is called <a href="https://en.wikipedia.org/wiki/Hierarchical_navigable_small_world">Hierarchical Navigable Small World</a>, which is apparently very popular for vector search, an important aspect of modern ML.</p>]]></content>


      <author>
          <name>Guilherme Kunigami</name>
        
        
      </author>


          <category term="blog" />


        <category term="computational geometry" />


        <summary type="html"><![CDATA[Jon Bentley is an American computer scientist, famously known for his book Programming Pearls. He also came up with the data structure called k-d tree while an undergrad at Stanford and published it in a paper titled Multidimensional Binary Search Trees Used for Associative Searching in 1975. In this post we study the kd-tree data structure, how to construct and perform queries on it. Then we provide an implementation in Python.]]></summary>


    </entry>
  
</feed>